
id stringlengths 18 24 | number int64 2 8.48k | title stringlengths 1 290 | body stringlengths 0 228k | state stringclasses 2
values | createdAt timestamp[s]date 2020-04-14 18:18:51 2026-08-13 03:02:44 | updatedAt timestamp[s]date 2020-04-29 09:23:05 2026-08-15 04:47:12 | closedAt timestamp[s]date 2020-04-29 09:23:05 2026-07-28 10:29:56 ⌀ | url stringlengths 48 51 | author dict | labels dict | comments listlengths 0 30 |
|---|---|---|---|---|---|---|---|---|---|---|---|
MDU6SXNzdWU2NjA2NTQwMTM= | 414 | from_dict delete? | AttributeError: type object 'Dataset' has no attribute 'from_dict' | CLOSED | 2020-07-19T07:08:36 | 2020-07-21T02:21:17 | 2020-07-21T02:21:17 | https://github.com/huggingface/datasets/issues/414 | {
"login": "hackerxiaobai"
} | {
"nodes": []
} | [
"`from_dict` was added in #350 that was unfortunately not included in the 0.3.0 release. It's going to be included in the next release that will be out pretty soon though.\r\nRight now if you want to use `from_dict` you have to install the package from the master branch\r\n```\r\npip install git+https://github.com/... |
MDU6SXNzdWU2NjAwNjM2NTU= | 413 | Is there a way to download only NQ dev? | Maybe I missed that in the docs, but is there a way to only download the dev set of natural questions (~1 GB)?
As we want to benchmark QA models on different datasets, I would like to avoid downloading the 41GB of training data.
I tried
```
dataset = nlp.load_dataset('natural_questions', split="validation", bea... | CLOSED | 2020-07-18T10:28:23 | 2022-02-11T09:50:21 | 2022-02-11T09:50:21 | https://github.com/huggingface/datasets/issues/413 | {
"login": "tholor"
} | {
"nodes": []
} | [
"Unfortunately it's not possible to download only the dev set of NQ.\r\n\r\nI think we could add a way to download only the test set by adding a custom configuration to the processing script though.",
"Ok, got it. I think this could be a valuable feature - especially for large datasets like NQ, but potentially al... |
MDU6SXNzdWU2NjAwNDcxMzk= | 412 | Unable to load XTREME dataset from disk | Hi 🤗 team!
## Description of the problem
Following the [docs](https://huggingface.co/nlp/loading_datasets.html?highlight=xtreme#manually-downloading-files) I'm trying to load the `PAN-X.fr` dataset from the [XTREME](https://github.com/google-research/xtreme) benchmark.
I have manually downloaded the `AmazonPho... | CLOSED | 2020-07-18T09:55:00 | 2020-07-21T08:15:44 | 2020-07-21T08:15:44 | https://github.com/huggingface/datasets/issues/412 | {
"login": "lewtun"
} | {
"nodes": []
} | [
"Hi @lewtun, you have to provide the full path to the downloaded file for example `/home/lewtum/..`",
"I was able to repro. Opening a PR to fix that.\r\nThanks for reporting this issue !",
"Thanks for the rapid fix @lhoestq!"
] |
MDU6SXNzdWU2NTkxMjg2MTE= | 409 | train_test_split error: 'dict' object has no attribute 'deepcopy' | `train_test_split` is giving me an error when I try and call it:
`'dict' object has no attribute 'deepcopy'`
## To reproduce
```
dataset = load_dataset('glue', 'mrpc', split='train')
dataset = dataset.train_test_split(test_size=0.2)
```
## Full Stacktrace
```
-------------------------------------------... | CLOSED | 2020-07-17T10:36:28 | 2020-07-21T14:34:52 | 2020-07-21T14:34:52 | https://github.com/huggingface/datasets/issues/409 | {
"login": "morganmcg1"
} | {
"nodes": []
} | [
"It was fixed in 2ddd18d139d3047c9c3abe96e1e7d05bb360132c.\r\nCould you pull the latest changes from master @morganmcg1 ?",
"Thanks @lhoestq, works fine now!"
] |
MDU6SXNzdWU2NTg2NzI3MzY= | 407 | MissingBeamOptions for Wikipedia 20200501.en | There may or may not be a regression for the pre-processed Wikipedia dataset. This was working fine 10 commits ago (without having Apache Beam available):
```
nlp.load_dataset('wikipedia', "20200501.en", split='train')
```
And now, having pulled master, I get:
```
Downloading and preparing dataset wikipedia... | CLOSED | 2020-07-16T23:48:03 | 2021-01-12T11:41:16 | 2020-07-17T14:24:28 | https://github.com/huggingface/datasets/issues/407 | {
"login": "mitchellgordon95"
} | {
"nodes": []
} | [
"Fixed. Could you try again @mitchellgordon95 ?\r\nIt was due a file not being updated on S3.\r\n\r\nWe need to make sure all the datasets scripts get updated properly @julien-c ",
"Works for me! Thanks.",
"I found the same issue with almost any language other than English. (For English, it works). Will someone... |
MDU6SXNzdWU2NTg1ODE3NjQ= | 406 | Faster Shuffling? | Consider shuffling bookcorpus:
```
dataset = nlp.load_dataset('bookcorpus', split='train')
dataset.shuffle()
```
According to tqdm, this will take around 2.5 hours on my machine to complete (even with the faster version of select from #405). I've also tried with `keep_in_memory=True` and `writer_batch_size=1000`... | CLOSED | 2020-07-16T21:21:53 | 2023-08-16T09:52:39 | 2020-09-07T14:45:25 | https://github.com/huggingface/datasets/issues/406 | {
"login": "mitchellgordon95"
} | {
"nodes": []
} | [
"I think the slowness here probably come from the fact that we are copying from and to python.\r\n\r\n@lhoestq for all the `select`-based methods I think we should stay in Arrow format and update the writer so that it can accept Arrow tables or batches as well. What do you think?",
"> @lhoestq for all the `select... |
MDU6SXNzdWU2NTc0NTQ5ODM= | 395 | Memory issue when doing select | As noticed in #389, the following code loads the entire wikipedia in memory.
```python
import nlp
w = nlp.load_dataset("wikipedia", "20200501.en", split="train")
w.select([0])
```
This is caused by [this line](https://github.com/huggingface/nlp/blob/master/src/nlp/arrow_dataset.py#L626) for some reason, that ... | CLOSED | 2020-07-15T15:43:38 | 2020-07-16T08:07:31 | 2020-07-16T08:07:31 | https://github.com/huggingface/datasets/issues/395 | {
"login": "lhoestq"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NTY3MDc0OTc= | 388 | 🐛 [Dataset] Cannot download wmt14, wmt15 and wmt17 | 1. I try downloading `wmt14`, `wmt15`, `wmt17`, `wmt19` with the following code:
```
nlp.load_dataset('wmt14','de-en')
nlp.load_dataset('wmt15','de-en')
nlp.load_dataset('wmt17','de-en')
nlp.load_dataset('wmt19','de-en')
```
The code runs but the download speed is **extremely slow**, the same behaviour is not ob... | CLOSED | 2020-07-14T15:36:41 | 2022-10-04T18:01:28 | 2022-10-04T18:01:28 | https://github.com/huggingface/datasets/issues/388 | {
"login": "SamuelCahyawijaya"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"similar slow download speed here for nlp.load_dataset('wmt14', 'fr-en')\r\n`\r\nDownloading: 100%|██████████████████████████████████████████████████████████| 658M/658M [1:00:42<00:00, 181kB/s]\r\nDownloading: 100%|██████████████████████████████████████████████████████████| 918M/918M [1:39:38<00:00, 154kB/s]\r\nDow... |
MDU6SXNzdWU2NTYzNjEzNTc= | 387 | Conversion through to_pandas output numpy arrays for lists instead of python objects | In a related question, the conversion through to_pandas output numpy arrays for the lists instead of python objects.
Here is an example:
```python
>>> dataset._data.slice(key, 1).to_pandas().to_dict("list")
{'sentence1': ['Amrozi accused his brother , whom he called " the witness " , of deliberately distorting hi... | CLOSED | 2020-07-14T06:24:01 | 2020-07-17T11:37:00 | 2020-07-17T11:37:00 | https://github.com/huggingface/datasets/issues/387 | {
"login": "thomwolf"
} | {
"nodes": []
} | [
"To convert from arrow type we have three options: to_numpy, to_pandas and to_pydict/to_pylist.\r\n\r\n- to_numpy and to_pandas return numpy arrays instead of lists but are very fast.\r\n- to_pydict/to_pylist can be 100x slower and become the bottleneck for reading data, but at least they return lists.\r\n\r\nMaybe... |
MDU6SXNzdWU2NTUyOTA0ODI= | 382 | 1080 | CLOSED | 2020-07-11T22:29:07 | 2020-07-11T22:49:38 | 2020-07-11T22:49:38 | https://github.com/huggingface/datasets/issues/382 | {
"login": "saq194"
} | {
"nodes": []
} | [] | |
MDU6SXNzdWU2NTUyNzcxMTk= | 381 | NLp | CLOSED | 2020-07-11T20:50:14 | 2020-07-11T20:50:39 | 2020-07-11T20:50:39 | https://github.com/huggingface/datasets/issues/381 | {
"login": "Spartanthor"
} | {
"nodes": []
} | [] | |
MDU6SXNzdWU2NTUyMjYzMTY= | 378 | [dataset] Structure of MLQA seems unecessary nested | The features of the MLQA dataset comprise several nested dictionaries with a single element inside (for `questions` and `ids`): https://github.com/huggingface/nlp/blob/master/datasets/mlqa/mlqa.py#L90-L97
Should we keep this @mariamabarham @patrickvonplaten? Was this added for compatibility with tfds?
```python
... | CLOSED | 2020-07-11T15:16:08 | 2020-07-15T16:17:20 | 2020-07-15T16:17:20 | https://github.com/huggingface/datasets/issues/378 | {
"login": "thomwolf"
} | {
"nodes": []
} | [
"Same for the RACE dataset: https://github.com/huggingface/nlp/blob/master/datasets/race/race.py\r\n\r\nShould we scan all the datasets to remove this pattern of un-necessary nesting?",
"You're right, I think we don't need to use the nested dictionary. \r\n"
] |
MDU6SXNzdWU2NTUyMTU3OTA= | 377 | Iyy!!! | CLOSED | 2020-07-11T14:11:07 | 2020-07-11T14:30:51 | 2020-07-11T14:30:51 | https://github.com/huggingface/datasets/issues/377 | {
"login": "ajinomoh"
} | {
"nodes": []
} | [] | |
MDU6SXNzdWU2NTUwNDc4MjY= | 376 | to_pandas conversion doesn't always work | For some complex nested types, the conversion from Arrow to python dict through pandas doesn't seem to be possible.
Here is an example using the official SQUAD v2 JSON file.
This example was found while investigating #373.
```python
>>> squad = load_dataset('json', data_files={nlp.Split.TRAIN: ["./train-v2.0.... | CLOSED | 2020-07-10T21:33:31 | 2022-10-04T18:05:39 | 2022-10-04T18:05:39 | https://github.com/huggingface/datasets/issues/376 | {
"login": "thomwolf"
} | {
"nodes": []
} | [
"**Edit**: other topic previously in this message moved to a new issue: https://github.com/huggingface/nlp/issues/387",
"Could you try to update pyarrow to >=0.17.0 ? It should fix the `to_pandas` bug\r\n\r\nAlso I'm not sure that structures like list<struct> are fully supported in the lib (none of the datasets u... |
MDU6SXNzdWU2NTUwMjMzMDc= | 375 | TypeError when computing bertscore | Hi,
I installed nlp 0.3.0 via pip, and my python version is 3.7.
When I tried to compute bertscore with the code:
```
import nlp
bertscore = nlp.load_metric('bertscore')
# load hyps and refs
...
print (bertscore.compute(hyps, refs, lang='en'))
```
I got the following error.
```
Traceback (most rece... | CLOSED | 2020-07-10T20:37:44 | 2022-06-01T15:15:59 | 2022-06-01T15:15:59 | https://github.com/huggingface/datasets/issues/375 | {
"login": "willywsm1013"
} | {
"nodes": []
} | [
"I am not able to reproduce this issue on my side.\r\nCould you give us more details about the inputs you used ?\r\n\r\nI do get another error though:\r\n```\r\n~/.virtualenvs/hf-datasets/lib/python3.7/site-packages/bert_score/utils.py in bert_cos_score_idf(model, refs, hyps, tokenizer, idf_dict, verbose, batch_siz... |
MDU6SXNzdWU2NTQ4NDUxMzM= | 373 | Segmentation fault when loading local JSON dataset as of #372 | The last issue was closed (#369) once the #372 update was merged. However, I'm still not able to load a SQuAD formatted JSON file. Instead of the previously recorded pyarrow error, I now get a segmentation fault.
```
dataset = nlp.load_dataset('json', data_files={nlp.Split.TRAIN: ["./datasets/train-v2.0.json"]}, f... | CLOSED | 2020-07-10T15:04:25 | 2022-10-04T18:05:47 | 2022-10-04T18:05:47 | https://github.com/huggingface/datasets/issues/373 | {
"login": "vegarab"
} | {
"nodes": []
} | [
"I've seen this sort of thing before -- it might help to delete the directory -- I've also noticed that there is an error with the json Dataloader for any data I've tried to load. I've replaced it with this, which skips over the data feature population step:\r\n\r\n\r\n```python\r\nimport os\r\n\r\nimport pyarrow.j... |
MDU6SXNzdWU2NTQxODY4OTA= | 369 | can't load local dataset: pyarrow.lib.ArrowInvalid: straddling object straddles two block boundaries | Trying to load a local SQuAD-formatted dataset (from a JSON file, about 60MB):
```
dataset = nlp.load_dataset(path='json', data_files={nlp.Split.TRAIN: ["./path/to/file.json"]})
```
causes
```
Traceback (most recent call last):
File "dataloader.py", line 9, in <module>
["./path/to/file.json"]})
File "/... | CLOSED | 2020-07-09T16:16:53 | 2020-12-15T23:07:22 | 2020-07-10T14:52:06 | https://github.com/huggingface/datasets/issues/369 | {
"login": "vegarab"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"I am able to reproduce this with the official SQuAD `train-v2.0.json` file downloaded directly from https://rajpurkar.github.io/SQuAD-explorer/",
"I am facing this issue in transformers library 3.0.2 while reading a csv using datasets.\r\nIs this fixed in latest version? \r\nI updated the latest version 4.0.1 bu... |
MDU6SXNzdWU2NTQwODcyNTE= | 368 | load_metric can't acquire lock anymore | I can't load metric (glue) anymore after an error in a previous run. I even removed the whole cache folder `/home/XXX/.cache/huggingface/`, and the issue persisted. What are the steps to fix this?
Traceback (most recent call last):
File "/home/XXX/miniconda3/envs/ML-DL-py-3.7/lib/python3.7/site-packages/n... | CLOSED | 2020-07-09T14:04:09 | 2020-07-10T13:45:20 | 2020-07-10T13:45:20 | https://github.com/huggingface/datasets/issues/368 | {
"login": "ydshieh"
} | {
"nodes": []
} | [
"I found that, in the same process (or the same interactive session), if I do\r\n\r\nimport nlp\r\n\r\nm1 = nlp.load_metric('glue', 'mrpc')\r\nm2 = nlp.load_metric('glue', 'sst2')\r\n\r\nI will get the same error `ValueError: Cannot acquire lock, caching file might be used by another process, you should setup a uni... |
MDU6SXNzdWU2NTM4NDU5NjQ= | 365 | How to augment data ? | Is there any clean way to augment data ?
For now my work-around is to use batched map, like this :
```python
def aug(samples):
# Simply copy the existing data to have x2 amount of data
for k, v in samples.items():
samples[k].extend(v)
return samples
dataset = dataset.map(aug, batched=T... | CLOSED | 2020-07-09T07:52:37 | 2020-07-10T09:12:07 | 2020-07-10T08:22:15 | https://github.com/huggingface/datasets/issues/365 | {
"login": "astariul"
} | {
"nodes": []
} | [
"Using batched map is probably the easiest way at the moment.\r\nWhat kind of augmentation would you like to do ?",
"Some samples in the dataset are too long, I want to divide them in several samples.",
"Using batched map is the way to go then.\r\nWe'll make it clearer in the docs that map could be used for aug... |
MDU6SXNzdWU2NTM3NjYyNDU= | 362 | [dateset subset missing] xtreme paws-x | I tried nlp.load_dataset('xtreme', 'PAWS-X.es') but get the value error
It turns out that the subset for Spanish is missing
https://github.com/google-research-datasets/paws/tree/master/pawsx | CLOSED | 2020-07-09T05:04:54 | 2020-07-09T12:38:42 | 2020-07-09T12:38:42 | https://github.com/huggingface/datasets/issues/362 | {
"login": "cosmeowpawlitan"
} | {
"nodes": []
} | [
"You're right, thanks for pointing it out. We will update it "
] |
MDU6SXNzdWU2NTM3NTczNzY= | 361 | 🐛 [Metrics] ROUGE is non-deterministic | If I run the ROUGE metric 2 times, with same predictions / references, the scores are slightly different.
Refer to [this Colab notebook](https://colab.research.google.com/drive/1wRssNXgb9ldcp4ulwj-hMJn0ywhDOiDy?usp=sharing) for reproducing the problem.
Example of F-score for ROUGE-1, ROUGE-2, ROUGE-L in 2 differe... | CLOSED | 2020-07-09T04:39:37 | 2022-09-09T15:20:55 | 2020-07-20T23:48:37 | https://github.com/huggingface/datasets/issues/361 | {
"login": "astariul"
} | {
"nodes": []
} | [
"Hi, can you give a full self-contained example to reproduce this behavior?",
"> Hi, can you give a full self-contained example to reproduce this behavior?\r\n\r\nThere is a notebook in the post ;)",
"> If I run the ROUGE metric 2 times, with same predictions / references, the scores are slightly different.\r\n... |
MDU6SXNzdWU2NTM2ODcxNzY= | 360 | [Feature request] Add dataset.ragged_map() function for many-to-many transformations | `dataset.map()` enables one-to-one transformations. Input one example and output one example. This is helpful for tokenizing and cleaning individual lines.
`dataset.filter()` enables one-to-(one-or-none) transformations. Input one example and output either zero/one example. This is helpful for removing portions from t... | CLOSED | 2020-07-09T01:04:43 | 2020-07-09T19:31:51 | 2020-07-09T19:31:51 | https://github.com/huggingface/datasets/issues/360 | {
"login": "jarednielsen"
} | {
"nodes": []
} | [
"Actually `map(batched=True)` can already change the size of the dataset.\r\nIt can accept examples of length `N` and returns a batch of length `M` (can be null or greater than `N`).\r\n\r\nI'll make that explicit in the doc that I'm currently writing.",
"You're two steps ahead of me :) In my testing, it also wor... |
MDU6SXNzdWU2NTM2NTYyNzk= | 359 | ArrowBasedBuilder _prepare_split parse_schema breaks on nested structures | I tried using the Json dataloader to load some JSON lines files. but get an exception in the parse_schema function.
```
---------------------------------------------------------------------------
ValueError Traceback (most recent call last)
<ipython-input-23-9aecfbee53bd> in <mo... | CLOSED | 2020-07-08T23:24:05 | 2020-07-10T14:52:06 | 2020-07-10T14:52:06 | https://github.com/huggingface/datasets/issues/359 | {
"login": "timothyjlaurent"
} | {
"nodes": []
} | [
"Hi, it depends on what it is in your `dataset_builder.py` file. Can you share it?\r\n\r\nIf you are just loading `json` files, you can also directly use the `json` script (which will find the schema/features from your JSON structure):\r\n\r\n```python\r\nfrom nlp import load_dataset\r\nds = load_dataset(\"json\", ... |
MDU6SXNzdWU2NTM0NTEwMTM= | 355 | can't load SNLI dataset | `nlp` seems to load `snli` from some URL based on nlp.stanford.edu. This subdomain is frequently down -- including right now, when I'd like to load `snli` in a Colab notebook, but can't.
Is there a plan to move these datasets to huggingface servers for a more stable solution?
Btw, here's the stack trace:
```
... | CLOSED | 2020-07-08T16:54:14 | 2020-07-18T05:15:57 | 2020-07-15T07:59:01 | https://github.com/huggingface/datasets/issues/355 | {
"login": "jxmorris12"
} | {
"nodes": []
} | [
"I just added the processed files of `snli` on our google storage, so that when you do `load_dataset` it can download the processed files from there :)\r\n\r\nWe are thinking about having available those processed files for more datasets in the future, because sometimes files aren't available (like for `snli`), or ... |
MDU6SXNzdWU2NTMyNTA2MTE= | 353 | [Dataset requests] New datasets for Text Classification | We are missing a few datasets for Text Classification which is an important field.
Namely, it would be really nice to add:
- [x] TREC-6 dataset (see here for instance: https://pytorchnlp.readthedocs.io/en/latest/source/torchnlp.datasets.html#torchnlp.datasets.trec_dataset) **[done]**
- #386
- [x] Yelp-5
- #... | OPEN | 2020-07-08T12:17:58 | 2025-04-05T09:28:15 | null | https://github.com/huggingface/datasets/issues/353 | {
"login": "thomwolf"
} | {
"nodes": [
{
"name": "help wanted"
},
{
"name": "dataset request"
}
]
} | [
"Pinging @mariamabarham as well",
"- `nlp` has MR! It's called `rotten_tomatoes`\r\n- SST is part of GLUE, or is that just SST-2?\r\n- `nlp` also has `ag_news`, a popular news classification dataset\r\n\r\nI'd also like to see:\r\n- the Yahoo Answers topic classification dataset\r\n- the Kaggle Fake News classifi... |
MDU6SXNzdWU2NTIxMDY1Njc= | 347 | 'cp950' codec error from load_dataset('xtreme', 'tydiqa') | 
I guess the error is related to python source encoding issue that my PC is trying to decode the source code with wrong encoding-decoding tools, perhaps :
https://www.python.org/dev/peps/pep-0263/
I gues... | CLOSED | 2020-07-07T08:14:23 | 2020-09-07T14:51:45 | 2020-09-07T14:51:45 | https://github.com/huggingface/datasets/issues/347 | {
"login": "cosmeowpawlitan"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"This is probably a Windows issue, we need to specify the encoding when `load_dataset()` reads the original CSV file.\r\nTry to find the `open()` statement called by `load_dataset()` and add an `encoding='utf-8'` parameter.\r\nSee issues #242 and #307 ",
"It should be in `xtreme.py:L755`:\r\n```python\r\n ... |
MDU6SXNzdWU2NTE3NjEyMDE= | 345 | Supporting documents in ELI5 | I was attempting to use the ELI5 dataset, when I realized that huggingface does not provide the supporting documents (the source documents from the common crawl). Without the supporting documents, this makes the dataset about as useful for my project as a block of cheese, or some other more apt metaphor. According to ... | CLOSED | 2020-07-06T19:14:13 | 2020-10-27T15:38:45 | 2020-10-27T15:38:45 | https://github.com/huggingface/datasets/issues/345 | {
"login": "saverymax"
} | {
"nodes": []
} | [
"Hi @saverymax ! For licensing reasons, the original team was unable to release pre-processed CommonCrawl documents. Instead, they provided a script to re-create them from a CommonCrawl dump, but it unfortunately requires access to a medium-large size cluster:\r\nhttps://github.com/facebookresearch/ELI5#downloading... |
MDU6SXNzdWU2NTEzMzMxOTQ= | 342 | Features should be updated when `map()` changes schema | `dataset.map()` can change the schema and column names.
We should update the features in this case (with what is possible to infer). | CLOSED | 2020-07-06T08:03:23 | 2020-07-23T10:15:16 | 2020-07-23T10:15:16 | https://github.com/huggingface/datasets/issues/342 | {
"login": "thomwolf"
} | {
"nodes": []
} | [
"`dataset.column_names` are being updated but `dataset.features` aren't indeed..."
] |
MDU6SXNzdWU2NTAwMzU4ODc= | 337 | [Feature request] Export Arrow dataset to TFRecords | The TFRecord generation process is error-prone and requires complex separate Python scripts to download and preprocess the data. I propose to combine the user-friendly features of `nlp` with the speed and efficiency of TFRecords. Sample API:
```python
# use these existing methods
ds = load_dataset("wikitext", "wik... | CLOSED | 2020-07-02T15:47:12 | 2020-07-22T09:16:12 | 2020-07-22T09:16:12 | https://github.com/huggingface/datasets/issues/337 | {
"login": "jarednielsen"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NDk5MTQyMDM= | 336 | [Dataset requests] New datasets for Open Question Answering | We are still a few datasets missing for Open-Question Answering which is currently a field in strong development.
Namely, it would be really nice to add:
- WebQuestions (Berant et al., 2013) [done]
- CuratedTrec (Baudis et al. 2015) [not open-source]
- MS-MARCO (NGuyen et al. 2016) [done]
- SearchQA (Dunn et al.... | CLOSED | 2020-07-02T13:03:03 | 2020-07-16T09:04:22 | 2020-07-16T09:04:22 | https://github.com/huggingface/datasets/issues/336 | {
"login": "thomwolf"
} | {
"nodes": [
{
"name": "help wanted"
},
{
"name": "dataset request"
}
]
} | [] |
MDU6SXNzdWU2NDg1MzMxOTk= | 331 | Loading CNN/Daily Mail dataset produces `nlp.utils.info_utils.NonMatchingSplitsSizesError` | ```
>>> import nlp
>>> nlp.load_dataset('cnn_dailymail', '3.0.0')
Downloading and preparing dataset cnn_dailymail/3.0.0 (download: 558.32 MiB, generated: 1.26 GiB, total: 1.81 GiB) to /u/jm8wx/.cache/huggingface/datasets/cnn_dailymail/3.0.0/3.0.0...
Traceback (most recent call last):
File "<stdin>", line 1, in... | CLOSED | 2020-06-30T22:21:33 | 2020-07-09T13:03:40 | 2020-07-09T13:03:40 | https://github.com/huggingface/datasets/issues/331 | {
"login": "jxmorris12"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"I couldn't reproduce on my side.\r\nIt looks like you were not able to generate all the examples, and you have the problem for each split train-test-validation.\r\nCould you try to enable logging, try again and send the logs ?\r\n```python\r\nimport logging\r\nlogging.basicConfig(level=logging.INFO)\r\n```",
"he... |
MDU6SXNzdWU2NDg0NDY5Nzk= | 329 | [Bug] FileLock dependency incompatible with filesystem | I'm downloading a dataset successfully with
`load_dataset("wikitext", "wikitext-2-raw-v1")`
But when I attempt to cache it on an external volume, it hangs indefinitely:
`load_dataset("wikitext", "wikitext-2-raw-v1", cache_dir="/fsx") # /fsx is an external volume mount`
The filesystem when hanging looks like thi... | CLOSED | 2020-06-30T19:45:31 | 2024-12-26T15:13:39 | 2020-06-30T21:33:06 | https://github.com/huggingface/datasets/issues/329 | {
"login": "jarednielsen"
} | {
"nodes": []
} | [
"Hi, can you give details on your environment/os/packages versions/etc?",
"Environment is Ubuntu 18.04, Python 3.7.5, nlp==0.3.0, filelock=3.0.12.\r\n\r\nThe external volume is Amazon FSx for Lustre, and it by default creates files with limited permissions. My working theory is that FileLock creates a lockfile th... |
MDU6SXNzdWU2NDgzMjY4NDE= | 328 | Fork dataset | We have a multi-task learning model training I'm trying to convert to using the Arrow-based nlp dataset.
We're currently training a custom TensorFlow model but the nlp paradigm should be a bridge for us to be able to use the wealth of pre-trained models in Transformers.
Our preprocessing flow parses raw text and... | CLOSED | 2020-06-30T16:42:53 | 2020-07-06T21:43:59 | 2020-07-06T21:43:59 | https://github.com/huggingface/datasets/issues/328 | {
"login": "timothyjlaurent"
} | {
"nodes": []
} | [
"To be able to generate the Arrow dataset you need to either use our csv or json utilities `load_dataset(\"json\", data_files=my_json_files)` OR write your own custom dataset script (you can find some inspiration from the [squad](https://github.com/huggingface/nlp/blob/master/datasets/squad/squad.py) script for exa... |
MDU6SXNzdWU2NDgxMjYxMDM= | 326 | Large dataset in Squad2-format | At the moment we are building an large question answering dataset and think about sharing it with the huggingface community.
Caused the computing power we splitted it into multiple tiles, but they are all in the same format.
Right now the most important facts about are this:
- Contexts: 1.047.671
- questions: 1.677... | CLOSED | 2020-06-30T12:18:59 | 2020-07-09T09:01:50 | 2020-07-09T09:01:50 | https://github.com/huggingface/datasets/issues/326 | {
"login": "flozi00"
} | {
"nodes": []
} | [
"I'm pretty sure you can get some inspiration from the squad_v2 script. It looks like the dataset is quite big so it will take some time for the users to generate it, but it should be reasonable.\r\n\r\nAlso you are saying that you are still making the dataset grow in size right ?\r\nIt's probably good practice to ... |
MDU6SXNzdWU2NDc1MjU3MjU= | 324 | Error when calculating glue score | I was trying glue score along with other metrics here. But glue gives me this error;
```
import nlp
glue_metric = nlp.load_metric('glue',name="cola")
glue_score = glue_metric.compute(predictions, references)
```
```
---------------------------------------------------------------------------
--------------... | CLOSED | 2020-06-29T16:53:48 | 2020-07-09T09:13:34 | 2020-07-09T09:13:34 | https://github.com/huggingface/datasets/issues/324 | {
"login": "D-i-l-r-u-k-s-h-i"
} | {
"nodes": []
} | [
"The glue metric for cola is a metric for classification. It expects label ids as integers as inputs.",
"I want to evaluate a sentence pair whether they are semantically equivalent, so I used MRPC and it gives the same error, does that mean we have to encode the sentences and parse as input?\r\n\r\nusing BertToke... |
MDU6SXNzdWU2NDcyNzE1MjY= | 321 | ERROR:root:mwparserfromhell | Hi,
I am trying to download some wikipedia data but I got this error for spanish "es" (but there are maybe some others languages which have the same error I haven't tried all of them ).
`ERROR:root:mwparserfromhell ParseError: This is a bug and should be reported. Info: C tokenizer exited with non-empty token sta... | CLOSED | 2020-06-29T11:10:43 | 2022-02-14T15:21:46 | 2022-02-14T15:21:46 | https://github.com/huggingface/datasets/issues/321 | {
"login": "Shiro-LK"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"It looks like it comes from `mwparserfromhell`.\r\n\r\nWould it be possible to get the bad `section` that causes this issue ? The `section` string is from `datasets/wikipedia.py:L548` ? You could just add a `try` statement and print the section if the line `section_text.append(section.strip_code().strip())` crashe... |
MDU6SXNzdWU2NDcxODgxNjc= | 320 | Blog Authorship Corpus, Non Matching Splits Sizes Error, nlp viewer | Selecting `blog_authorship_corpus` in the nlp viewer throws the following error:
```
NonMatchingSplitsSizesError: [{'expected': SplitInfo(name='train', num_bytes=610252351, num_examples=532812, dataset_name='blog_authorship_corpus'), 'recorded': SplitInfo(name='train', num_bytes=614706451, num_examples=535568, dat... | CLOSED | 2020-06-29T07:36:35 | 2020-06-29T14:44:42 | 2020-06-29T14:44:42 | https://github.com/huggingface/datasets/issues/320 | {
"login": "mariamabarham"
} | {
"nodes": [
{
"name": "nlp-viewer"
}
]
} | [
"I wonder if this means downloading failed? That corpus has a really slow server.",
"This dataset seems to have a decoding problem that results in inconsistencies in the number of generated examples.\r\nSee #215.\r\nThat's why we end up with a `NonMatchingSplitsSizesError `."
] |
MDU6SXNzdWU2NDY3OTI0ODc= | 319 | Nested sequences with dicts | Am pretty much finished [adding a dataset](https://github.com/ghomasHudson/nlp/blob/DocRED/datasets/docred/docred.py) for [DocRED](https://github.com/thunlp/DocRED), but am getting an error when trying to add a nested `nlp.features.sequence(nlp.features.sequence({key:value,...}))`.
The original data is in this form... | CLOSED | 2020-06-27T23:45:17 | 2020-07-03T10:22:00 | 2020-07-03T10:22:00 | https://github.com/huggingface/datasets/issues/319 | {
"login": "ghomasHudson"
} | {
"nodes": []
} | [
"Oh yes, this is a backward compatibility feature with tensorflow_dataset in which a `Sequence` or `dict` is converted in a `dict` of `lists`, unfortunately it is not very intuitive, see here: https://github.com/huggingface/nlp/blob/master/src/nlp/features.py#L409\r\n\r\nTo avoid this behavior, you can just define ... |
MDU6SXNzdWU2NDY1NTUzODQ= | 317 | Adding a dataset with multiple subtasks | I intent to add the datasets of the MT Quality Estimation shared tasks to `nlp`. However, they have different subtasks -- such as word-level, sentence-level and document-level quality estimation, each of which having different language pairs, and some of the data reused in different subtasks.
For example, in [QE 201... | CLOSED | 2020-06-26T23:14:19 | 2020-10-27T15:36:52 | 2020-10-27T15:36:52 | https://github.com/huggingface/datasets/issues/317 | {
"login": "erickrf"
} | {
"nodes": []
} | [
"For one dataset you can have different configurations that each have their own `nlp.Features`.\r\nWe imagine having one configuration per subtask for example.\r\nThey are loaded with `nlp.load_dataset(\"my_dataset\", \"my_config\")`.\r\n\r\nFor example the `glue` dataset has many configurations. It is a bit differ... |
MDU6SXNzdWU2NDU4ODg5NDM= | 315 | [Question] Best way to batch a large dataset? | I'm training on large datasets such as Wikipedia and BookCorpus. Following the instructions in [the tutorial notebook](https://colab.research.google.com/github/huggingface/nlp/blob/master/notebooks/Overview.ipynb), I see the following recommended for TensorFlow:
```python
train_tf_dataset = train_tf_dataset.filter(... | OPEN | 2020-06-25T22:30:20 | 2026-05-21T23:25:15 | null | https://github.com/huggingface/datasets/issues/315 | {
"login": "jarednielsen"
} | {
"nodes": [
{
"name": "generic discussion"
}
]
} | [
"Update: I think I've found a solution.\r\n\r\n```python\r\noutput_types = {\"input_ids\": tf.int64, \"token_type_ids\": tf.int64, \"attention_mask\": tf.int64}\r\ndef train_dataset_gen():\r\n for i in range(len(train_dataset)):\r\n yield train_dataset[i]\r\ntf_dataset = tf.data.Dataset.from_generator(tra... |
MDU6SXNzdWU2NDUwMjU1NjE= | 312 | [Feature request] Add `shard()` method to dataset | Currently, to shard a dataset into 10 pieces on different ranks, you can run
```python
rank = 3 # for example
size = 10
dataset = nlp.load_dataset('wikitext', 'wikitext-2-raw-v1', split=f"train[{rank*10}%:{(rank+1)*10}%]")
```
However, this breaks down if you have a number of ranks that doesn't divide cleanly... | CLOSED | 2020-06-24T22:48:33 | 2020-07-06T12:35:36 | 2020-07-06T12:35:36 | https://github.com/huggingface/datasets/issues/312 | {
"login": "jarednielsen"
} | {
"nodes": []
} | [
"Hi Jared,\r\nInteresting, thanks for raising this question. You can also do that after loading with `dataset.select()` or `dataset.filter()` which let you keep only a specific subset of rows in a dataset.\r\nWhat is your use-case for sharding?",
"Thanks for the pointer to those functions! It's still a little mor... |
MDU6SXNzdWU2NDQxODcyNjI= | 307 | Specify encoding for MRPC | Same as #242, but with MRPC: on Windows, I get a `UnicodeDecodeError` when I try to download the dataset:
```python
dataset = nlp.load_dataset('glue', 'mrpc')
```
```python
Downloading and preparing dataset glue/mrpc (download: Unknown size, generated: Unknown size, total: Unknown size) to C:\Users\Python\.cache... | CLOSED | 2020-06-23T22:24:49 | 2020-06-25T12:16:09 | 2020-06-25T12:16:09 | https://github.com/huggingface/datasets/issues/307 | {
"login": "patpizio"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NDQxNDgxNDk= | 305 | Importing downloaded package repository fails | The `get_imports` function in `src/nlp/load.py` has a feature to download a package as a zip archive of the github repository and import functions from the unpacked directory. This is used for example in the `metrics/coval.py` file, and would be useful to add BLEURT (@ankparikh).
Currently however, the code seems to... | CLOSED | 2020-06-23T21:09:05 | 2020-07-30T16:44:23 | 2020-07-30T16:44:23 | https://github.com/huggingface/datasets/issues/305 | {
"login": "yjernite"
} | {
"nodes": [
{
"name": "metric bug"
}
]
} | [] |
MDU6SXNzdWU2NDQwOTE5NzA= | 304 | Problem while printing doc string when instantiating multiple metrics. | When I load more than one metric and try to print doc string of a particular metric,. It shows the doc strings of all imported metric one after the other which looks quite confusing and clumsy.
Attached [Colab](https://colab.research.google.com/drive/13H0ZgyQ2se0mqJ2yyew0bNEgJuHaJ8H3?usp=sharing) Notebook for problem ... | CLOSED | 2020-06-23T19:32:05 | 2020-07-22T09:50:58 | 2020-07-22T09:50:58 | https://github.com/huggingface/datasets/issues/304 | {
"login": "codehunk628"
} | {
"nodes": [
{
"name": "metric bug"
}
]
} | [] |
MDU6SXNzdWU2NDM5MTA0MTg= | 302 | Question - Sign Language Datasets | An emerging field in NLP is SLP - sign language processing.
I was wondering about adding datasets here, specifically because it's shaping up to be large and easily usable.
The metrics for sign language to text translation are the same.
So, what do you think about (me, or others) adding datasets here?
An exa... | CLOSED | 2020-06-23T14:53:40 | 2020-11-25T11:25:33 | 2020-11-25T11:25:33 | https://github.com/huggingface/datasets/issues/302 | {
"login": "AmitMY"
} | {
"nodes": [
{
"name": "enhancement"
},
{
"name": "generic discussion"
}
]
} | [
"Even more complicating - \r\n\r\nAs I see it, datasets can have \"addons\".\r\nFor example, the WebNLG dataset is a dataset for data-to-text. However, a work of mine and other works enriched this dataset with text plans / underlying text structures. In that case, I see a need to load the dataset \"WebNLG\" with \"... |
MDU6SXNzdWU2NDM3NjM1MjU= | 301 | Setting cache_dir gives error on wikipedia download | First of all thank you for a super handy library! I'd like to download large files to a specific drive so I set `cache_dir=my_path`. This works fine with e.g. imdb and squad. But on wikipedia I get an error:
```
nlp.load_dataset('wikipedia', '20200501.de', split = 'train', cache_dir=my_path)
```
```
OSError ... | CLOSED | 2020-06-23T11:31:44 | 2020-06-24T07:05:07 | 2020-06-24T07:05:07 | https://github.com/huggingface/datasets/issues/301 | {
"login": "hallvagi"
} | {
"nodes": []
} | [
"Whoops didn't mean to close this one.\r\nI did some changes, could you try to run it from the master branch ?",
"Now it works, thanks!"
] |
MDU6SXNzdWU2NDM0NDQ2MjU= | 297 | Error in Demo for Specific Datasets | Selecting `natural_questions` or `newsroom` dataset in the online demo results in an error similar to the following.

| CLOSED | 2020-06-23T00:38:42 | 2020-07-17T17:43:06 | 2020-07-17T17:43:06 | https://github.com/huggingface/datasets/issues/297 | {
"login": "s-jse"
} | {
"nodes": [
{
"name": "nlp-viewer"
}
]
} | [
"Thanks for reporting these errors :)\r\n\r\nI can actually see two issues here.\r\n\r\nFirst, datasets like `natural_questions` require apache_beam to be processed. Right now the import is not at the right place so we have this error message. However, even the imports are fixed, the nlp viewer doesn't actually hav... |
MDU6SXNzdWU2NDM0MjM3MTc= | 296 | snli -1 labels | I'm trying to train a model on the SNLI dataset. Why does it have so many -1 labels?
```
import nlp
from collections import Counter
data = nlp.load_dataset('snli')['train']
print(Counter(data['label']))
Counter({0: 183416, 2: 183187, 1: 182764, -1: 785})
```
| CLOSED | 2020-06-22T23:33:30 | 2020-06-23T14:41:59 | 2020-06-23T14:41:58 | https://github.com/huggingface/datasets/issues/296 | {
"login": "jxmorris12"
} | {
"nodes": []
} | [
"@jxmorris12 , we use `-1` to label examples for which `gold label` is missing (`gold label = -` in the original dataset). ",
"Thanks @mariamabarham! so the original dataset is missing some labels? That is weird. Is standard practice just to discard those examples training/eval?",
"Yes the original dataset is... |
MDU6SXNzdWU2NDMyNDU0MTI= | 295 | Improve input warning for evaluation metrics | Hi,
I am the author of `bert_score`. Recently, we received [ an issue ](https://github.com/Tiiiger/bert_score/issues/62) reporting a problem in using `bert_score` from the `nlp` package (also see #238 in this repo). After looking into this, I realized that the problem arises from the format `nlp.Metric` takes inpu... | CLOSED | 2020-06-22T17:28:57 | 2020-06-23T14:47:37 | 2020-06-23T14:47:37 | https://github.com/huggingface/datasets/issues/295 | {
"login": "Tiiiger"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NDMxODExNzk= | 294 | Cannot load arxiv dataset on MacOS? | I am having trouble loading the `"arxiv"` config from the `"scientific_papers"` dataset on MacOS. When I try loading the dataset with:
```python
arxiv = nlp.load_dataset("scientific_papers", "arxiv")
```
I get the following stack trace:
```bash
JSONDecodeError Traceback (most recen... | CLOSED | 2020-06-22T15:46:55 | 2020-06-30T15:25:10 | 2020-06-30T15:25:10 | https://github.com/huggingface/datasets/issues/294 | {
"login": "JohnGiorgi"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"I couldn't replicate this issue on my macbook :/\r\nCould you try to play with different encodings in `with open(path, encoding=...) as f` in scientific_papers.py:L108 ?",
"I was able to track down the file causing the problem by adding the following to `scientific_papers.py` (starting at line 116):\r\n\r\n```py... |
MDU6SXNzdWU2NDE5NzgyODY= | 290 | ConnectionError - Eli5 dataset download | Hi, I have a problem with downloading Eli5 dataset. When typing `nlp.load_dataset('eli5')`, I get ConnectionError: Couldn't reach https://storage.googleapis.com/huggingface-nlp/cache/datasets/eli5/LFQA_reddit/1.0.0/explain_like_im_five-train_eli5.arrow
I would appreciate if you could help me with this issue. | CLOSED | 2020-06-19T13:40:33 | 2020-06-20T13:22:24 | 2020-06-20T13:22:24 | https://github.com/huggingface/datasets/issues/290 | {
"login": "JovanNj"
} | {
"nodes": []
} | [
"It should ne fixed now, thanks for reporting this one :)\r\nIt was an issue on our google storage.\r\n\r\nLet me now if you're still facing this issue.",
"It works now, thanks for prompt help!"
] |
MDU6SXNzdWU2NDE4ODg2MTA= | 288 | Error at the first example in README: AttributeError: module 'dill' has no attribute '_dill' | /Users/parasol_tree/anaconda3/lib/python3.6/site-packages/tensorflow/python/framework/dtypes.py:469: FutureWarning: Passing (type, 1) or '1type' as a synonym of type is deprecated; in a future version of numpy, it will be understood as (type, (1,)) / '(1,)type'.
_np_qint8 = np.dtype([("qint8", np.int8, 1)])
/Users/... | CLOSED | 2020-06-19T11:01:22 | 2020-06-21T09:05:11 | 2020-06-21T09:05:11 | https://github.com/huggingface/datasets/issues/288 | {
"login": "wutong8023"
} | {
"nodes": []
} | [
"It looks like the bug comes from `dill`. Which version of `dill` are you using ?",
"Thank you. It is version 0.2.6, which version is better?",
"0.2.6 is three years old now, maybe try a more recent one, e.g. the current 0.3.2 if you can?",
"Thanks guys! I upgraded dill and it works.",
"Awesome"
] |
MDU6SXNzdWU2NDEyNzA0Mzk= | 283 | Consistent formatting of citations | The citations are all of a different format, some have "```" and have text inside, others are proper bibtex.
Can we make it so that they all are proper citations, i.e. parse by the bibtex spec:
https://bibtexparser.readthedocs.io/en/master/ | CLOSED | 2020-06-18T14:48:45 | 2020-06-22T17:30:46 | 2020-06-22T17:30:46 | https://github.com/huggingface/datasets/issues/283 | {
"login": "srush"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NDEwNjc4NTY= | 281 | Private/sensitive data | Hi all,
Thanks for this fantastic library, it makes it very easy to do prototyping for NLP projects interchangeably between TF/Pytorch.
Unfortunately, there is data that cannot easily be shared publicly as it may contain sensitive information.
Is there support/a plan to support such data with NLP, e.g. by readin... | CLOSED | 2020-06-18T09:47:27 | 2020-06-20T13:15:12 | 2020-06-20T13:15:12 | https://github.com/huggingface/datasets/issues/281 | {
"login": "MFreidank"
} | {
"nodes": []
} | [
"Hi @MFreidank, you should already be able to load a dataset from local sources, indeed. (ping @lhoestq and @jplu)\r\n\r\nWe're also thinking about the ability to host private datasets on a hosted bucket with permission management, but that's further down the road.",
"Hi @MFreidank, it is possible to load a datas... |
MDU6SXNzdWU2NDA2Nzc2MTU= | 280 | Error with SquadV2 Metrics | I can't seem to import squad v2 metrics.
**squad_metric = nlp.load_metric('squad_v2')**
**This throws me an error.:**
```
ImportError Traceback (most recent call last)
<ipython-input-8-170b6a170555> in <module>
----> 1 squad_metric = nlp.load_metric('squad_v2')
~/env/lib6... | CLOSED | 2020-06-17T19:10:54 | 2020-06-19T08:33:41 | 2020-06-19T08:33:41 | https://github.com/huggingface/datasets/issues/280 | {
"login": "avinregmi"
} | {
"nodes": []
} | [] |
MDU6SXNzdWU2NDA2MTE2OTI= | 279 | Dataset Preprocessing Cache with .map() function not working as expected | I've been having issues with reproducibility when loading and processing datasets with the `.map` function. I was only able to resolve them by clearing all of the cache files on my system.
Is there a way to disable using the cache when processing a dataset? As I make minor processing changes on the same dataset, I ... | CLOSED | 2020-06-17T17:17:21 | 2026-02-03T19:38:57 | 2021-04-18T23:43:49 | https://github.com/huggingface/datasets/issues/279 | {
"login": "sarahwie"
} | {
"nodes": []
} | [
"When you're processing a dataset with `.map`, it checks whether it has already done this computation using a hash based on the function and the input (using some fancy serialization with `dill`). If you found that it doesn't work as expected in some cases, let us know !\r\n\r\nGiven that, you can still force to re... |
MDU6SXNzdWU2NDA1MTg5MTc= | 278 | MemoryError when loading German Wikipedia | Hi, first off let me say thank you for all the awesome work you're doing at Hugging Face across all your projects (NLP, Transformers, Tokenizers) - they're all amazing contributions to us working with NLP models :)
I'm trying to download the German Wikipedia dataset as follows:
```
wiki = nlp.load_dataset("wikip... | CLOSED | 2020-06-17T15:06:21 | 2020-06-19T12:53:02 | 2020-06-19T12:53:02 | https://github.com/huggingface/datasets/issues/278 | {
"login": "gregburman"
} | {
"nodes": []
} | [
"Hi !\r\n\r\nAs you noticed, \"big\" datasets like Wikipedia require apache beam to be processed.\r\nHowever users usually don't have an apache beam runtime available (spark, dataflow, etc.) so our goal for this library is to also make available processed versions of these datasets, so that users can just download ... |
MDU6SXNzdWU2NDAxNjMwNTM= | 277 | Empty samples in glue/qqp | ```
qqp = nlp.load_dataset('glue', 'qqp')
print(qqp['train'][310121])
print(qqp['train'][362225])
```
```
{'question1': 'How can I create an Android app?', 'question2': '', 'label': 0, 'idx': 310137}
{'question1': 'How can I develop android app?', 'question2': '', 'label': 0, 'idx': 362246}
```
Notice that que... | CLOSED | 2020-06-17T05:54:52 | 2020-06-21T00:21:45 | 2020-06-21T00:21:45 | https://github.com/huggingface/datasets/issues/277 | {
"login": "richarddwang"
} | {
"nodes": []
} | [
"We are only wrapping the original dataset.\r\n\r\nMaybe try to ask on the GLUE mailing list or reach out to the original authors?",
"Tanks for the suggestion, I'll try to ask GLUE benchmark.\r\nI'll first close the issue, post the following up here afterwards, and reopen the issue if needed. "
] |
MDU6SXNzdWU2Mzk0MzkwNTI= | 275 | NonMatchingChecksumError when loading pubmed dataset | I get this error when i run `nlp.load_dataset('scientific_papers', 'pubmed', split = 'train[:50%]')`.
The error is:
```
---------------------------------------------------------------------------
NonMatchingChecksumError Traceback (most recent call last)
<ipython-input-2-7742dea167d0> in <module... | CLOSED | 2020-06-16T07:31:51 | 2020-06-19T07:37:07 | 2020-06-19T07:37:07 | https://github.com/huggingface/datasets/issues/275 | {
"login": "DavideStenner"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"For some reason the files are not available for unauthenticated users right now (like the download service of this package). Instead of downloading the right files, it downloads the html of the error.\r\nAccording to the error it should be back again in 24h.\r\n\r\n
```python
ModuleNotFoundError: No module named 'langdetect'
Traceback:
File "/home/sasha/.local/lib/python3.7/site-packages/streamlit/ScriptRunner.py", line 322, in _run_script
exec(code, module.__d... | CLOSED | 2020-06-13T08:26:16 | 2020-10-27T15:35:29 | 2020-10-27T15:35:13 | https://github.com/huggingface/datasets/issues/270 | {
"login": "rajarsheem"
} | {
"nodes": [
{
"name": "nlp-viewer"
}
]
} | [
"C4 is too large to be shown in the viewer"
] |
MDU6SXNzdWU2MzgxMDY3NzQ= | 269 | Error in metric.compute: missing `original_instructions` argument | I'm running into an error using metrics for computation in the latest master as well as version 0.2.1. Here is a minimal example:
```python
import nlp
rte_metric = nlp.load_metric('glue', name="rte")
rte_metric.compute(
[0, 0, 1, 1],
[0, 1, 0, 1],
)
```
```
181 # Read the predictio... | CLOSED | 2020-06-13T06:26:54 | 2020-06-18T07:41:44 | 2020-06-18T07:41:44 | https://github.com/huggingface/datasets/issues/269 | {
"login": "zphang"
} | {
"nodes": [
{
"name": "metric bug"
}
]
} | [] |
MDU6SXNzdWU2Mzc0MTU1NDU= | 267 | How can I load/find WMT en-romanian? | I believe it is from `wmt16`
When I run
```python
wmt = nlp.load_dataset('wmt16')
```
I get:
```python
AssertionError: The dataset wmt16 with config cs-en requires manual data.
Please follow the manual download instructions: Some of the wmt configs here, require a manual download.
Please look into wm... | CLOSED | 2020-06-12T01:09:37 | 2020-06-19T08:24:19 | 2020-06-19T08:24:19 | https://github.com/huggingface/datasets/issues/267 | {
"login": "sshleifer"
} | {
"nodes": []
} | [
"I will take a look :-) "
] |
MDU6SXNzdWU2MzcwMjgwMTU= | 263 | [Feature request] Support for external modality for language datasets | # Background
In recent years many researchers have advocated that learning meanings from text-based only datasets is just like asking a human to "learn to speak by listening to the radio" [[E. Bender and A. Koller,2020](https://openreview.net/forum?id=GKTvAcb12b), [Y. Bisk et. al, 2020](https://arxiv.org/abs/2004.10... | CLOSED | 2020-06-11T13:42:18 | 2022-02-10T13:26:35 | 2022-02-10T13:26:35 | https://github.com/huggingface/datasets/issues/263 | {
"login": "aleSuglia"
} | {
"nodes": [
{
"name": "enhancement"
},
{
"name": "generic discussion"
}
]
} | [
"Thanks a lot, @aleSuglia for the very detailed and introductive feature request.\r\nIt seems like we could build something pretty useful here indeed.\r\n\r\nOne of the questions here is that Arrow doesn't have built-in support for generic \"tensors\" in records but there might be ways to do that in a clean way. We... |
MDU6SXNzdWU2MzYzNzIzODA= | 261 | Downloading dataset error with pyarrow.lib.RecordBatch | I am trying to download `sentiment140` and I have the following error
```
/usr/local/lib/python3.6/dist-packages/nlp/load.py in load_dataset(path, name, version, data_dir, data_files, split, cache_dir, download_config, download_mode, ignore_verifications, save_infos, **config_kwargs)
518 download_mode=... | CLOSED | 2020-06-10T16:04:19 | 2020-06-11T14:35:12 | 2020-06-11T14:35:12 | https://github.com/huggingface/datasets/issues/261 | {
"login": "cuent"
} | {
"nodes": []
} | [
"When you install `nlp` for the first time on a Colab runtime, it updates the `pyarrow` library that was already on colab. This update shows this message on colab:\r\n```\r\nWARNING: The following packages were previously imported in this runtime:\r\n [pyarrow]\r\nYou must restart the runtime in order to use newly... |
MDU6SXNzdWU2MzYyMzk1Mjk= | 259 | documentation missing how to split a dataset | I am trying to understand how to split a dataset ( as arrow_dataset).
I know I can do something like this to access a split which is already in the original dataset :
`ds_test = nlp.load_dataset('imdb, split='test') `
But how can I split ds_test into a test and a validation set (without reading the data into m... | CLOSED | 2020-06-10T13:18:13 | 2023-03-14T13:56:07 | 2020-06-18T22:20:24 | https://github.com/huggingface/datasets/issues/259 | {
"login": "fotisj"
} | {
"nodes": []
} | [
"this seems to work for my specific problem:\r\n\r\n`self.train_ds, self.test_ds, self.val_ds = map(_prepare_ds, ('train', 'test[:25%]+test[50%:75%]', 'test[75%:]'))`",
"Currently you can indeed split a dataset using `ds_test = nlp.load_dataset('imdb, split='test[:5000]')` (works also with percentages).\r\n\r\nHo... |
MDU6SXNzdWU2MzU4NTk1MjU= | 258 | Why is dataset after tokenization far more larger than the orginal one ? | I tokenize wiki dataset by `map` and cache the results.
```
def tokenize_tfm(example):
example['input_ids'] = hf_fast_tokenizer.convert_tokens_to_ids(hf_fast_tokenizer.tokenize(example['text']))
return example
wiki = nlp.load_dataset('wikipedia', '20200501.en', cache_dir=cache_dir)['train']
wiki.map(token... | CLOSED | 2020-06-10T01:27:07 | 2020-06-10T12:46:34 | 2020-06-10T12:46:34 | https://github.com/huggingface/datasets/issues/258 | {
"login": "richarddwang"
} | {
"nodes": []
} | [
"Hi ! This is because `.map` added the new column `input_ids` to the dataset, and so all the other columns were kept. Therefore the dataset size increased a lot.\r\n If you want to only keep the `input_ids` column, you can stash the other ones by specifying `remove_columns=[\"title\", \"text\"]` in the arguments of... |
MDU6SXNzdWU2MzU2MjA5Nzk= | 257 | Tokenizer pickling issue fix not landed in `nlp` yet? | Unless I recreate an arrow_dataset from my loaded nlp dataset myself (which I think does not use the cache by default), I get the following error when applying the map function:
```
dataset = nlp.load_dataset('cos_e')
tokenizer = GPT2TokenizerFast.from_pretrained('gpt2', cache_dir=cache_dir)
for split in datase... | CLOSED | 2020-06-09T17:12:34 | 2020-06-10T21:45:32 | 2020-06-09T17:26:53 | https://github.com/huggingface/datasets/issues/257 | {
"login": "sarahwie"
} | {
"nodes": []
} | [
"Yes, the new release of tokenizers solves this and should be out soon.\r\nIn the meantime, you can install it with `pip install tokenizers==0.8.0-dev2`",
"If others run into this issue, a quick fix is to use python 3.6 instead of 3.7+. Serialization differences between the 3rd party `dataclasses` package for 3.6... |
MDU6SXNzdWU2MzU1OTYyOTU= | 256 | [Feature request] Add a feature to dataset | Is there a straightforward way to add a field to the arrow_dataset, prior to performing map? | CLOSED | 2020-06-09T16:38:12 | 2020-06-09T16:51:42 | 2020-06-09T16:51:42 | https://github.com/huggingface/datasets/issues/256 | {
"login": "sarahwie"
} | {
"nodes": []
} | [
"Do you have an example of what you would like to do? (you can just add a field in the output of the unction you give to map and this will add this field in the output table)",
"Given another source of data loaded in, I want to pre-add it to the dataset so that it aligns with the indices of the arrow dataset prio... |
MDU6SXNzdWU2MzUwNTc1Njg= | 254 | [Feature request] Be able to remove a specific sample of the dataset | As mentioned in #117, it's currently not possible to remove a sample of the dataset.
But it is a important use case : After applying some preprocessing, some samples might be empty for example. We should be able to remove these samples from the dataset, or at least mark them as `removed` so when iterating the datase... | CLOSED | 2020-06-09T02:22:13 | 2020-06-09T08:41:38 | 2020-06-09T08:41:38 | https://github.com/huggingface/datasets/issues/254 | {
"login": "astariul"
} | {
"nodes": []
} | [
"Oh yes you can now do that with the `dataset.filter()` method that was added in #214 "
] |
MDU6SXNzdWU2MzQ1NjMyMzk= | 252 | NonMatchingSplitsSizesError error when reading the IMDB dataset | Hi!
I am trying to load the `imdb` dataset with this line:
`dataset = nlp.load_dataset('imdb', data_dir='/A/PATH', cache_dir='/A/PATH')`
but I am getting the following error:
```
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "/mounts/Users/cisintern/antmarakis/anaconda3/... | CLOSED | 2020-06-08T12:26:24 | 2021-08-27T15:20:58 | 2020-06-08T14:01:26 | https://github.com/huggingface/datasets/issues/252 | {
"login": "antmarakis"
} | {
"nodes": []
} | [
"I just tried on my side and I didn't encounter your problem.\r\nApparently the script doesn't generate all the examples on your side.\r\n\r\nCan you provide the version of `nlp` you're using ?\r\nCan you try to clear your cache and re-run the code ?",
"I updated it, that was it, thanks!",
"Hello, I am facing t... |
MDU6SXNzdWU2MzMzOTM0NDM= | 249 | [Dataset created] some critical small issues when I was creating a dataset | Hi, I successfully created a dataset and has made a pr #248.
But I have encountered several problems when I was creating it, and those should be easy to fix.
1. Not found dataset_info.json
should be fixed by #241 , eager to wait it be merged.
2. Forced to install `apach_beam`
If we should install it, then it m... | CLOSED | 2020-06-07T12:58:54 | 2020-06-12T08:28:51 | 2020-06-12T08:28:51 | https://github.com/huggingface/datasets/issues/249 | {
"login": "richarddwang"
} | {
"nodes": []
} | [
"Thanks for noticing all these :) They should be easy to fix indeed",
"Alright I think I fixed all the problems you mentioned. Thanks again, that will be useful for many people.\r\nThere is still more work needed for point 7. but we plan to have some nice docs soon."
] |
MDU6SXNzdWU2MzIzODAwNTQ= | 246 | What is the best way to cache a dataset? | For example if I want to use streamlit with a nlp dataset:
```
@st.cache
def load_data():
return nlp.load_dataset('squad')
```
This code raises the error "uncachable object"
Right now I just fixed with a constant for my specific case:
```
@st.cache(hash_funcs={pyarrow.lib.Buffer: lambda b: 0})
```... | CLOSED | 2020-06-06T11:02:07 | 2020-07-09T09:15:07 | 2020-07-09T09:15:07 | https://github.com/huggingface/datasets/issues/246 | {
"login": "Mistobaan"
} | {
"nodes": []
} | [
"Everything is already cached by default in 🤗nlp (in particular dataset\nloading and all the “map()” operations) so I don’t think you need to do any\nspecific caching in streamlit.\n\nTell us if you feel like it’s not the case.\n\nOn Sat, 6 Jun 2020 at 13:02, Fabrizio Milo <notifications@github.com> wrote:\n\n> Fo... |
MDU6SXNzdWU2MzE5ODUxMDg= | 245 | SST-2 test labels are all -1 | I'm trying to test a model on the SST-2 task, but all the labels I see in the test set are -1.
```
>>> import nlp
>>> glue = nlp.load_dataset('glue', 'sst2')
>>> glue
{'train': Dataset(schema: {'sentence': 'string', 'label': 'int64', 'idx': 'int32'}, num_rows: 67349), 'validation': Dataset(schema: {'sentence': 'st... | CLOSED | 2020-06-05T21:41:42 | 2021-12-08T00:47:32 | 2020-06-06T16:56:41 | https://github.com/huggingface/datasets/issues/245 | {
"login": "jxmorris12"
} | {
"nodes": []
} | [
"this also happened to me with `nlp.load_dataset('glue', 'mnli')`",
"Yes, this is because the test sets for glue are hidden so the labels are\nnot publicly available. You can read the glue paper for more details.\n\nOn Sat, 6 Jun 2020 at 18:16, Jack Morris <notifications@github.com> wrote:\n\n> this also happened... |
MDU6SXNzdWU2MzE3MzM2ODM= | 242 | UnicodeDecodeError when downloading GLUE-MNLI | When I run
```python
dataset = nlp.load_dataset('glue', 'mnli')
```
I get an encoding error (could it be because I'm using Windows?) :
```python
# Lots of error log lines later...
~\Miniconda3\envs\nlp\lib\site-packages\tqdm\std.py in __iter__(self)
1128 try:
-> 1129 for obj in iterable:... | CLOSED | 2020-06-05T16:30:01 | 2020-06-09T16:06:47 | 2020-06-08T08:45:03 | https://github.com/huggingface/datasets/issues/242 | {
"login": "patpizio"
} | {
"nodes": []
} | [
"It should be good now, thanks for noticing and fixing it ! I would say that it was because you are on windows but not 100% sure",
"On Windows Python supports Unicode almost everywhere, but one of the notable exceptions is open() where it uses the locale encoding schema. So platform independent python scripts wou... |
MDU6SXNzdWU2MzE0MzQ2Nzc= | 240 | Deterministic dataset loading | When calling:
```python
import nlp
dataset = nlp.load_dataset("trivia_qa", split="validation[:1%]")
```
the resulting dataset is not deterministic over different google colabs.
After talking to @thomwolf, I suspect the reason to be the use of `glob.glob` in line:
https://github.com/huggingface/nlp/blob/2e0... | CLOSED | 2020-06-05T09:03:26 | 2020-06-08T09:18:14 | 2020-06-08T09:18:14 | https://github.com/huggingface/datasets/issues/240 | {
"login": "patrickvonplaten"
} | {
"nodes": []
} | [
"Yes good point !",
"I think using `sorted(glob.glob())` would actually solve this problem. Can you think of other reasons why dataset loading might not be deterministic? @mariamabarham @yjernite @lhoestq @thomwolf . \r\n\r\nI can do a sweep through the dataset scripts and fix the glob.glob() if you guys are ok w... |
MDU6SXNzdWU2MzEzNDA0NDA= | 239 | [Creating new dataset] Not found dataset_info.json | Hi, I am trying to create Toronto Book Corpus. #131
I ran
`~/nlp % python nlp-cli test datasets/bookcorpus --save_infos --all_configs`
but this doesn't create `dataset_info.json` and try to use it
```
INFO:nlp.load:Checking datasets/bookcorpus/bookcorpus.py for additional imports.
INFO:filelock:Lock 1397953257... | CLOSED | 2020-06-05T06:15:04 | 2020-06-07T13:01:04 | 2020-06-07T13:01:04 | https://github.com/huggingface/datasets/issues/239 | {
"login": "richarddwang"
} | {
"nodes": []
} | [
"I think you can just `rm` this directory and it should be good :)",
"@lhoestq - this seems to happen quite often (already the 2nd issue). Can we maybe delete this automatically?",
"Yes I have an idea of what's going on. I'm sure I can fix that",
"Hi, I rebase my local copy to `fix-empty-cache-dir`, and try t... |
MDU6SXNzdWU2MzEyNjAxNDM= | 238 | [Metric] Bertscore : Warning : Empty candidate sentence; Setting recall to be 0. | When running BERT-Score, I'm meeting this warning :
> Warning: Empty candidate sentence; Setting recall to be 0.
Code :
```
import nlp
metric = nlp.load_metric("bertscore")
scores = metric.compute(["swag", "swags"], ["swags", "totally something different"], lang="en", device=0)
```
---
**What am I do... | CLOSED | 2020-06-05T02:14:47 | 2020-06-29T17:10:19 | 2020-06-29T17:10:19 | https://github.com/huggingface/datasets/issues/238 | {
"login": "astariul"
} | {
"nodes": [
{
"name": "metric bug"
}
]
} | [
"This print statement comes from the official implementation of bert_score (see [here](https://github.com/Tiiiger/bert_score/blob/master/bert_score/utils.py#L343)). The warning shows up only if the attention mask outputs no candidate.\r\nRight now we want to only use official code for metrics to have fair evaluatio... |
MDU6SXNzdWU2MzExOTk5NDA= | 237 | Can't download MultiNLI | When I try to download MultiNLI with
```python
dataset = load_dataset('multi_nli')
```
I get this long error:
```python
---------------------------------------------------------------------------
OSError Traceback (most recent call last)
<ipython-input-13-3b11f6be4cb9> in <m... | CLOSED | 2020-06-04T23:05:21 | 2020-06-06T10:51:34 | 2020-06-06T10:51:34 | https://github.com/huggingface/datasets/issues/237 | {
"login": "patpizio"
} | {
"nodes": []
} | [
"You should use `load_dataset('glue', 'mnli')`",
"Thanks! I thought I had to use the same code displayed in the live viewer:\r\n```python\r\n!pip install nlp\r\nfrom nlp import load_dataset\r\ndataset = load_dataset('multi_nli', 'plain_text')\r\n```\r\nYour suggestion works, even if then I got a different issue (... |
MDU6SXNzdWU2MzA1MzQ0Mjc= | 234 | Huggingface NLP, Uploading custom dataset | Hello,
Does anyone know how we can call our custom dataset using the nlp.load command? Let's say that I have a dataset based on the same format as that of squad-v1.1, how am I supposed to load it using huggingface nlp.
Thank you! | CLOSED | 2020-06-04T05:59:06 | 2020-07-06T09:33:26 | 2020-07-06T09:33:26 | https://github.com/huggingface/datasets/issues/234 | {
"login": "Nouman97"
} | {
"nodes": []
} | [
"What do you mean 'custom' ? You may want to elaborate on it when ask a question.\r\n\r\nAnyway, there are two things you may interested\r\n`nlp.Dataset.from_file` and `load_dataset(..., cache_dir=)`",
"To load a dataset you need to have a script that defines the format of the examples, the splits and the way to ... |
MDU6SXNzdWU2MzA0MzIxMzI= | 233 | Fail to download c4 english corpus | i run following code to download c4 English corpus.
```
dataset = nlp.load_dataset('c4', 'en', beam_runner='DirectRunner'
, data_dir='/mypath')
```
and i met failure as follows
```
Downloading and preparing dataset c4/en (download: Unknown size, generated: Unknown size, total: Unknown size) to /home/adam/.... | CLOSED | 2020-06-04T01:06:38 | 2021-01-08T07:17:32 | 2020-06-08T09:16:59 | https://github.com/huggingface/datasets/issues/233 | {
"login": "donggyukimc"
} | {
"nodes": []
} | [
"Hello ! Thanks for noticing this bug, let me fix that.\r\n\r\nAlso for information, as specified in the changelog of the latest release, C4 currently needs to have a runtime for apache beam to work on. Apache beam is used to process this very big dataset and it can work on dataflow, spark, flink, apex, etc. You ca... |
MDU6SXNzdWU2Mjk5NTI0MDI= | 228 | Not able to access the XNLI dataset | When I try to access the XNLI dataset, I get the following error. The option of plain_text get selected automatically and then I get the following error.
```
FileNotFoundError: [Errno 2] No such file or directory: '/home/sasha/.cache/huggingface/datasets/xnli/plain_text/1.0.0/dataset_info.json'
Traceback:
File "/... | CLOSED | 2020-06-03T12:25:14 | 2020-07-17T17:44:22 | 2020-07-17T17:44:22 | https://github.com/huggingface/datasets/issues/228 | {
"login": "aswin-giridhar"
} | {
"nodes": [
{
"name": "nlp-viewer"
}
]
} | [
"Added pull request to change the name of the file from dataset_infos.json to dataset_info.json",
"Thanks for reporting this bug !\r\nAs it seems to be just a cache problem, I closed your PR.\r\nI think we might just need to clear and reload the `xnli` cache @srush ? ",
"Update: The dataset_info.json error is g... |
MDU6SXNzdWU2Mjk4NDU3MDQ= | 227 | Should we still have to force to install apache_beam to download wikipedia ? | Hi, first thanks to @lhoestq 's revolutionary work, I successfully downloaded processed wikipedia according to the doc. 😍😍😍
But at the first try, it tell me to install `apache_beam` and `mwparserfromhell`, which I thought wouldn't be used according to #204 , it was kind of confusing me at that time.
Maybe we s... | CLOSED | 2020-06-03T09:33:20 | 2020-06-03T15:25:41 | 2020-06-03T15:25:41 | https://github.com/huggingface/datasets/issues/227 | {
"login": "richarddwang"
} | {
"nodes": []
} | [
"Thanks for your message 😊 \r\nIndeed users shouldn't have to install those dependencies",
"Got it, feel free to close this issue when you think it’s resolved.",
"It should be good now :)"
] |
MDU6SXNzdWU2MjgwODMzNjY= | 225 | [ROUGE] Different scores with `files2rouge` | It seems that the ROUGE score of `nlp` is lower than the one of `files2rouge`.
Here is a self-contained notebook to reproduce both scores : https://colab.research.google.com/drive/14EyAXValB6UzKY9x4rs_T3pyL7alpw_F?usp=sharing
---
`nlp` : (Only mid F-scores)
>rouge1 0.33508031962733364
rouge2 0.145743337761... | CLOSED | 2020-06-01T00:50:36 | 2020-06-03T15:27:18 | 2020-06-03T15:27:18 | https://github.com/huggingface/datasets/issues/225 | {
"login": "astariul"
} | {
"nodes": [
{
"name": "Metric discussion"
}
]
} | [
"@Colanim unfortunately there are different implementations of the ROUGE metric floating around online which yield different results, and we had to chose one for the package :) We ended up including the one from the google-research repository, which does minimal post-processing before computing the P/R/F scores. If... |
MDU6SXNzdWU2Mjc3OTE2OTM= | 224 | [Feature Request/Help] BLEURT model -> PyTorch | Hi, I am interested in porting google research's new BLEURT learned metric to PyTorch (because I wish to do something experimental with language generation and backpropping through BLEURT). I noticed that you guys don't have it yet so I am partly just asking if you plan to add it (@thomwolf said you want to do so on Tw... | CLOSED | 2020-05-30T18:30:40 | 2023-08-26T17:38:48 | 2021-01-04T09:53:32 | https://github.com/huggingface/datasets/issues/224 | {
"login": "adamwlev"
} | {
"nodes": [
{
"name": "enhancement"
}
]
} | [
"Is there any update on this? \r\n\r\nThanks!",
"Hitting this error when using bleurt with PyTorch ...\r\n\r\n```\r\nUnrecognizedFlagError: Unknown command line flag 'f'\r\n```\r\n... and I'm assuming because it was built for TF specifically. Is there a way to use this metric in PyTorch?",
"We currently provid... |
MDU6SXNzdWU2Mjc2ODMzODY= | 223 | [Feature request] Add FLUE dataset | Hi,
I think it would be interesting to add the FLUE dataset for francophones or anyone wishing to work on French.
In other requests, I read that you are already working on some datasets, and I was wondering if FLUE was planned.
If it is not the case, I can provide each of the cleaned FLUE datasets (in the form... | CLOSED | 2020-05-30T08:52:15 | 2020-12-03T13:39:33 | 2020-12-03T13:39:33 | https://github.com/huggingface/datasets/issues/223 | {
"login": "lbourdois"
} | {
"nodes": [
{
"name": "dataset request"
}
]
} | [
"Hi @lbourdois, yes please share it with us",
"@mariamabarham \r\nI put all the datasets on this drive: https://1drv.ms/u/s!Ao2Rcpiny7RFinDypq7w-LbXcsx9?e=iVsEDh\r\n\r\n\r\nSome information : \r\n• For FLUE, the quote used is\r\n\r\n> @misc{le2019flaubert,\r\n> title={FlauBERT: Unsupervised Language Model Pre... |
MDU6SXNzdWU2Mjc1ODY2OTA= | 222 | Colab Notebook breaks when downloading the squad dataset | When I run the notebook in Colab
https://colab.research.google.com/github/huggingface/nlp/blob/master/notebooks/Overview.ipynb
breaks when running this cell:
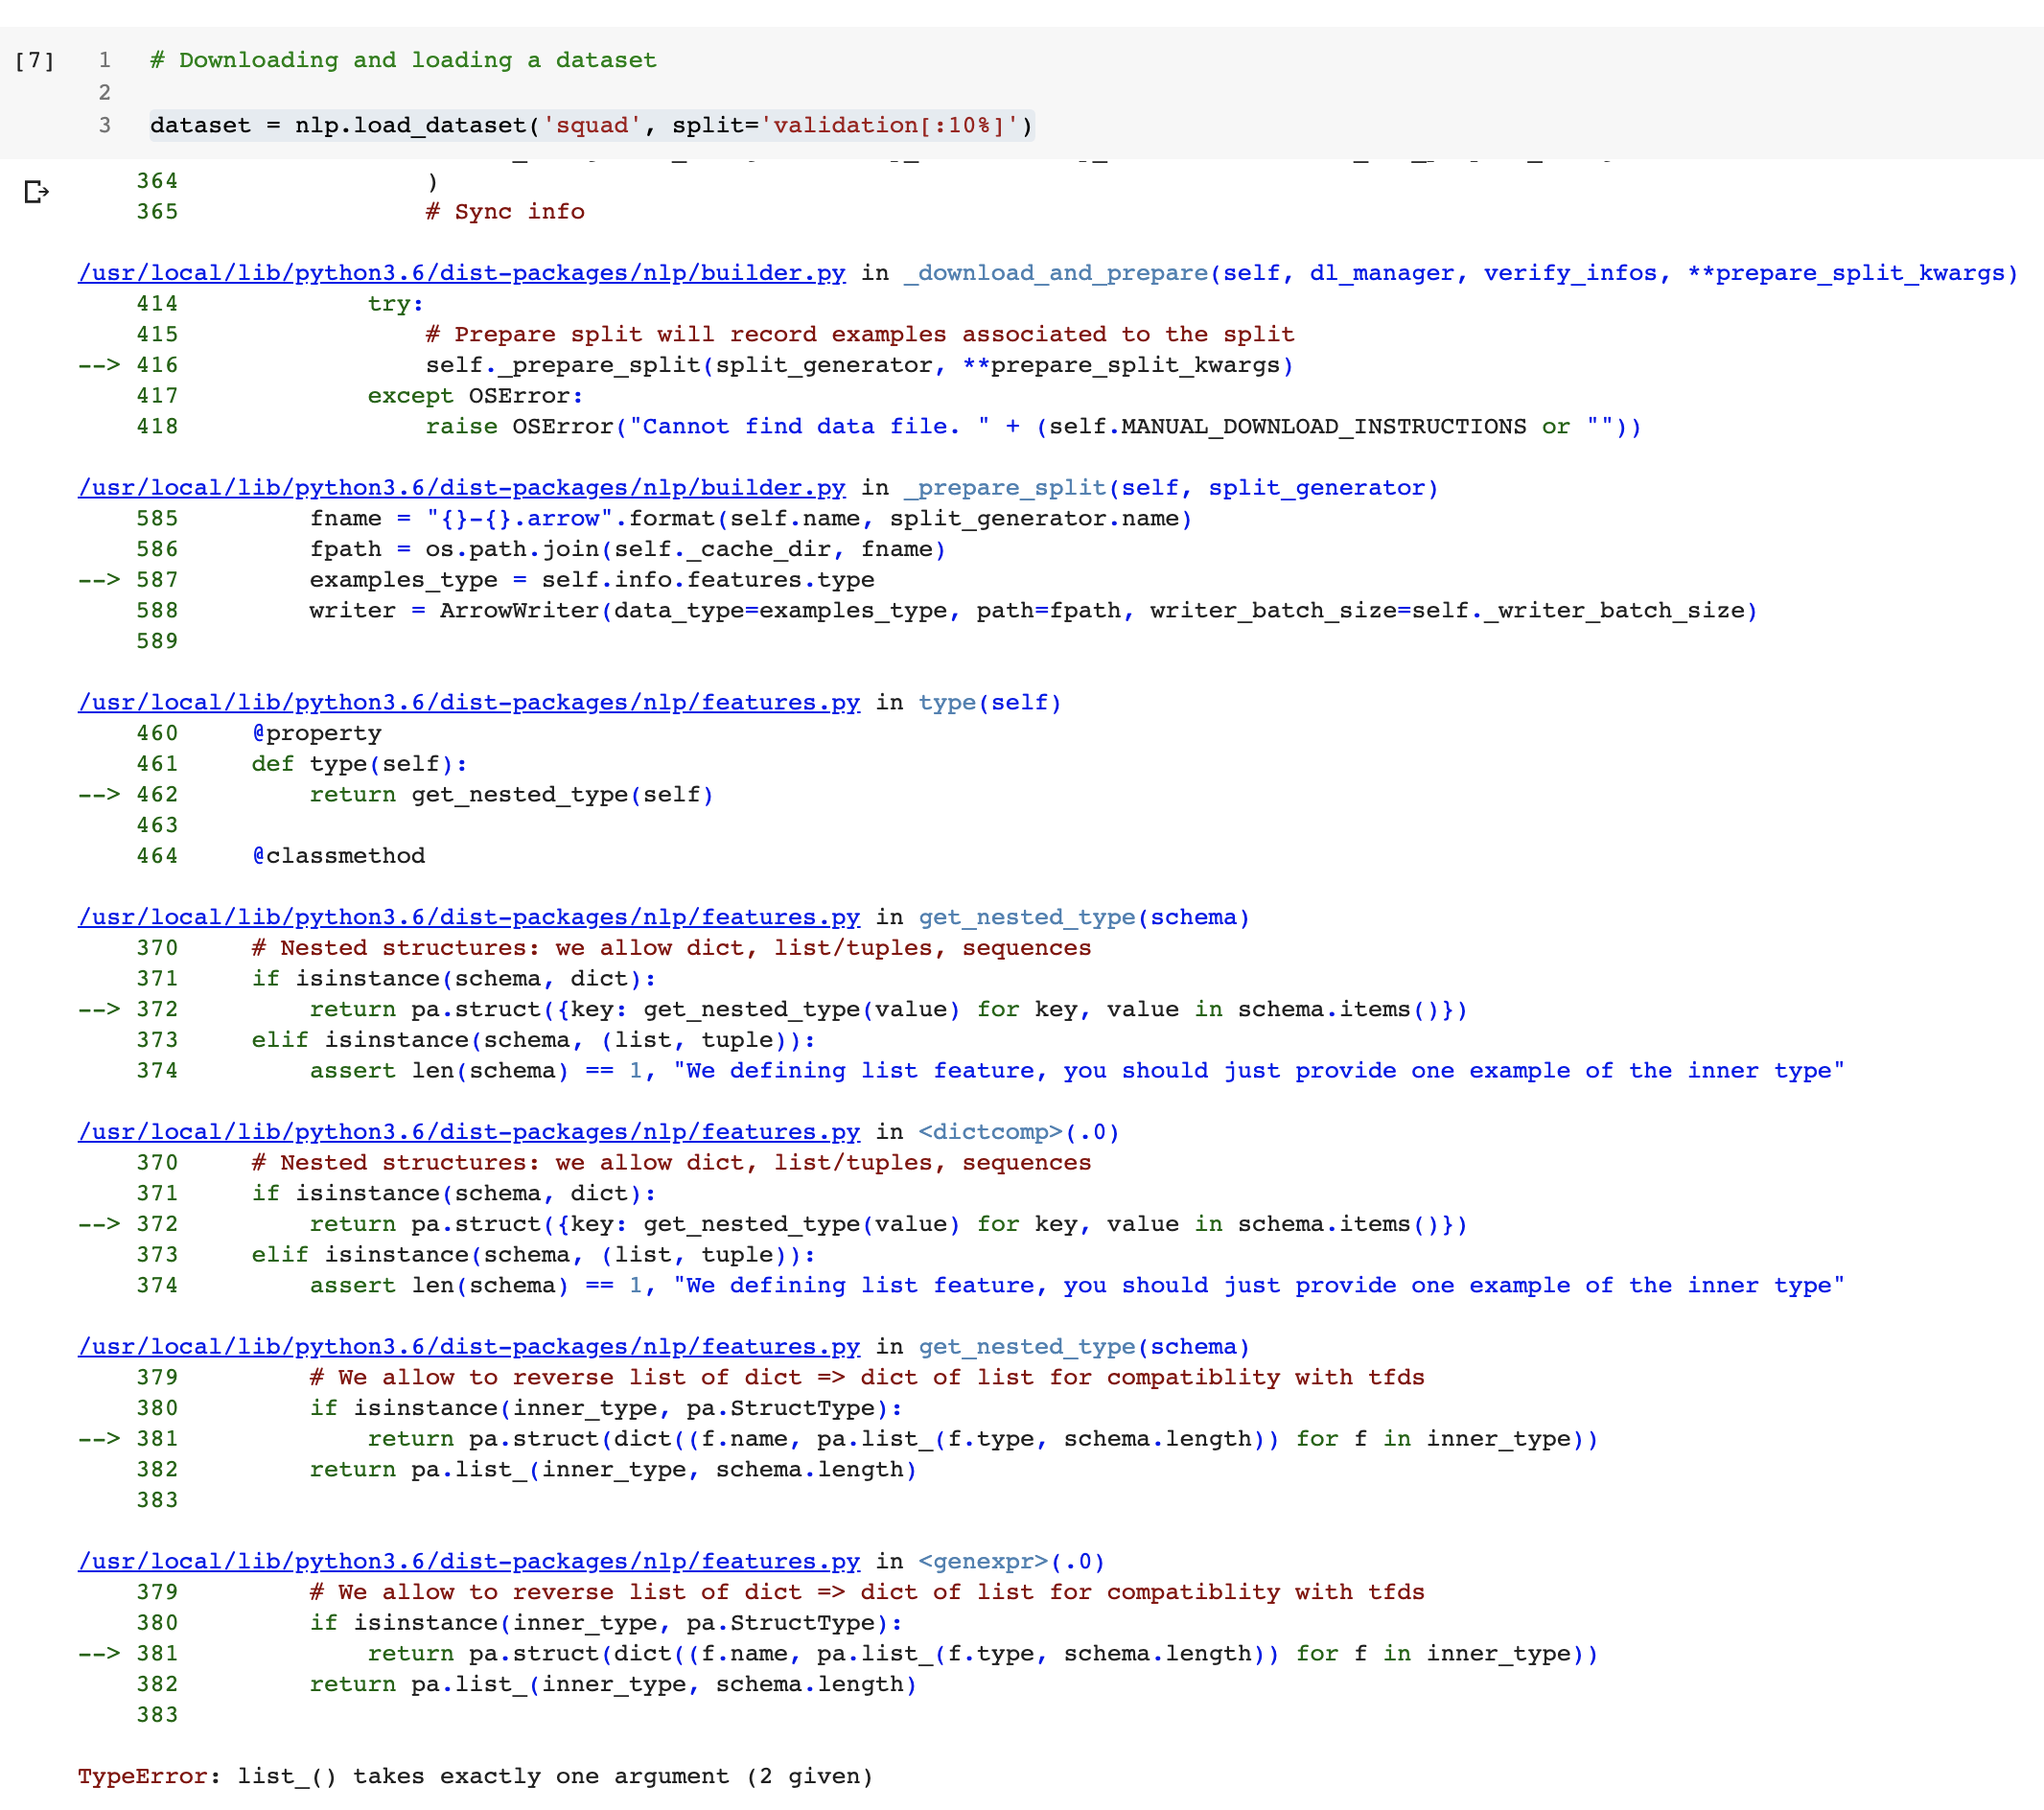
| CLOSED | 2020-05-29T22:55:59 | 2020-06-04T00:21:05 | 2020-06-04T00:21:05 | https://github.com/huggingface/datasets/issues/222 | {
"login": "carlos-aguayo"
} | {
"nodes": []
} | [
"The notebook forces version 0.1.0. If I use the latest, things work, I'll run the whole notebook and create a PR.\r\n\r\nBut in the meantime, this issue gets fixed by changing:\r\n`!pip install nlp==0.1.0`\r\nto\r\n`!pip install nlp`",
"It still breaks very near the end\r\n\r\n.
The [T5 paper](https://arxiv.org/pdf/1910.10683.pdf) highlights multiple ways of mixing the tasks together during finetuning:
- **Examples-proportional mixing** - sam... | OPEN | 2020-05-29T09:22:26 | 2026-05-21T23:24:59 | null | https://github.com/huggingface/datasets/issues/217 | {
"login": "ghomasHudson"
} | {
"nodes": [
{
"name": "enhancement"
},
{
"name": "generic discussion"
}
]
} | [
"I like this feature! I think the first question we should decide on is how to convert all datasets into the same format. In T5, the authors decided to format every dataset into a text-to-text format. If the dataset had \"multiple\" inputs like MNLI, the inputs were concatenated. So in MNLI the input:\r\n\r\n> - **... |
MDU6SXNzdWU2MjY4OTY4OTA= | 216 | ❓ How to get ROUGE-2 with the ROUGE metric ? | I'm trying to use ROUGE metric, but I don't know how to get the ROUGE-2 metric.
---
I compute scores with :
```python
import nlp
rouge = nlp.load_metric('rouge')
with open("pred.txt") as p, open("ref.txt") as g:
for lp, lg in zip(p, g):
rouge.add([lp], [lg])
score = rouge.compute()
```
... | CLOSED | 2020-05-28T23:47:32 | 2020-06-01T00:04:35 | 2020-06-01T00:04:35 | https://github.com/huggingface/datasets/issues/216 | {
"login": "astariul"
} | {
"nodes": []
} | [
"ROUGE-1 and ROUGE-L shouldn't return the same thing. This is weird",
"For the rouge2 metric you can do\r\n\r\n```python\r\nrouge = nlp.load_metric('rouge')\r\nwith open(\"pred.txt\") as p, open(\"ref.txt\") as g:\r\n for lp, lg in zip(p, g):\r\n rouge.add(lp, lg)\r\nscore = rouge.compute(rouge_types=[\... |
MDU6SXNzdWU2MjY4Njc4Nzk= | 215 | NonMatchingSplitsSizesError when loading blog_authorship_corpus | Getting this error when i run `nlp.load_dataset('blog_authorship_corpus')`.
```
raise NonMatchingSplitsSizesError(str(bad_splits))
nlp.utils.info_utils.NonMatchingSplitsSizesError: [{'expected': SplitInfo(name='train',
num_bytes=610252351, num_examples=532812, dataset_name='blog_authorship_corpus'),
'recorded... | CLOSED | 2020-05-28T22:55:19 | 2025-01-04T00:03:12 | 2022-02-10T13:05:45 | https://github.com/huggingface/datasets/issues/215 | {
"login": "cedricconol"
} | {
"nodes": [
{
"name": "dataset bug"
}
]
} | [
"I just ran it on colab and got this\r\n```\r\n[{'expected': SplitInfo(name='train', num_bytes=610252351, num_examples=532812,\r\ndataset_name='blog_authorship_corpus'), 'recorded': SplitInfo(name='train',\r\nnum_bytes=611607465, num_examples=533285, dataset_name='blog_authorship_corpus')},\r\n{'expected': SplitInf... |
MDU6SXNzdWU2MjY1NjU5OTQ= | 211 | [Arrow writer, Trivia_qa] Could not convert TagMe with type str: converting to null type | Running the following code
```
import nlp
ds = nlp.load_dataset("trivia_qa", "rc", split="validation[:1%]") # this might take 2.3 min to download but it's cached afterwards...
ds.map(lambda x: x, load_from_cache_file=False)
```
triggers a `ArrowInvalid: Could not convert TagMe with type str: converting to n... | CLOSED | 2020-05-28T14:38:14 | 2020-07-23T10:15:16 | 2020-07-23T10:15:16 | https://github.com/huggingface/datasets/issues/211 | {
"login": "patrickvonplaten"
} | {
"nodes": [
{
"name": "enhancement"
}
]
} | [
"Here the full error trace:\r\n\r\n```\r\nArrowInvalid Traceback (most recent call last)\r\n<ipython-input-1-7aaf3f011358> in <module>\r\n 1 import nlp\r\n 2 ds = nlp.load_dataset(\"trivia_qa\", \"rc\", split=\"validation[:1%]\") # this might take 2.3 min to download but it's... |
MDU6SXNzdWU2MjU5MzIyMDA= | 207 | Remove test set from NLP viewer | While the new [NLP viewer](https://huggingface.co/nlp/viewer/) is a great tool, I think it would be best to outright remove the option of looking at the test sets. At the very least, a warning should be displayed to users before showing the test set. Newcomers to the field might not be aware of best practices, and smal... | CLOSED | 2020-05-27T18:32:07 | 2022-02-10T13:17:45 | 2022-02-10T13:17:45 | https://github.com/huggingface/datasets/issues/207 | {
"login": "chrisdonahue"
} | {
"nodes": [
{
"name": "nlp-viewer"
}
]
} | [
"~is the viewer also open source?~\r\n[is a streamlit app!](https://docs.streamlit.io/en/latest/getting_started.html)",
"Appears that [two thirds of those polled on Twitter](https://twitter.com/srush_nlp/status/1265734497632477185) are in favor of _some_ mechanism for averting eyeballs from the test data.",
"We... |
MDU6SXNzdWU2MjU4NDI5ODk= | 206 | [Question] Combine 2 datasets which have the same columns | Hi,
I am using ``nlp`` to load personal datasets. I created summarization datasets in multi-languages based on wikinews. I have one dataset for english and one for german (french is getting to be ready as well). I want to keep these datasets independent because they need different pre-processing (add different task-... | CLOSED | 2020-05-27T16:25:52 | 2020-06-10T09:11:14 | 2020-06-10T09:11:14 | https://github.com/huggingface/datasets/issues/206 | {
"login": "airKlizz"
} | {
"nodes": []
} | [
"We are thinking about ways to combine datasets for T5 in #217, feel free to share your thoughts about this.",
"Ok great! I will look at it. Thanks"
] |
MDU6SXNzdWU2MjU0OTM5ODM= | 202 | Mistaken `_KWARGS_DESCRIPTION` for XNLI metric | Hi!
The [`_KWARGS_DESCRIPTION`](https://github.com/huggingface/nlp/blob/7d0fa58641f3f462fb2861dcdd6ce7f0da3f6a56/metrics/xnli/xnli.py#L45) for the XNLI metric uses `Args` and `Returns` text from [BLEU](https://github.com/huggingface/nlp/blob/7d0fa58641f3f462fb2861dcdd6ce7f0da3f6a56/metrics/bleu/bleu.py#L58) metric:
... | CLOSED | 2020-05-27T08:34:42 | 2020-05-28T13:22:36 | 2020-05-28T13:22:36 | https://github.com/huggingface/datasets/issues/202 | {
"login": "phiyodr"
} | {
"nodes": []
} | [
"Indeed, good catch ! thanks\r\nFixing it right now"
] |
MDU6SXNzdWU2MjUyMDA2Mjc= | 198 | Index outside of table length | The offset input box warns of numbers larger than a limit (like 2000) but then the errors start at a smaller value than that limit (like 1955).
> ValueError: Index (2000) outside of table length (2000).
> Traceback:
> File "/home/sasha/.local/lib/python3.7/site-packages/streamlit/ScriptRunner.py", line 322, in _ru... | CLOSED | 2020-05-26T21:09:40 | 2020-05-26T22:43:49 | 2020-05-26T22:43:49 | https://github.com/huggingface/datasets/issues/198 | {
"login": "casajarm"
} | {
"nodes": []
} | [
"Sounds like something related to the nlp viewer @srush ",
"Fixed. "
] |
MDU6SXNzdWU2MjQ5NjY5MDQ= | 197 | Scientific Papers only downloading Pubmed | Hi!
I have been playing around with this module, and I am a bit confused about the `scientific_papers` dataset. I thought that it would download two separate datasets, arxiv and pubmed. But when I run the following:
```
dataset = nlp.load_dataset('scientific_papers', data_dir='.', cache_dir='.')
Downloading: 10... | CLOSED | 2020-05-26T15:18:47 | 2020-05-28T08:19:28 | 2020-05-28T08:19:28 | https://github.com/huggingface/datasets/issues/197 | {
"login": "antmarakis"
} | {
"nodes": []
} | [
"Hi so there are indeed two configurations in the datasets as you can see [here](https://github.com/huggingface/nlp/blob/master/datasets/scientific_papers/scientific_papers.py#L81-L82).\r\n\r\nYou can load either one with:\r\n```python\r\ndataset = nlp.load_dataset('scientific_papers', 'pubmed')\r\ndataset = nlp.lo... |
MDU6SXNzdWU2MjQ2NTU1NTg= | 193 | [Tensorflow] Use something else than `from_tensor_slices()` | In the example notebook, the TF Dataset is built using `from_tensor_slices()` :
```python
columns = ['input_ids', 'token_type_ids', 'attention_mask', 'start_positions', 'end_positions']
train_tf_dataset.set_format(type='tensorflow', columns=columns)
features = {x: train_tf_dataset[x] for x in columns[:3]}
label... | CLOSED | 2020-05-26T07:19:14 | 2020-10-27T15:28:11 | 2020-10-27T15:28:11 | https://github.com/huggingface/datasets/issues/193 | {
"login": "astariul"
} | {
"nodes": []
} | [
"I guess we can use `tf.data.Dataset.from_generator` instead. I'll give it a try.",
"Is `tf.data.Dataset.from_generator` working on TPU ?",
"`from_generator` is not working on TPU, I met the following error :\r\n\r\n```\r\nFile \"/usr/local/lib/python3.6/contextlib.py\", line 88, in __exit__\r\n next(self.ge... |
MDU6SXNzdWU2MjQzOTc1OTI= | 192 | [Question] Create Apache Arrow dataset from raw text file | Hi guys, I have gathered and preprocessed about 2GB of COVID papers from CORD dataset @ Kggle. I have seen you have a text dataset as "Crime and punishment" in Apache arrow format. Do you have any script to do it from a raw txt file (preprocessed as for BERT like) or any guide?
Is the worth of send it to you and add i... | CLOSED | 2020-05-25T16:42:47 | 2021-12-18T01:45:34 | 2020-10-27T15:20:22 | https://github.com/huggingface/datasets/issues/192 | {
"login": "mrm8488"
} | {
"nodes": []
} | [
"We store every dataset in the Arrow format. This is convenient as it supports nested types and memory mapping. If you are curious feel free to check the [pyarrow documentation](https://arrow.apache.org/docs/python/)\r\n\r\nYou can use this library to load your covid papers by creating a dataset script. You can fin... |
MDU6SXNzdWU2MjQwNDg4ODE= | 189 | [Question] BERT-style multiple choice formatting | Hello, I am wondering what the equivalent formatting of a dataset should be to allow for multiple-choice answering prediction, BERT-style. Previously, this was done by passing a list of `InputFeatures` to the dataloader instead of a list of `InputFeature`, where `InputFeatures` contained lists of length equal to the nu... | CLOSED | 2020-05-25T05:11:05 | 2020-05-25T18:38:28 | 2020-05-25T18:38:28 | https://github.com/huggingface/datasets/issues/189 | {
"login": "sarahwie"
} | {
"nodes": []
} | [
"Hi @sarahwie, can you details this a little more?\r\n\r\nI'm not sure I understand what you refer to and what you mean when you say \"Previously, this was done by passing a list of InputFeatures to the dataloader instead of a list of InputFeature\"",
"I think I've resolved it. For others' reference: to convert f... |
MDU6SXNzdWU2MjM4OTA0MzA= | 188 | When will the remaining math_dataset modules be added as dataset objects | Currently only the algebra_linear_1d is supported. Is there a timeline for making the other modules supported. If no timeline is established, how can I help? | CLOSED | 2020-05-24T15:46:52 | 2020-05-24T18:53:48 | 2020-05-24T18:53:48 | https://github.com/huggingface/datasets/issues/188 | {
"login": "tylerroost"
} | {
"nodes": []
} | [
"On a similar note it would be nice to differentiate between train-easy, train-medium, and train-hard",
"Hi @tylerroost, we don't have a timeline for this at the moment.\r\nIf you want to give it a look we would be happy to review a PR on it.\r\nAlso, the library is one week old so everything is quite barebones, ... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.