
Datasets:

The dataset viewer is not available for this split.
Error code:   FeaturesError
Exception:    ArrowInvalid
Message:      JSON parse error: Invalid value. in row 0
Traceback:    Traceback (most recent call last):
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 324, in _generate_tables
                  df = pandas_read_json(f)
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 38, in pandas_read_json
                  return pd.read_json(path_or_buf, **kwargs)
                         ~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/pandas/io/json/_json.py", line 791, in read_json
                  json_reader = JsonReader(
                      path_or_buf,
                  ...<16 lines>...
                      engine=engine,
                  )
                File "/usr/local/lib/python3.14/site-packages/pandas/io/json/_json.py", line 905, in __init__
                  self.data = self._preprocess_data(data)
                              ~~~~~~~~~~~~~~~~~~~~~^^^^^^
                File "/usr/local/lib/python3.14/site-packages/pandas/io/json/_json.py", line 917, in _preprocess_data
                  data = data.read()
                File "/usr/local/lib/python3.14/site-packages/datasets/utils/file_utils.py", line 844, in read_with_retries
                  out = read(*args, **kwargs)
                File "<frozen codecs>", line 325, in decode
              UnicodeDecodeError: 'utf-8' codec can't decode byte 0x89 in position 0: invalid start byte

              During handling of the above exception, another exception occurred:

              Traceback (most recent call last):
                File "/src/services/worker/src/worker/job_runners/split/first_rows.py", line 244, in compute_first_rows_from_streaming_response
                  iterable_dataset = iterable_dataset._resolve_features()
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 4408, in _resolve_features
                  features = _infer_features_from_batch(self.with_format(None)._head())
                                                        ~~~~~~~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2679, in _head
                  return next(iter(self.iter(batch_size=n)))
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2861, in iter
                  for key, pa_table in ex_iterable.iter_arrow():
                                       ~~~~~~~~~~~~~~~~~~~~~~^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 2395, in _iter_arrow
                  yield from self.ex_iterable._iter_arrow()
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 536, in _iter_arrow
                  for key, pa_table in iterator:
                                       ^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/iterable_dataset.py", line 419, in _iter_arrow
                  for key, pa_table in self.generate_tables_fn(**gen_kwags):
                                       ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 327, in _generate_tables
                  raise e
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/json/json.py", line 290, in _generate_tables
                  pa_table = paj.read_json(
                      io.BytesIO(batch), read_options=paj.ReadOptions(block_size=block_size)
                  )
                File "pyarrow/_json.pyx", line 342, in pyarrow._json.read_json
                File "pyarrow/error.pxi", line 155, in pyarrow.lib.pyarrow_internal_check_status
                File "pyarrow/error.pxi", line 92, in pyarrow.lib.check_status
                  raise convert_status(status)
              pyarrow.lib.ArrowInvalid: JSON parse error: Invalid value. in row 0
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.
DDACS, Deep Drawing and Cutting Simulations Dataset


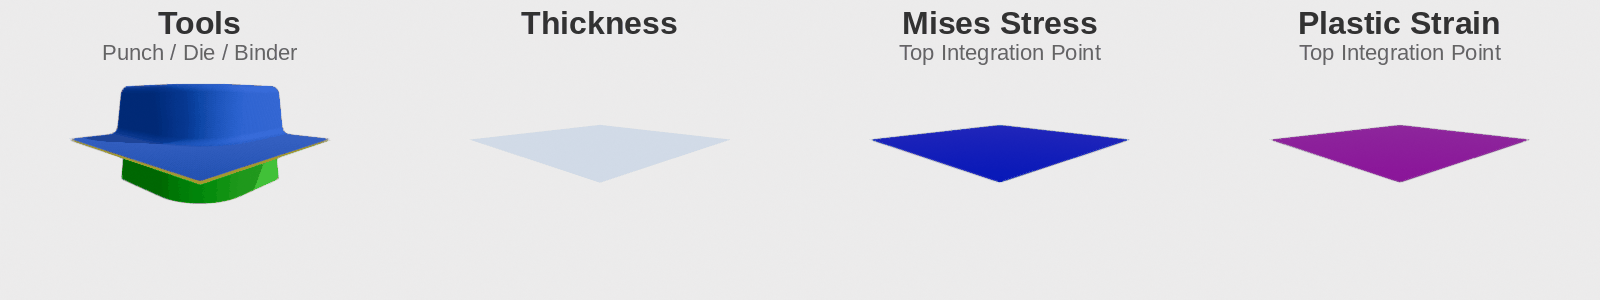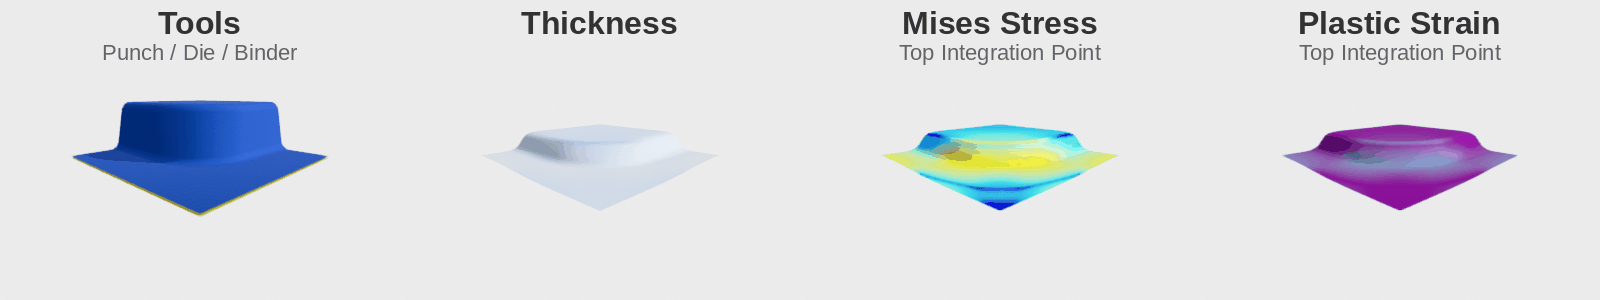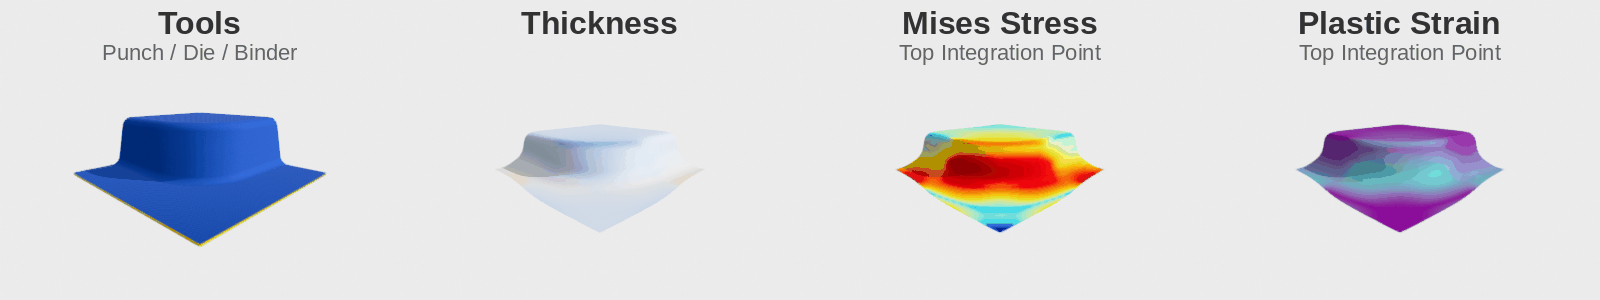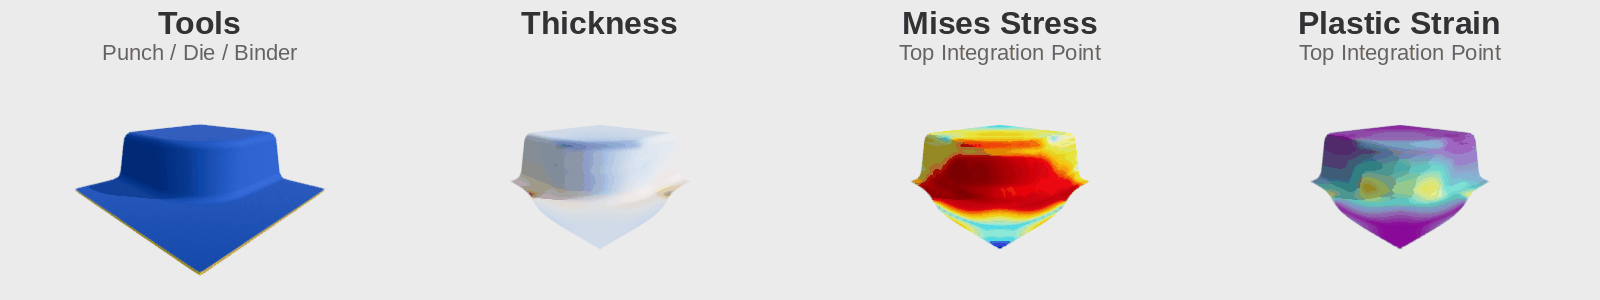
Simulation with the tool geometries showing sheet metal thinning, stress, and strain.
A large-scale dataset and benchmark for training AI models that replace computationally expensive FEA simulations in industrial sheet metal manufacturing. Each simulation models a two-stage stamping process (deep drawing in OP10 and cutting with elastic recovery in OP20) for a cup geometry parameterised by 8 input dimensions. Train ML surrogates that predict mesh deformation, stress, strain, and springback in seconds instead of the minutes-to-hours a CAE solver would take.
| Simulations | 32,466 |
| Total size | ~640 GB (HDF5, lossless) |
| Process steps per sim | 2 (OP10 deep drawing, OP20 cutting) |
| Input parameters | 8 (4 geometric + 4 process) |
| Train / val / test | 25,973 / 3,246 / 3,247 (predefined) |
| Mesh-node states | ~2.1 B across all sims, timesteps, components |
Documentation · Dataset DOI · Paper
About this sample
This is a 22 MB teaser of DDACS, one full simulation plus the Croissant 1.1 manifest, the complete process-parameter table, and the dataset documentation, so you can explore the schema and run every tutorial in seconds before committing to the full download.
data/
  metadata.json             Croissant 1.1 manifest (the dataset schema)
  process_parameters.csv    8 input parameters for all 32,466 simulations
  h5/258864.zip             one full simulation (OP10 + OP20, all components)
ddacs_documentation.pdf     dataset documentation
notebooks/                  the tutorial notebooks (Hugging Face bundle only; on Kaggle
                            they are the attached Code notebooks)
Croissant manifest. data/metadata.json is the
Croissant 1.1 manifest, the machine-readable
schema (every HDF5 field and CSV column) that ddacs.load() and any
Croissant-aware tool consume. It is the same manifest published with the full
dataset on DaRUS (doi:10.18419/DARUS-4801).
Installation
pip install ddacs # add the PyTorch adapter with: pip install 'ddacs[torch]'
Basic usage
ddacs.load parses the Croissant manifest; ddacs.open_h5 opens a single
simulation in memory and returns an h5py.File.
import ddacs

# Load the dataset manifest bundled with this sample.
ds = ddacs.load(data_dir="data")
print([rs.id for rs in ds.metadata.record_sets])

# Open the included simulation. OP10 carries the blank and the three tools.
with ddacs.open_h5(258864, data_dir="data") as f:
    blank_thickness = f["OP10/blank/element_shell_thickness"][-1]
    print("final-timestep thickness:", blank_thickness.shape)
PyTorch integration
DDACSDataset is a torch.utils.data.IterableDataset over a Croissant view. It
auto-shards across DataLoader workers and DDP ranks, and silently skips
simulations whose zip is missing, so partial downloads (like this teaser) stream
cleanly.
from ddacs.pytorch import DDACSDataset
from torch.utils.data import DataLoader

ds = DDACSDataset(view="springback-minimal", data_dir="data")
for batch in DataLoader(ds, batch_size=1, num_workers=0):
    forming    = batch["op10_blank_node_displacement_forming"]
    springback = batch["op10_blank_node_displacement_springback"]
    break
Tutorials
The end-to-end tutorial notebooks live in the GitHub repository and are published on
Read the Docs; on Hugging Face they are bundled in notebooks/, on Kaggle they are the notebooks attached to this dataset:
- Getting started, install, load, first plot.
- Build your own view,
ddacs.add_view, manifest inspection, SIM-KAx provenance. - PyTorch training,
DDACSDataset, filters, train/val/test splits. - Visualization, thickness, components, springback, vectors.
- Loose HDF5 recipe, pandas +
h5pyafter--extract --remove-zip. - Streaming & numpy export,
ddacs.streaming.iter_view,export_to_numpy,load_export. - Streaming & numpy export,
iter_view,export_to_numpy, ~1000× speedup.
Version compatibility
The ddacs package major version tracks the DaRUS dataset major version, enforced
by the bundled Croissant manifest.
| Package | DaRUS dataset |
|---|---|
ddacs 3.x |
v3.0 and any future v3.x updates (current) |
ddacs 2.x |
v1.0 and v2.0 |
Pin the major to the dataset you target, e.g. pip install 'ddacs~=3.0'.
⬇️ Get the full dataset
This sample contains a single simulation. The complete DDACS dataset, 32,466 simulations, ~640 GB of lossless HDF5, with the predefined 25,973 / 3,246 / 3,247 train/val/test split, is hosted on DaRUS with a citable DOI:
➡️ https://doi.org/10.18419/DARUS-4801
Everything you ran here scales to the full release unchanged, just point the same code at the full download, or let the package fetch it:
pip install ddacs
ddacs download            # full release  (ddacs download --small for this 22 MB sample)
Citation
If you use this dataset or code in your research, please cite both the dataset and the paper:
@dataset{baum2025ddacs,
  title={Deep Drawing and Cutting Simulations Dataset},
  subtitle={FEM Simulations of a deep drawn and cut dual phase steel part},
  author={Baum, Sebastian and Heinzelmann, Pascal},
  year={2025}, version={3.0}, publisher={DaRUS},
  doi={10.18419/DARUS-4801}, license={CC BY 4.0},
  url={https://doi.org/10.18419/DARUS-4801}
}

@article{heinzelmann2025benchmark,
  title={A Comprehensive Benchmark Dataset for Sheet Metal Forming: Advancing
         Machine Learning and Surrogate Modelling in Process Simulations},
  author={Heinzelmann, Pascal and Baum, Sebastian and Riedmueller, Kim Rouven
          and Liewald, Mathias and Weyrich, Michael},
  journal={MATEC Web of Conferences}, volume={408}, year={2025}, pages={01090},
  doi={10.1051/matecconf/202540801090},
  url={https://www.matec-conferences.org/articles/matecconf/abs/2025/02/matecconf_iddrg2025_01090/matecconf_iddrg2025_01090.html}
}
License
Data: CC BY 4.0. Package code: MIT.
- Downloads last month
- 564