

UniTranslator: A Unified Multi-modal Framework for End-to-end In-Image Machine Translation
Paper • 2606.24333 • Published
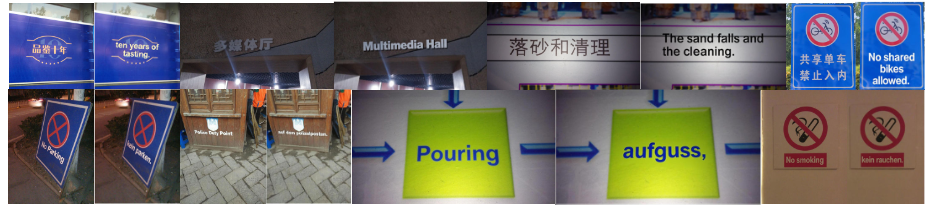
UniTranslator, accepted at ECCV 2026, is an end-to-end framework for in-image machine translation (IIMT). Given an image and a translation instruction, it predicts the translated text and renders that translation back into the source text regions while preserving the surrounding scene, layout, and typography as closely as possible.
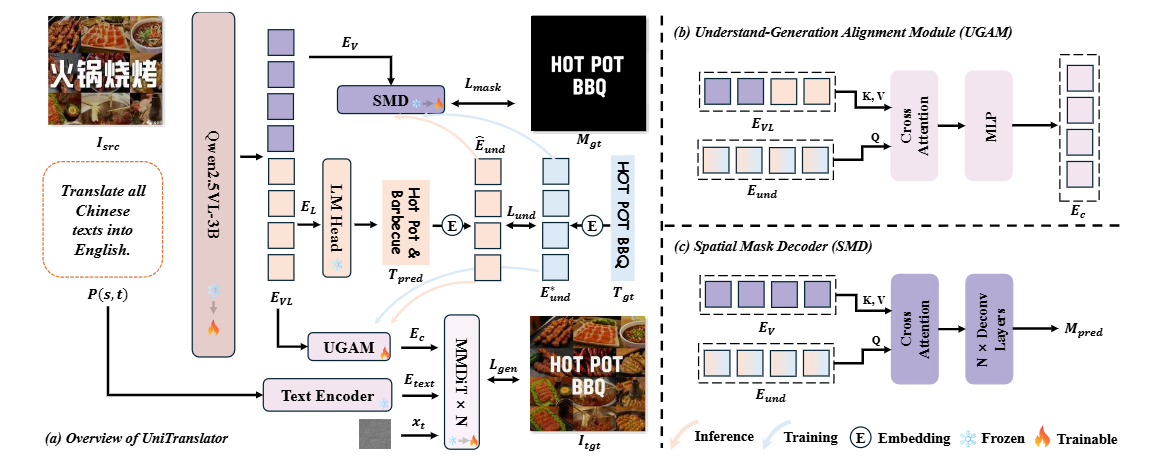
UniTranslator introduces two components:
This repository contains a research checkpoint that uses custom model classes from the GitHub repository. It is not directly compatible with
AutoPipeline.from_pretrained("SeerRay-Lab/Unitranslator")or the hosted Hugging Face Inference API.
| Property | Description |
|---|---|
| Task | End-to-end in-image machine translation |
| Input | Source image, source language, and target language |
| Output | Predicted translation text and an edited image containing the translated text |
| Multimodal backbone | Qwen2.5-VL-3B-based checkpoint |
| Image generator | FLUX.1-Kontext-dev-based denoiser |
| Main components | UGAM and SMD |
| Training | Two-stage warm-up and joint fine-tuning |
| Recommended precision | BF16 |
The released checkpoint combines a multimodal understanding branch, a FLUX-based generation branch, and task-specific alignment and spatial-supervision modules. Inference first autoregressively predicts the translation and then uses the resulting representation to condition image generation.
The paper evaluates the following directions:
De → En)En → De)Fr → En)Ro → En)En → Fr)En → Cs)En → Ru)En → Ro)Other language directions are not guaranteed to provide comparable quality.
| Path | Purpose |
|---|---|
univa/ |
Final combined UniTranslator task checkpoint, including the multimodal model, denoiser, UGAM, and SMD weights |
lora/ |
Rank-64 LoRA adapter used in stage-two Qwen2.5-VL fine-tuning |
denoise_projector.bin |
Standalone denoise-projector/UGAM checkpoint artifact |
pytorch_model/ |
DeepSpeed training state for resuming training |
random_states_*.pkl, scheduler.bin, latest |
Training-resume metadata |
For inference, download univa/ and lora/. The large DeepSpeed optimizer and random-state files are not required.
git clone https://github.com/SeerRay-Lab/Unitranslator.git
cd Unitranslator

conda create -n univa python=3.10 -y
conda activate univa
pip install -r requirements.txt
pip install flash_attn --no-build-isolation
The reference environment uses PyTorch 2.7.1, Transformers 4.57.0, Diffusers 0.32.2, Accelerate 1.5.2, and PEFT 0.10.0.
Download only the files needed for inference:
hf download SeerRay-Lab/Unitranslator \
  --include "univa/*" \
  --include "lora/*" \
  --local-dir checkpoints/Unitranslator
UniTranslator also depends on Qwen2.5-VL-3B-Instruct and FLUX.1-Kontext-dev:
hf download Qwen/Qwen2.5-VL-3B-Instruct \
  --local-dir checkpoints/Qwen2.5-VL-3B-Instruct

hf download black-forest-labs/FLUX.1-Kontext-dev \
  --local-dir checkpoints/FLUX.1-Kontext-dev
FLUX.1-Kontext-dev is gated. You must first accept its license on the model page and authenticate with Hugging Face.
The released inference code reconstructs the base Qwen2.5-VL + FLUX hybrid model before loading the UniTranslator task weights and LoRA adapter:
python scripts/make_univa_qwen2p5vl_tf.py \
  --origin_qwenvl_ckpt_path checkpoints/Qwen2.5-VL-3B-Instruct \
  --origin_flux_ckpt_path checkpoints/FLUX.1-Kontext-dev \
  --save_path checkpoints/UniWorld_Kontext_3b_TF
python infer_dir_tf.py \
  --base_model_path checkpoints/UniWorld_Kontext_3b_TF \
  --lora_adapter_path checkpoints/Unitranslator/lora \
  --flux_finetune_path checkpoints/Unitranslator/univa \
  --flux_base_path checkpoints/FLUX.1-Kontext-dev \
  --input_dir path/to/input_images \
  --output_dir results/de_to_en \
  --gpu_id 0 \
  --total_gpus 1 \
  --source_language German \
  --target_language English \
  --dtype bf16 \
  --height 1024 \
  --width 1024 \
  --num_inference_steps 50 \
  --guidance_scale 5.0
The generated images and a JSONL file containing the predicted translations are written to --output_dir.
For multi-GPU directory inference, launch one process per GPU with different --gpu_id values and the same --total_gpus. Input images are assigned to processes by round-robin sharding.
The prompt format used by the inference script is:
Translate all {source_language} texts into {target_language}.
The paper reports approximately 50 GB peak GPU memory and 9.51 seconds per image under its evaluation setting. Actual memory use and latency depend on resolution, precision, hardware, and inference steps. A high-memory CUDA GPU is recommended.
UniTranslator uses a two-stage training strategy:
The paper reports BF16 mixed precision, AdamW, gradient checkpointing, gradient accumulation of 8, and NVIDIA H800 GPUs. See the configuration files under scripts/denoiser/ for the released training setup.
The repository provides train_stage1.sh and train_stage2.sh as reference launchers. Update their configuration paths for your environment before running them; the checked-in scripts and YAML files contain project-local paths and may require adaptation.
# Stage-one supervision
python convert_en_de.py

# Stage-two mask supervision
python convert_transv_mask.py
Datasets used by the project include:
Users are responsible for complying with the licenses and terms of each dataset.
All numbers below are reported in the UniTranslator paper.
| Direction | BLEU ↑ | Structure-BLEU ↑ | SSIM ↑ |
|---|---|---|---|
| De → En | 25.03 | 24.86 | 0.8184 |
| En → De | 13.41 | 13.36 | 0.7887 |
| Fr → En | 27.77 | 27.14 | 0.8060 |
| Ro → En | 18.45 | 18.29 | 0.8045 |
| Direction | BLEU ↑ | COMET ↑ | FID ↓ |
|---|---|---|---|
| De → En | 14.7 | 59.8 | 8.9 |
| En → De | 13.0 | 45.5 | 12.5 |
| System | Average BLEU ↑ | Average COMET ↑ | Average FID ↓ |
|---|---|---|---|
| Translatotron-V | 1.4 | 32.2 | 69.1 |
| VisTrans | 11.3 | 47.0 | 28.8 |
| UniTranslator | 12.8 | 50.7 | 22.9 |
BLEU and COMET evaluate translation quality, Structure-BLEU additionally considers text-region alignment, SSIM measures source/target structural similarity, and FID evaluates generated-image distribution quality.
The source code repository is released under the Apache 2.0 License.
The released model is based in part on FLUX.1-Kontext-dev. Use of the model weights is therefore also subject to the FLUX.1 Dev Non-Commercial License and its Acceptable Use Policy. Users must comply with all applicable upstream model and dataset licenses; the more restrictive terms apply where relevant.
If you find this work useful, please cite:
@article{lyu2026unitranslator,
  title={UniTranslator: A Unified Multi-modal Framework for End-to-end In-Image Machine Translation},
  author={Lyu, Jiahao and Fu, Pei and Li, Zhenhang and Zhang, Shaojie and Yang, Jiahui and Ma, Can and Zhou, Yu and Luo, Zhenbo and Luan, Jian},
  journal={arXiv preprint arXiv:2606.24333},
  year={2026}
}
This project builds on UniWorld, Qwen2.5-VL, and FLUX.1-Kontext-dev. See the paper and GitHub repository for the complete acknowledgements.
Base model
Qwen/Qwen2.5-VL-3B-Instruct