
EVOKE: Eliciting World Knowledge in Agents for Transferable Decision-Making




Abstract
Large language models (LLMs) are increasingly deployed as agents for multi-step decision-making, yet transfer poorly to unseen environments. World-model methods address this by training agents to predict future observations, at the cost of additional training and errors that compound when predictions are used for planning. However, for LLM agents operating in digital environments, much of this world knowledge is already internalized during pretraining, which shifts the problem from acquiring it to eliciting it. We argue that typical post-training provides little pressure for such elicitation, since supervision under a single goal at each visited state inadvertently drives policies to rely on superficial contextual habits. We introduce EVOKE, a post-training method that supplies this pressure through goal diversity at fixed states. Motivated by theory showing that an agent competent across diverse goals must encode a world model recoverable from its action preferences, EVOKE holds the environment state and interaction history fixed and ranks the same candidate actions under alternative goals, forcing action preferences to change, so that a policy relying on contextual habits or single-goal correlations cannot order them correctly. This implicitly elicits the policy's pretrained world knowledge to inform decisions. We evaluate EVOKE across diverse tasks in three backbones, demonstrating improved task performance, unseen environment generalization, and data efficiency. We further conduct controlled analyses to better understand what drives these gains. These findings offer a new perspective on eliciting internalized world knowledge for transferable action through direct decision supervision.
Community
EVOKE: Eliciting World Knowledge in Agents for Transferable Decision-Making
🌐 Project Page · 📑 Paper · 💡 Idea · 📊 Results · 📝 Citation
EVOKE is a post-training method that elicits the world knowledge already inside pretrained LLM agents, so that they decide by the consequences of their actions rather than by contextual habits. It holds the state fixed, swaps in alternative goals, and trains the policy to rank the same candidate actions under each goal, with no world-model module and no inference-time planning.
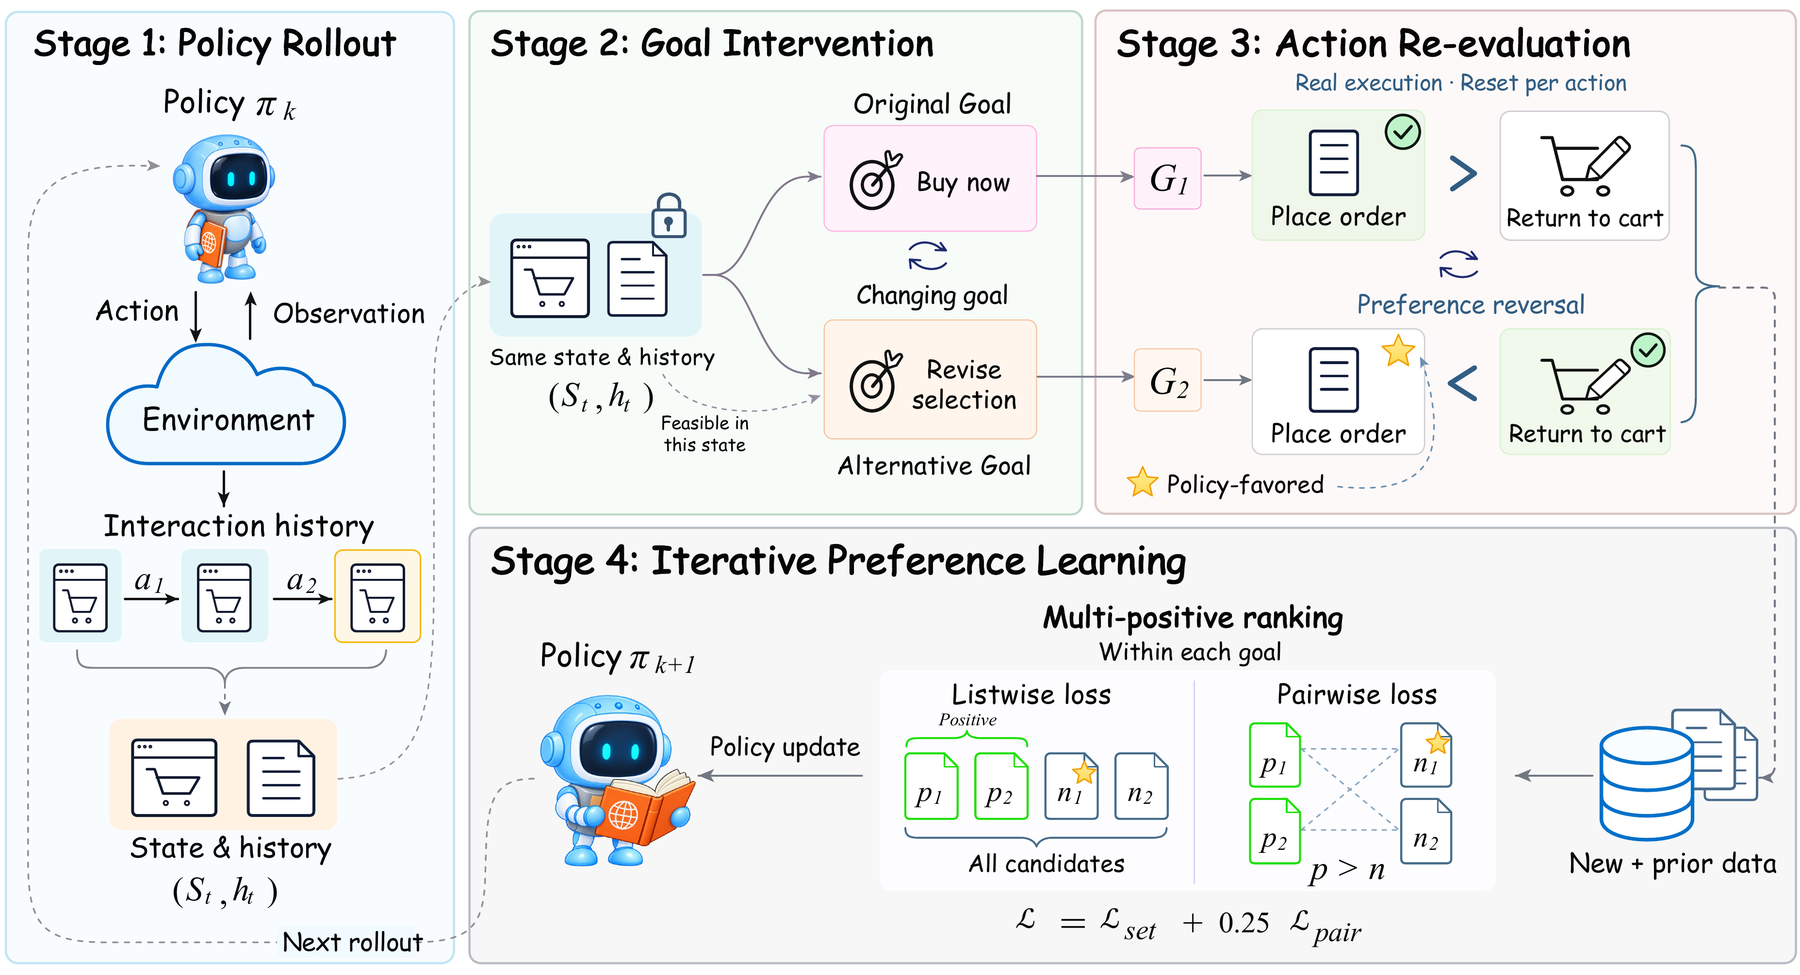
The EVOKE training loop. At collected states, actions are executed and assessed under alternative goals with the state, history, and available actions fixed. The policy learns by contrastive ranking on aggregated preferences; actions can switch between positive and competing across goals.
✨ Highlights
- 🚀 Best across the board — best average on ALFWorld, WebShop, and search-based QA with all three backbones.
- 🌍 Transfers to unseen environments — 91.1% / 93.1% / 84.6% on unseen ALFWorld games (Qwen2.5-3B / 7B / Qwen3-1.7B).
- 🧠 Elicits, not adds, knowledge — the backbone already encodes action consequences; EVOKE makes the policy decide by the goal rather than by habit.
💡 From Prediction to Preference
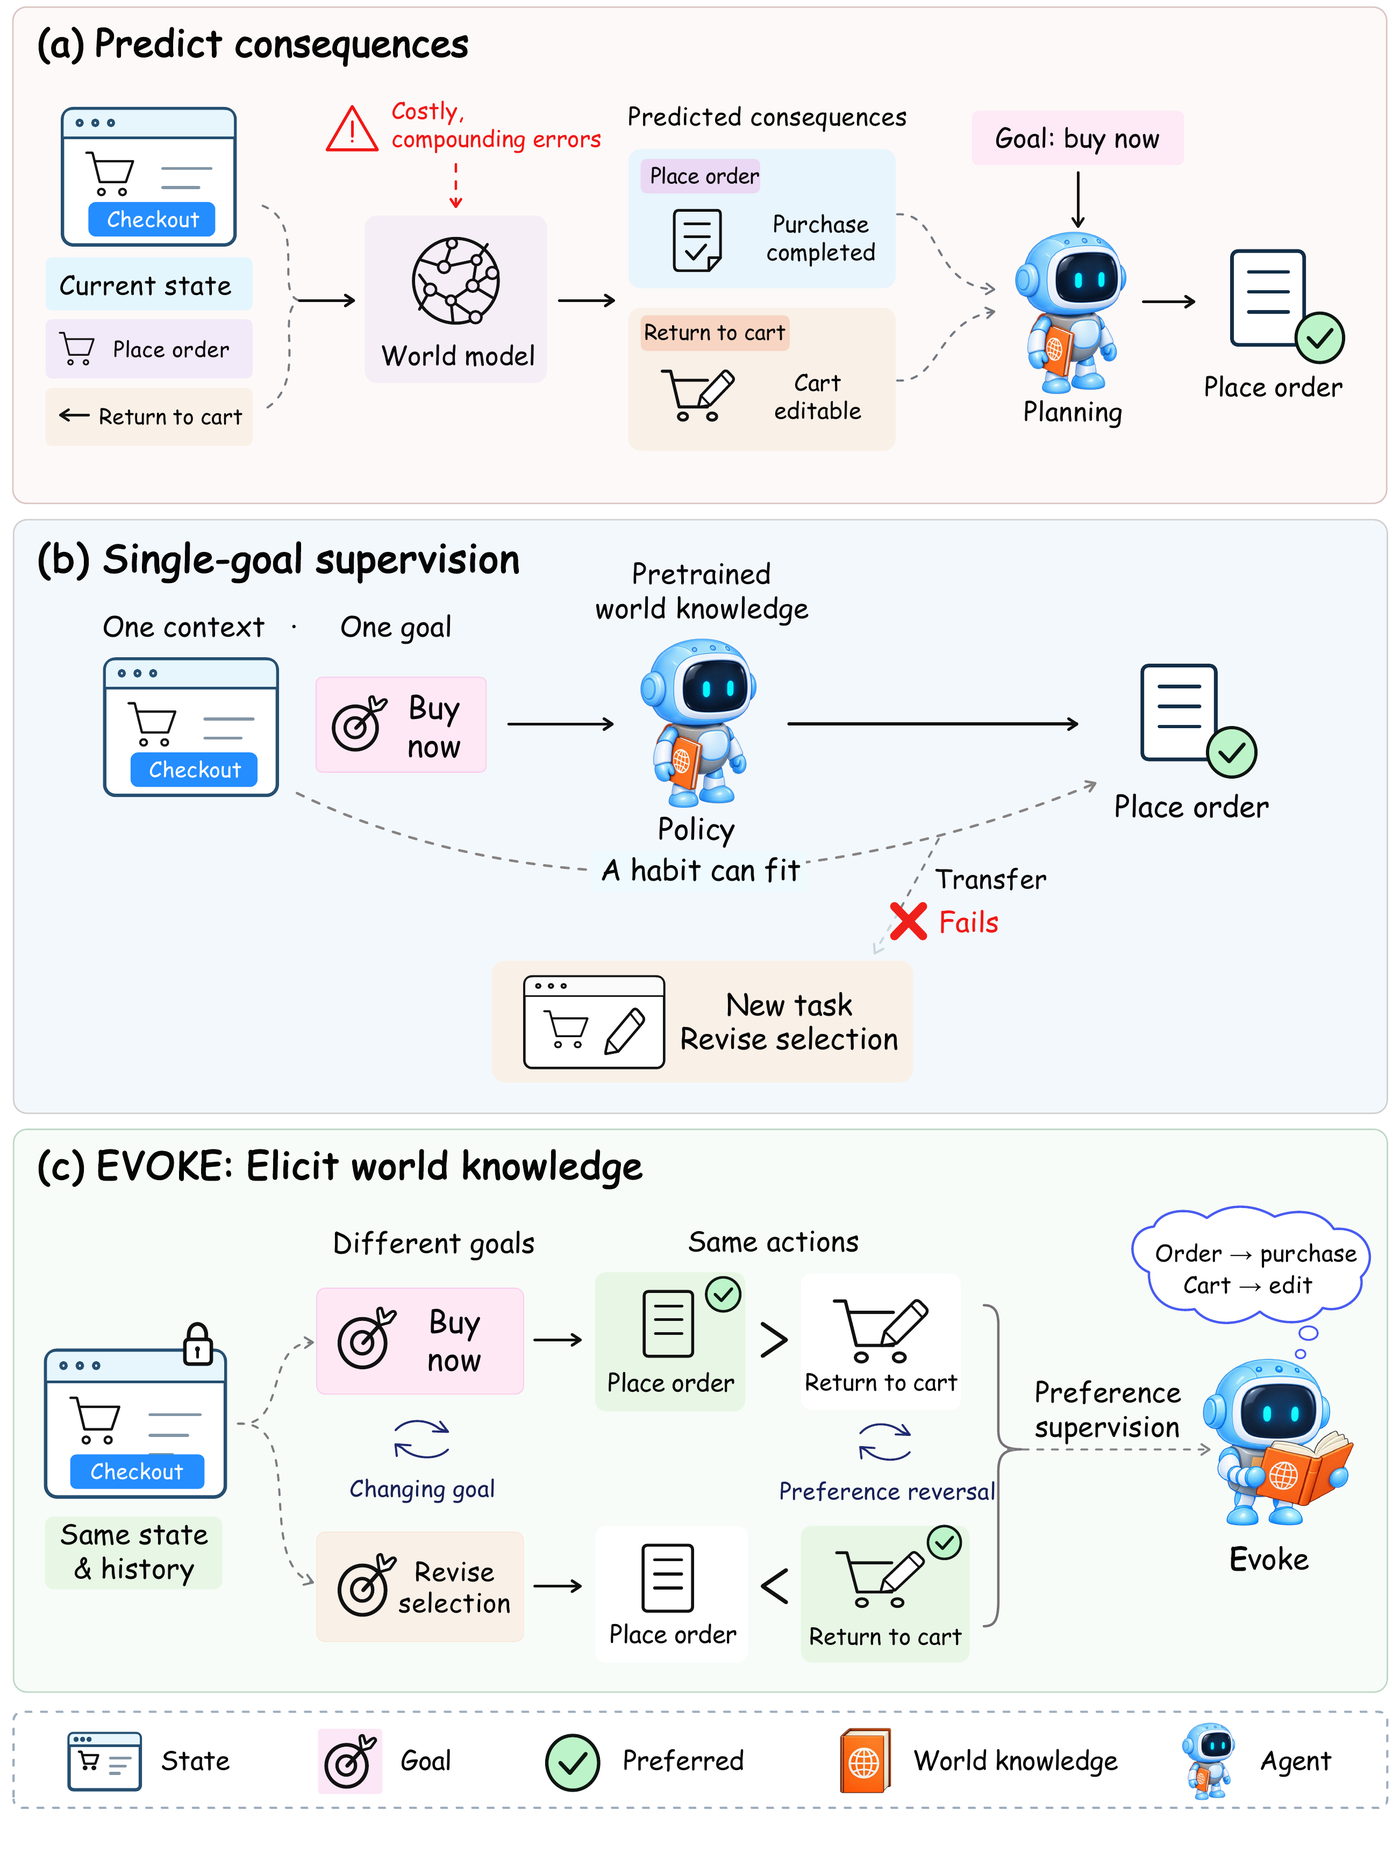 |
Do agents need to predict consequences to use them? (a) Predict consequences. World models learn to predict future observations, adding cost and compounding errors in planning. (b) Single-goal supervision. The knowledge is already in pretrained LLMs, but one goal per state lets the policy fit habits that fail to transfer. (c) EVOKE. Change the goal at a fixed state. Preferences flip, so habits fail and the policy must use its knowledge of consequences. |
📊 Results
Main Results
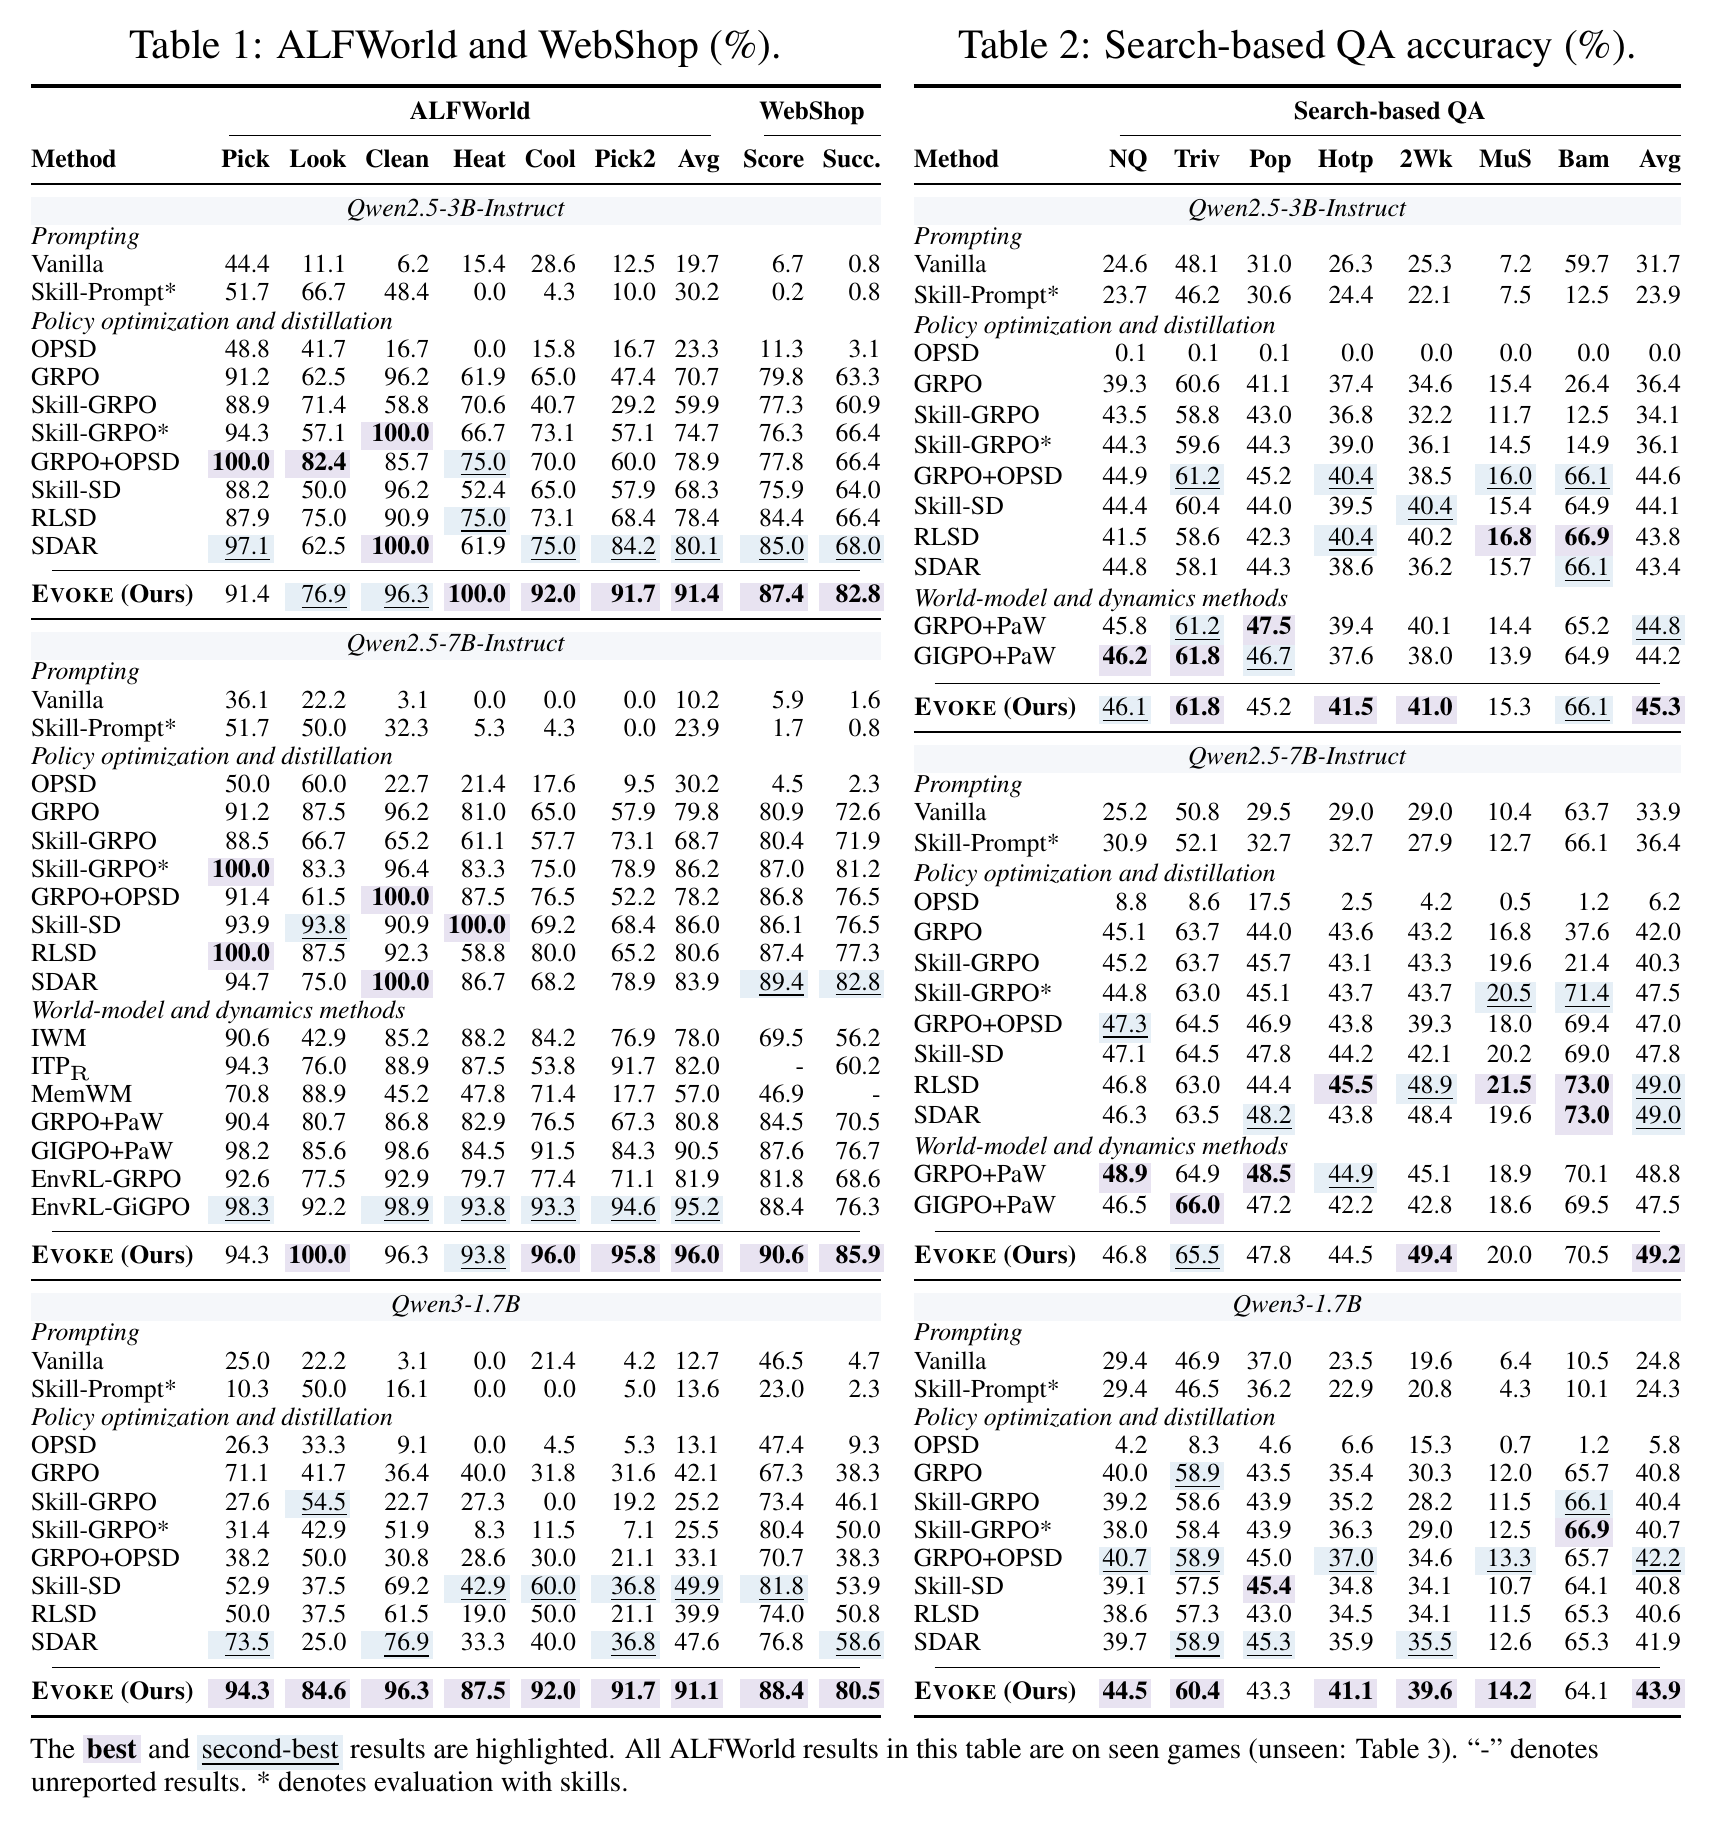
Main results on ALFWorld and WebShop (left) and search-based QA (right) across three backbones.
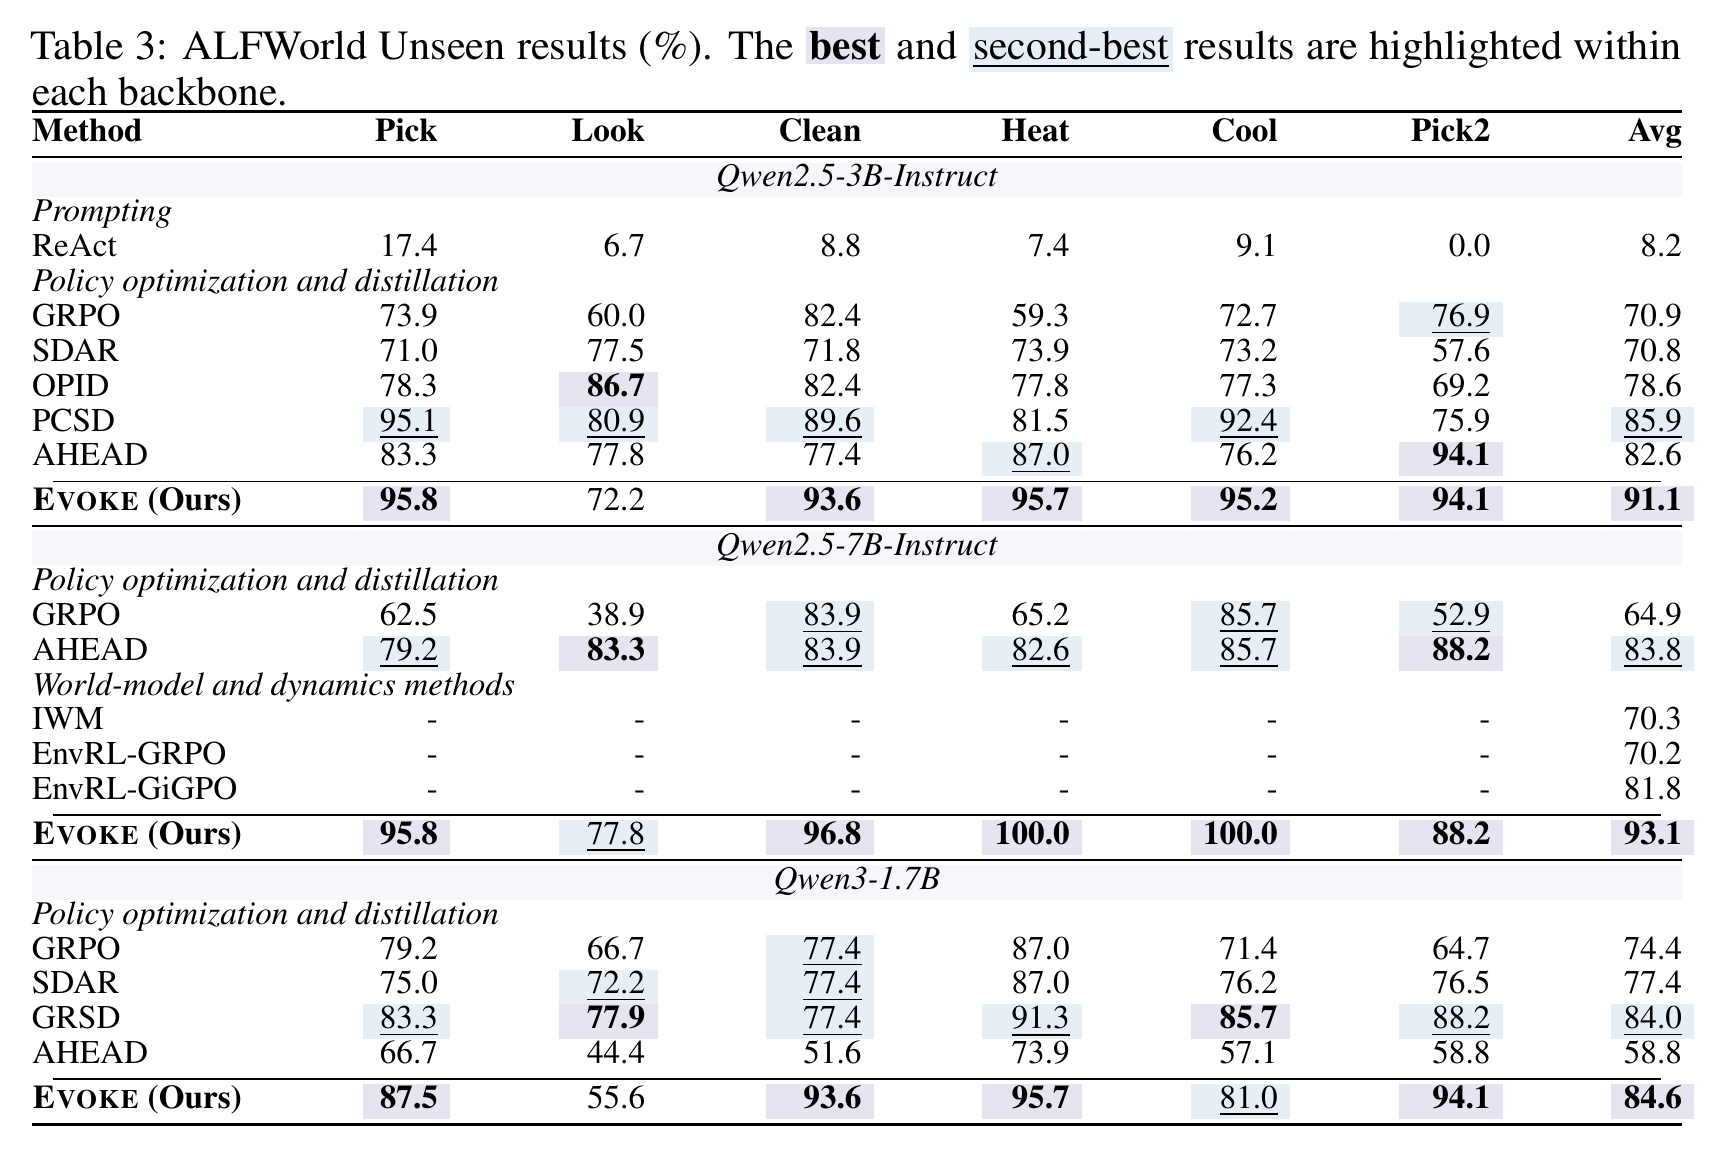
Generalization to unseen ALFWorld games.
Analysis
All analyses use Qwen2.5-3B on ALFWorld unless noted.
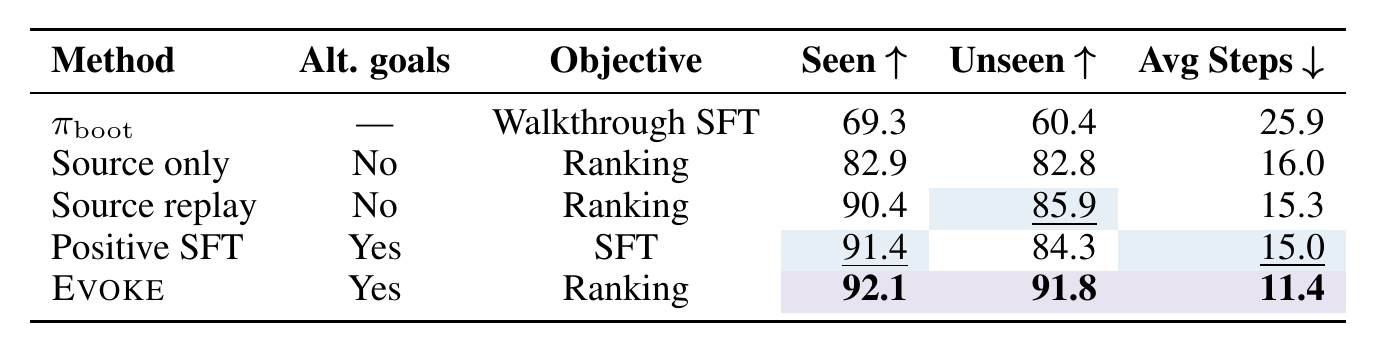
Decision-supervision ablations. Removing alternative goals or replacing ranking with imitation hurts unseen success. Micro success (%) and average unseen steps, averaged over training seeds.
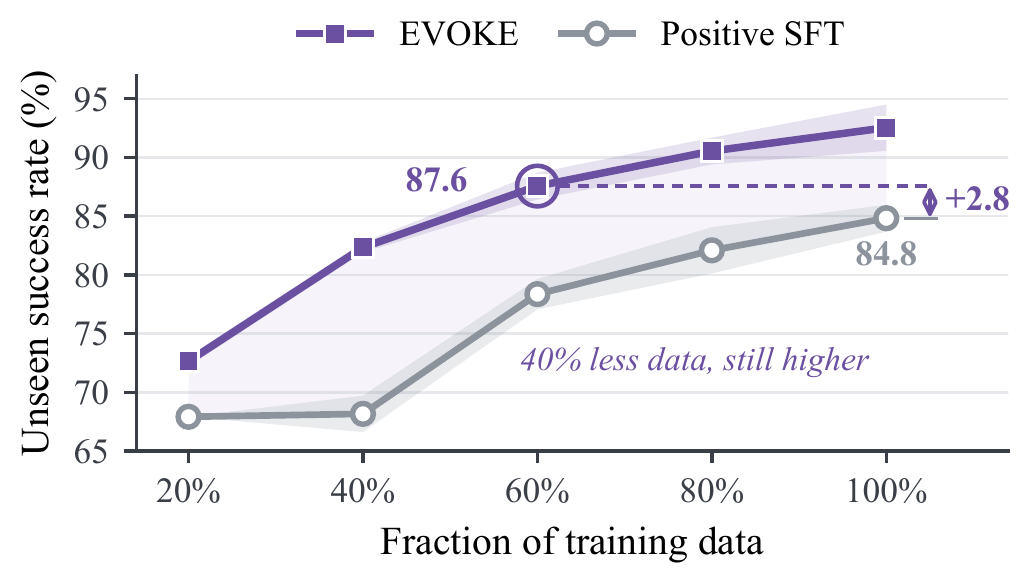 |
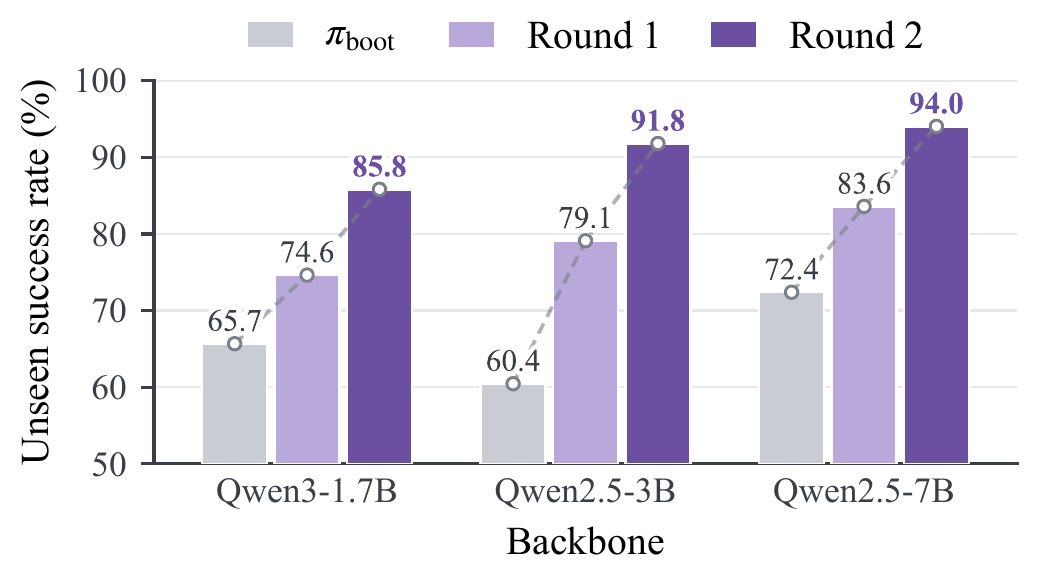 |
| Data efficiency. EVOKE outperforms SFT at every budget. | Iterative improvement. Every round improves every backbone. |
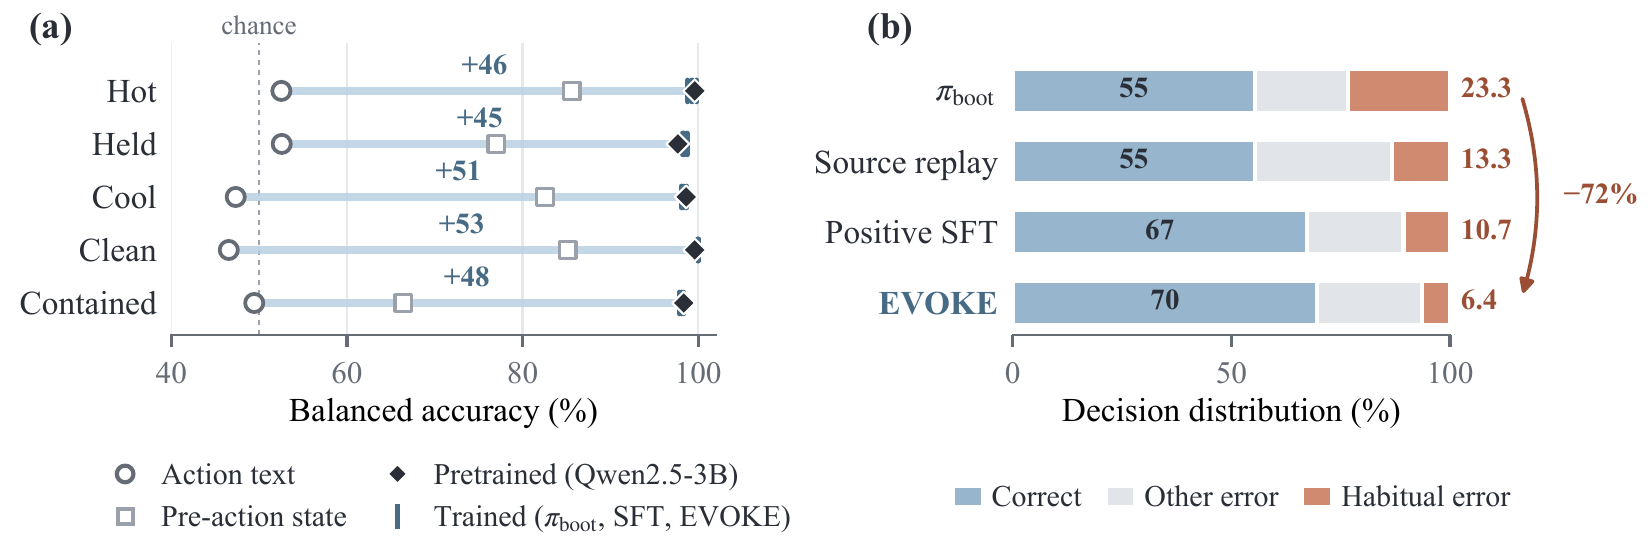
From knowledge to goal-directed decisions. (a) Action consequences are linearly decodable before any ALFWorld training. (b) EVOKE makes the fewest habitual errors, i.e., choosing the action that is correct for another goal in the same context.
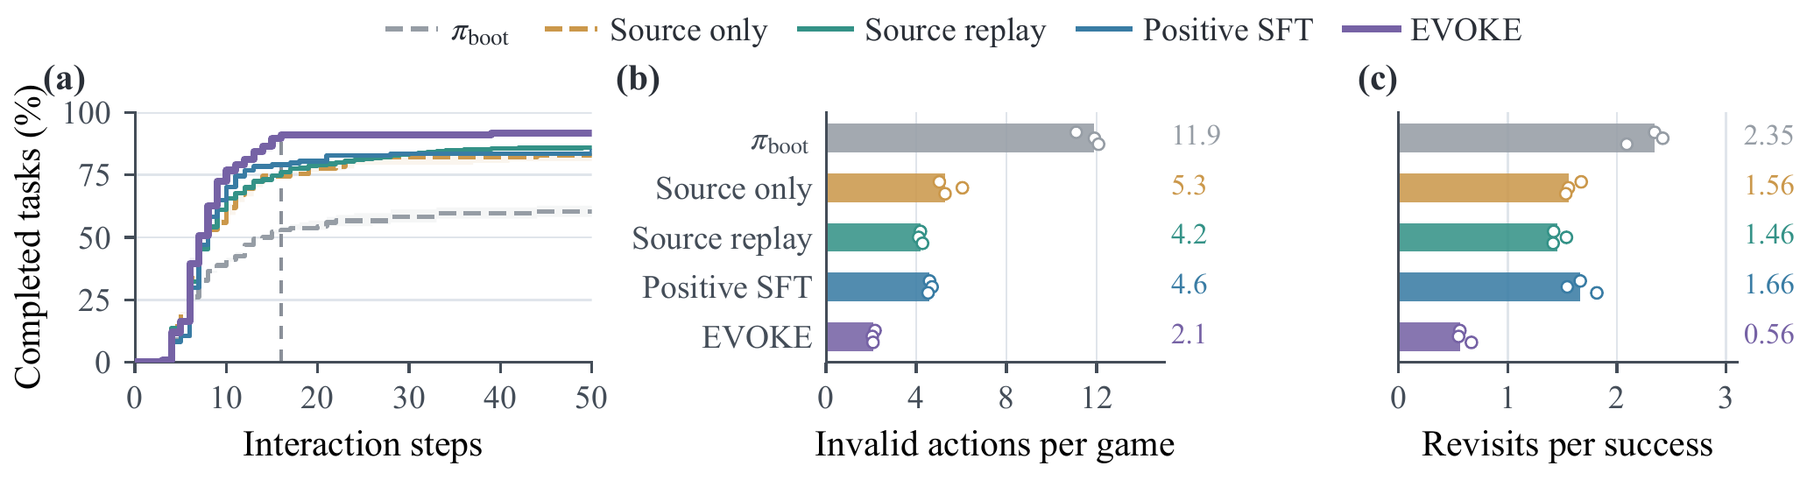
Execution on unseen games. EVOKE succeeds earlier and wastes fewer actions: (a) cumulative success over steps, (b) invalid actions per game, (c) revisits per successful game.
📝 Citation
@article{guo2026evoke,
  title={EVOKE: Eliciting World Knowledge in Agents for Transferable Decision-Making},
  author={Guo, Yuhan and Liu, Jinming and Xu, Liang and Li, Ziqiang and Huang, Jianguo and Wang, Zhicheng and Zhu, Hu and Chen, Qiuyu and Wei, Yuntao and Jin, Xin and Zeng, Wenjun},
  journal={arXiv preprint arXiv:2609.38334},
  year={2026}
}

This is an automated message from the ResearchStudio team.
We created an interactive ResearchStudio Reel for this paper. It includes a visual poster, a video, and a blog, all available for download in editable formats.

Open the ResearchStudio Reel →
Download all files from Hugging Face
Please give this comment a thumbs up if you find the Reel helpful!
Want to explore or create Reels for more papers? Visit the ResearchStudio demo.


Models citing this paper 3
Datasets citing this paper 0
No dataset linking this paper
Spaces citing this paper 0
No Space linking this paper