

Commit ·
0c8695b
0
Parent(s):
Publish MoJev
Browse files- .gitattributes +36 -0
- README.md +200 -0
- browser/comparison.json +111 -0
- browser/embeddings-int8.bin +3 -0
- browser/embeddings-scales.bin +3 -0
- browser/head.onnx +3 -0
- browser/layer-00-q4.onnx +3 -0
- browser/layer-01-q4.onnx +3 -0
- browser/layer-02-q4.onnx +3 -0
- browser/layer-03-q4.onnx +3 -0
- browser/layer-04-q4.onnx +3 -0
- browser/layer-05-q4.onnx +3 -0
- browser/layer-06-q4.onnx +3 -0
- browser/layer-07-q4.onnx +3 -0
- browser/layer-08-q4.onnx +3 -0
- browser/layer-09-q4.onnx +3 -0
- browser/layer-10-q4.onnx +3 -0
- browser/layer-11-q4.onnx +3 -0
- browser/layer-12-q4.onnx +3 -0
- browser/layer-13-q4.onnx +3 -0
- browser/layer-14-q4.onnx +3 -0
- browser/layer-15-q4.onnx +3 -0
- browser/layer-16-q4.onnx +3 -0
- browser/layer-17-q4.onnx +3 -0
- browser/layer-18-q4.onnx +3 -0
- browser/layer-19-q4.onnx +3 -0
- browser/layer-20-q4.onnx +3 -0
- browser/layer-21-q4.onnx +3 -0
- browser/layer-22-q4.onnx +3 -0
- browser/layer-23-q4.onnx +3 -0
- browser/manifest.json +158 -0
- browser/tokenizer.json +3 -0
- browser/tokenizer_config.json +32 -0
- browser/validation.json +242 -0
- chat_template.jinja +154 -0
- config.json +241 -0
- model.safetensors +3 -0
- modeling.py +263 -0
- preprocessor_config.json +21 -0
- schema.py +178 -0
- tokenizer.json +3 -0
- tokenizer_config.json +32 -0
- video_preprocessor_config.json +21 -0
.gitattributes
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,200 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
pretty_name: MoJev
|
| 4 |
+
base_model: Qwen/Qwen3.5-0.8B
|
| 5 |
+
datasets:
|
| 6 |
+
- MoLeMo-Lab/mojev-mix
|
| 7 |
+
library_name: transformers
|
| 8 |
+
pipeline_tag: text-classification
|
| 9 |
+
tags:
|
| 10 |
+
- calibration
|
| 11 |
+
- structured-output
|
| 12 |
+
- multiple-choice
|
| 13 |
+
- preference-learning
|
| 14 |
+
- multimodal
|
| 15 |
+
- mojev
|
| 16 |
+
model-index:
|
| 17 |
+
- name: MoJev
|
| 18 |
+
results:
|
| 19 |
+
- task:
|
| 20 |
+
type: text-classification
|
| 21 |
+
name: Typed decision scoring
|
| 22 |
+
dataset:
|
| 23 |
+
type: MoLeMo-Lab/mojev-mix
|
| 24 |
+
name: MoJev-Mix test
|
| 25 |
+
split: test
|
| 26 |
+
metrics:
|
| 27 |
+
- type: accuracy
|
| 28 |
+
value: 0.9323
|
| 29 |
+
name: Accuracy
|
| 30 |
+
---
|
| 31 |
+
|
| 32 |
+
<img align="right" src="https://molemo-lab.github.io/mojev/assets/molemo-logo.png" width="76" alt="MoLeMo Lab logo">
|
| 33 |
+
|
| 34 |
+
# MoJev
|
| 35 |
+
|
| 36 |
+
[](https://molemo-lab.github.io/mojev/)
|
| 37 |
+
[](https://huggingface.co/spaces/di-zhang-fdu/mojev)
|
| 38 |
+
[](https://github.com/MoLeMo-Lab/mojev/blob/master/paper/mojev-preprint.pdf)
|
| 39 |
+
[](https://github.com/MoLeMo-Lab/mojev)
|
| 40 |
+
[](https://huggingface.co/datasets/MoLeMo-Lab/mojev-mix)
|
| 41 |
+
|
| 42 |
+
**Typed, calibrated decisions in one forward pass.**
|
| 43 |
+
|
| 44 |
+
Contact: [contact@molemo.org](mailto:contact@molemo.org)
|
| 45 |
+
|
| 46 |
+
This is the trained checkpoint for the
|
| 47 |
+
[`mojev`](https://github.com/MoLeMo-Lab/mojev) runtime. It scores
|
| 48 |
+
request-time candidate values from unstructured state and returns schema-bound
|
| 49 |
+
probability distributions.
|
| 50 |
+
|
| 51 |
+
| MoJev family resource | location |
|
| 52 |
+
|---|---|
|
| 53 |
+
| Code | [MoLeMo-Lab/mojev](https://github.com/MoLeMo-Lab/mojev) |
|
| 54 |
+
| Model | **MoLeMo-Lab/mojev** |
|
| 55 |
+
| Dataset | [MoLeMo-Lab/mojev-mix](https://huggingface.co/datasets/MoLeMo-Lab/mojev-mix) |
|
| 56 |
+
| Results | [MoJev results](https://github.com/MoLeMo-Lab/mojev#results) |
|
| 57 |
+
| Preprint | [MoJev (PDF)](https://github.com/MoLeMo-Lab/mojev/blob/master/paper/mojev-preprint.pdf) |
|
| 58 |
+
| Project page | [MoJev](https://molemo-lab.github.io/mojev/) |
|
| 59 |
+
|
| 60 |
+
## Interactive demo
|
| 61 |
+
|
| 62 |
+
[Try MoJev on Hugging Face Spaces](https://huggingface.co/spaces/di-zhang-fdu/mojev):
|
| 63 |
+
text, one or multiple images, a question, and custom candidates are scored on
|
| 64 |
+
server-side ZeroGPU. No model weights are downloaded to the browser.
|
| 65 |
+
|
| 66 |
+
The optional [`browser/`](browser) text export uses asymmetric INT4 linear weights,
|
| 67 |
+
INT8 token embeddings, and an FP32 decision head. Export scripts and numerical comparisons are described in
|
| 68 |
+
the [browser guide](https://github.com/MoLeMo-Lab/mojev/tree/master/browser).
|
| 69 |
+
|
| 70 |
+
## Model contract
|
| 71 |
+
|
| 72 |
+
| input | released configuration |
|
| 73 |
+
|---|---|
|
| 74 |
+
| state | text and local image references; 16,384-token training truncation |
|
| 75 |
+
| question | instruction text |
|
| 76 |
+
| candidates | request-time strings |
|
| 77 |
+
| output | logits decoded as `Choice`, `Noul`, or `Score` distributions |
|
| 78 |
+
|
| 79 |
+
Candidate names are supplied by the caller and encoded directly from their text.
|
| 80 |
+
|
| 81 |
+
MoJev's Qwen3.5 backbone supports 262,144 tokens natively and up to
|
| 82 |
+
1,010,000 tokens with [YaRN scaling](https://github.com/vllm-project/recipes/blob/main/Qwen/Qwen3.5.md).
|
| 83 |
+
The checkpoint records the 16,384-token training window. The MoJev runtime
|
| 84 |
+
accepts a larger inference state window through `--context-tokens`; the packed
|
| 85 |
+
sequence also includes question and candidate tokens.
|
| 86 |
+
|
| 87 |
+
## Run with the MoJev server
|
| 88 |
+
|
| 89 |
+
```sh
|
| 90 |
+
git clone https://github.com/MoLeMo-Lab/mojev
|
| 91 |
+
cd mojev
|
| 92 |
+
pip install -e '.[transformers]'
|
| 93 |
+
|
| 94 |
+
mojev serve MoLeMo-Lab/mojev --port 8000
|
| 95 |
+
```
|
| 96 |
+
|
| 97 |
+
For a longer state within the native context:
|
| 98 |
+
|
| 99 |
+
```sh
|
| 100 |
+
mojev serve MoLeMo-Lab/mojev --port 8000 --context-tokens 65536
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
```python
|
| 104 |
+
from typesafe_sdk import Choice, TypeSafeClient
|
| 105 |
+
|
| 106 |
+
with TypeSafeClient(api_key="local", base_url="http://127.0.0.1:8000") as client:
|
| 107 |
+
result = client.system_one(
|
| 108 |
+
state={"document": "I was charged twice. Please fix this ASAP."},
|
| 109 |
+
questions={
|
| 110 |
+
"category": Choice(
|
| 111 |
+
instructions="What is this ticket about?",
|
| 112 |
+
criteria={"billing": None, "technical": None, "other": None},
|
| 113 |
+
)
|
| 114 |
+
},
|
| 115 |
+
)
|
| 116 |
+
|
| 117 |
+
print(result.choices["category"].choice)
|
| 118 |
+
print(result.choices["category"].probabilities)
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
## Load with Transformers
|
| 122 |
+
|
| 123 |
+
```python
|
| 124 |
+
from transformers import AutoModel, AutoProcessor
|
| 125 |
+
|
| 126 |
+
model = AutoModel.from_pretrained(
|
| 127 |
+
"MoLeMo-Lab/mojev",
|
| 128 |
+
trust_remote_code=True,
|
| 129 |
+
).to("cuda").eval()
|
| 130 |
+
processor = AutoProcessor.from_pretrained(
|
| 131 |
+
"MoLeMo-Lab/mojev",
|
| 132 |
+
trust_remote_code=True,
|
| 133 |
+
)
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
The model directory contains the scorer implementation through `auto_map`.
|
| 137 |
+
Packing, candidate sorting, and schema decoding are provided by the
|
| 138 |
+
[`mojev`](https://github.com/MoLeMo-Lab/mojev) package.
|
| 139 |
+
|
| 140 |
+
## Multimodal input
|
| 141 |
+
|
| 142 |
+
```sh
|
| 143 |
+
pip install -e '.[transformers]'
|
| 144 |
+
mojev serve MoLeMo-Lab/mojev --port 8000
|
| 145 |
+
```
|
| 146 |
+
|
| 147 |
+
Use the image marker followed by an absolute path in the request state:
|
| 148 |
+
|
| 149 |
+
```python
|
| 150 |
+
from pathlib import Path
|
| 151 |
+
|
| 152 |
+
image = Path("examples/cat.jpg").resolve()
|
| 153 |
+
state = f"Identify the subject. <|vision_start|><|image_pad|><|vision_end|>{image}"
|
| 154 |
+
```
|
| 155 |
+
|
| 156 |
+
The processor expands the image into visual patch tokens in the state branch.
|
| 157 |
+
Every question and candidate in the request can attend to those tokens.
|
| 158 |
+
|
| 159 |
+
| candidate set | grey image P(cat) | cat image P(cat) |
|
| 160 |
+
|---|---:|---:|
|
| 161 |
+
| `cat`, `dog` | 0.471 | **0.786** |
|
| 162 |
+
| `cat`, `dog`, `car`, `other` | 0.264 | **0.528** |
|
| 163 |
+
|
| 164 |
+
## Evaluation
|
| 165 |
+
|
| 166 |
+
On 12,000 evaluation decisions, the released checkpoint reaches **93.23%**
|
| 167 |
+
accuracy with **0.79%** expected calibration error.
|
| 168 |
+
|
| 169 |
+
## Architecture
|
| 170 |
+
|
| 171 |
+
|
| 172 |
+
|
| 173 |
+
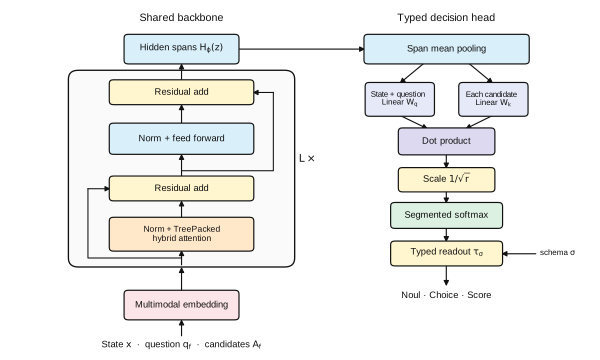
- Base: Qwen3.5-0.8B; all 854,036,544 parameters trained.
|
| 174 |
+
- Packing: state, questions, and candidates in one sequence.
|
| 175 |
+
- Attention: tree mask with isolated question/candidate branches.
|
| 176 |
+
- Readout: rank-512 context and candidate projections with scaled dot product.
|
| 177 |
+
- Objective: Plackett–Luce ranking plus Brier calibration loss.
|
| 178 |
+
- Precision: bf16 encoder and fp32 readout.
|
| 179 |
+
|
| 180 |
+
## Training
|
| 181 |
+
|
| 182 |
+
| item | value |
|
| 183 |
+
|---|---|
|
| 184 |
+
| data | 205,084 rows from 18 Open-Jev generators |
|
| 185 |
+
| epochs | 1 |
|
| 186 |
+
| parallelism | 8-way data parallel |
|
| 187 |
+
| learning rate | 1e-5 |
|
| 188 |
+
| state truncation | 16,384 tokens |
|
| 189 |
+
| Brier weight | 1.0 |
|
| 190 |
+
| wall time | 47 minutes |
|
| 191 |
+
|
| 192 |
+
## Applications
|
| 193 |
+
|
| 194 |
+
- routing and triage;
|
| 195 |
+
- policy and evidence classification;
|
| 196 |
+
- tool and workflow selection;
|
| 197 |
+
- calibrated execution, deferral, and escalation thresholds;
|
| 198 |
+
- multiple typed decisions over shared state.
|
| 199 |
+
|
| 200 |
+
Code is MIT licensed. The Qwen base model license applies to the checkpoint.
|
browser/comparison.json
ADDED
|
@@ -0,0 +1,111 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"source_revision": "d439315bd9a11409584e16758bb76a9d75b5bea7",
|
| 3 |
+
"source_encoder_dtype": "torch.bfloat16",
|
| 4 |
+
"scope": "Four English/Chinese text cases for numerical comparison.",
|
| 5 |
+
"cases": [
|
| 6 |
+
{
|
| 7 |
+
"context": "The customer was charged twice for the same order and wants the duplicate payment returned.",
|
| 8 |
+
"question": "Which team should handle this request?",
|
| 9 |
+
"candidates": [
|
| 10 |
+
"Billing",
|
| 11 |
+
"Technical support",
|
| 12 |
+
"Sales"
|
| 13 |
+
],
|
| 14 |
+
"tokens": 40,
|
| 15 |
+
"reference": [
|
| 16 |
+
0.9212515354156494,
|
| 17 |
+
0.04107579588890076,
|
| 18 |
+
0.037672750651836395
|
| 19 |
+
],
|
| 20 |
+
"quantized": [
|
| 21 |
+
0.8891163468360901,
|
| 22 |
+
0.05538984015583992,
|
| 23 |
+
0.05549393594264984
|
| 24 |
+
],
|
| 25 |
+
"quantized_logits": [
|
| 26 |
+
2.8020951747894287,
|
| 27 |
+
0.0262632817029953,
|
| 28 |
+
0.028140777722001076
|
| 29 |
+
],
|
| 30 |
+
"top1_agrees": true,
|
| 31 |
+
"max_probability_error": 0.032135188579559326,
|
| 32 |
+
"onnx_cpu_seconds": 0.33495458390098065
|
| 33 |
+
},
|
| 34 |
+
{
|
| 35 |
+
"context": "The red box is empty. The blue box contains the key.",
|
| 36 |
+
"question": "Which box contains the key?",
|
| 37 |
+
"candidates": [
|
| 38 |
+
"The red box",
|
| 39 |
+
"The blue box"
|
| 40 |
+
],
|
| 41 |
+
"tokens": 39,
|
| 42 |
+
"reference": [
|
| 43 |
+
0.020697807893157005,
|
| 44 |
+
0.9793022274971008
|
| 45 |
+
],
|
| 46 |
+
"quantized": [
|
| 47 |
+
0.03171052783727646,
|
| 48 |
+
0.9682894349098206
|
| 49 |
+
],
|
| 50 |
+
"quantized_logits": [
|
| 51 |
+
0.6149787306785583,
|
| 52 |
+
4.03386116027832
|
| 53 |
+
],
|
| 54 |
+
"top1_agrees": true,
|
| 55 |
+
"max_probability_error": 0.011012792587280273,
|
| 56 |
+
"onnx_cpu_seconds": 0.2776173329912126
|
| 57 |
+
},
|
| 58 |
+
{
|
| 59 |
+
"context": "A parcel must arrive by Friday. Express delivery arrives Thursday; standard delivery arrives Monday.",
|
| 60 |
+
"question": "Which delivery option meets the deadline?",
|
| 61 |
+
"candidates": [
|
| 62 |
+
"Express delivery",
|
| 63 |
+
"Standard delivery"
|
| 64 |
+
],
|
| 65 |
+
"tokens": 40,
|
| 66 |
+
"reference": [
|
| 67 |
+
0.30602750182151794,
|
| 68 |
+
0.6939724683761597
|
| 69 |
+
],
|
| 70 |
+
"quantized": [
|
| 71 |
+
0.26124119758605957,
|
| 72 |
+
0.7387588024139404
|
| 73 |
+
],
|
| 74 |
+
"quantized_logits": [
|
| 75 |
+
2.2718594074249268,
|
| 76 |
+
3.311386823654175
|
| 77 |
+
],
|
| 78 |
+
"top1_agrees": true,
|
| 79 |
+
"max_probability_error": 0.04478633403778076,
|
| 80 |
+
"onnx_cpu_seconds": 0.2724832500098273
|
| 81 |
+
},
|
| 82 |
+
{
|
| 83 |
+
"context": "用户说:订单被重复扣款,希望退回多付的钱。",
|
| 84 |
+
"question": "应该把请求转给哪个团队?",
|
| 85 |
+
"candidates": [
|
| 86 |
+
"账单与退款",
|
| 87 |
+
"技术支持",
|
| 88 |
+
"销售咨询"
|
| 89 |
+
],
|
| 90 |
+
"tokens": 47,
|
| 91 |
+
"reference": [
|
| 92 |
+
0.9347994327545166,
|
| 93 |
+
0.04668309539556503,
|
| 94 |
+
0.018517442047595978
|
| 95 |
+
],
|
| 96 |
+
"quantized": [
|
| 97 |
+
0.8895391821861267,
|
| 98 |
+
0.08191443234682083,
|
| 99 |
+
0.028546439483761787
|
| 100 |
+
],
|
| 101 |
+
"quantized_logits": [
|
| 102 |
+
2.27278733253479,
|
| 103 |
+
-0.11224094033241272,
|
| 104 |
+
-1.166383981704712
|
| 105 |
+
],
|
| 106 |
+
"top1_agrees": true,
|
| 107 |
+
"max_probability_error": 0.04526025056838989,
|
| 108 |
+
"onnx_cpu_seconds": 0.360311041935347
|
| 109 |
+
}
|
| 110 |
+
]
|
| 111 |
+
}
|
browser/embeddings-int8.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5032e7a0fc5a8624f72e4ed92786993ab74deb8bdb6623f02e0a38b70ea401c6
|
| 3 |
+
size 254279680
|
browser/embeddings-scales.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5aebec9840f73cf88236eaff35b9a28cc1cd64021d4c8c19152d5959270864fb
|
| 3 |
+
size 993280
|
browser/head.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:57f4f82d356d5bb5d9165a5790c864072eb3b32227715219aed7cea52d136046
|
| 3 |
+
size 4211043
|
browser/layer-00-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:339a24722fb2d0bb1e1e7c209c6fc381c42c7a711c2622768232675a7771cac0
|
| 3 |
+
size 13930999
|
browser/layer-01-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a61bbd7b5b407f1ff175d9b8a879bfbfa5174ad4c8f430a789e3245563c645ff
|
| 3 |
+
size 13930999
|
browser/layer-02-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:26d20e1fa8d16cab9d8cf93fc050bd12cc6cc90947518d9c87b37456c5f7ad6a
|
| 3 |
+
size 13930999
|
browser/layer-03-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a720bbcf1eb03fc444864b73cd3d3f97c4846c8e8f3a05c011ad9d3ca8bc3dd4
|
| 3 |
+
size 11847926
|
browser/layer-04-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b83acd1c46dc4136146b5dc4858a1b2ddd28e15d77b601057872536c53f43163
|
| 3 |
+
size 13930999
|
browser/layer-05-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b378e6f362e93c2eee3b8600eafc569e9e623798f1448280d36d8658f558ad77
|
| 3 |
+
size 13930999
|
browser/layer-06-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e78c6f6f138f8d60a54bb8fe9821588166ccf69296655cabadd64d45b642dd6c
|
| 3 |
+
size 13930999
|
browser/layer-07-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:76e3461b9c56d3b7eed6a192b5faebf9a2f9a980324bc9091cb8c55abf74a368
|
| 3 |
+
size 11847926
|
browser/layer-08-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c89020a7bdf5b9709a897d61895f583576e6be3fef9ddc53331eb22fa2f7a049
|
| 3 |
+
size 13930999
|
browser/layer-09-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5e2b111dee724f586eb4da7b954fad89cb3f1fccbc94e1ea7165b4f2ecd86b54
|
| 3 |
+
size 13930999
|
browser/layer-10-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d1020ff2d1ec8f9572837b6c467a5a31721b434e78060fff8cc76d9fa0e658b3
|
| 3 |
+
size 13930999
|
browser/layer-11-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3ae7203a0c8ef7ac9b4a8a6fcb5c203e8ba0b0be61de137b1e5ba462a73d7f3f
|
| 3 |
+
size 11847926
|
browser/layer-12-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2359186f1b54f2937c7c01a56819e3ce0ea63b3e5ad162dbb58c4bcfcdb940bf
|
| 3 |
+
size 13930999
|
browser/layer-13-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b84c3ce848e84be4f125dc3bc5db46043cd974188138fe7adec1ef1e6e486b3c
|
| 3 |
+
size 13930999
|
browser/layer-14-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b2a9b8c5007d032154b982f734e6905a3422dd22e48823d29bcf82dd2d575389
|
| 3 |
+
size 13930999
|
browser/layer-15-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:deb8c1d059a7ca2911ad68174ec673c4bf00b0396fb62f4fb05e38428461480b
|
| 3 |
+
size 11847926
|
browser/layer-16-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:25a08af6d7432e07eec78017e3fe3750ffc4e5e67fd16aae5a07ee35576eb3eb
|
| 3 |
+
size 13930999
|
browser/layer-17-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7a92793c044d96f3983b710f4acc8483a78abaa71214c65704d7fcc76710833d
|
| 3 |
+
size 13930999
|
browser/layer-18-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:36f34165d21862b08b11898ed189c6e6a7f2f8f19faa87b361d1b70e41f1124f
|
| 3 |
+
size 13930999
|
browser/layer-19-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:19ea7c9a796dacbec7a733a897e2919cbf78522f414f698aa531414e873b77e0
|
| 3 |
+
size 11847926
|
browser/layer-20-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fcee1290c07ed2b56daddea42021520b3a4675c287c685dc021a349aa366f16a
|
| 3 |
+
size 13930999
|
browser/layer-21-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:61df1d01e2afe4f372f81df2905e0b671de2b95c2cb0140184869684074d5e3a
|
| 3 |
+
size 13930999
|
browser/layer-22-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ad9093090c30af97d1d809f48ed05f13c3f3e0f32134b0a7c488ff62954e039f
|
| 3 |
+
size 13930999
|
browser/layer-23-q4.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:99f2d5d78d8df94895ecd394b060a2ba8e688394f8bd057fb6185d01c4579c4f
|
| 3 |
+
size 11847926
|
browser/manifest.json
ADDED
|
@@ -0,0 +1,158 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "mojev-browser-v1",
|
| 3 |
+
"source": "MoLeMo-Lab/mojev",
|
| 4 |
+
"source_revision": "d439315bd9a11409584e16758bb76a9d75b5bea7",
|
| 5 |
+
"source_sha256": "eae27bf03e0e44501316cafab2406b1505732ddf4b836d19fbb8deb642f55f50",
|
| 6 |
+
"width": 1024,
|
| 7 |
+
"layer_types": [
|
| 8 |
+
"linear_attention",
|
| 9 |
+
"linear_attention",
|
| 10 |
+
"linear_attention",
|
| 11 |
+
"full_attention",
|
| 12 |
+
"linear_attention",
|
| 13 |
+
"linear_attention",
|
| 14 |
+
"linear_attention",
|
| 15 |
+
"full_attention",
|
| 16 |
+
"linear_attention",
|
| 17 |
+
"linear_attention",
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"full_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"linear_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"full_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"linear_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"full_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"linear_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"full_attention"
|
| 32 |
+
],
|
| 33 |
+
"precision": {
|
| 34 |
+
"layers": "asymmetric int4, block 32",
|
| 35 |
+
"embeddings": "int8 per row",
|
| 36 |
+
"head": "float32"
|
| 37 |
+
},
|
| 38 |
+
"modality": "text",
|
| 39 |
+
"files": {
|
| 40 |
+
"embeddings-int8.bin": {
|
| 41 |
+
"bytes": 254279680,
|
| 42 |
+
"sha256": "5032e7a0fc5a8624f72e4ed92786993ab74deb8bdb6623f02e0a38b70ea401c6"
|
| 43 |
+
},
|
| 44 |
+
"embeddings-scales.bin": {
|
| 45 |
+
"bytes": 993280,
|
| 46 |
+
"sha256": "5aebec9840f73cf88236eaff35b9a28cc1cd64021d4c8c19152d5959270864fb"
|
| 47 |
+
},
|
| 48 |
+
"head.onnx": {
|
| 49 |
+
"bytes": 4211043,
|
| 50 |
+
"sha256": "57f4f82d356d5bb5d9165a5790c864072eb3b32227715219aed7cea52d136046"
|
| 51 |
+
},
|
| 52 |
+
"tokenizer.json": {
|
| 53 |
+
"bytes": 19989325,
|
| 54 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 55 |
+
},
|
| 56 |
+
"tokenizer_config.json": {
|
| 57 |
+
"bytes": 1124,
|
| 58 |
+
"sha256": "66e427c470fe580fe8c7b5725d857af23d8417e37fae62667ec698306a19987b"
|
| 59 |
+
},
|
| 60 |
+
"layer-00-q4.onnx": {
|
| 61 |
+
"bytes": 13930999,
|
| 62 |
+
"sha256": "339a24722fb2d0bb1e1e7c209c6fc381c42c7a711c2622768232675a7771cac0"
|
| 63 |
+
},
|
| 64 |
+
"layer-01-q4.onnx": {
|
| 65 |
+
"bytes": 13930999,
|
| 66 |
+
"sha256": "a61bbd7b5b407f1ff175d9b8a879bfbfa5174ad4c8f430a789e3245563c645ff"
|
| 67 |
+
},
|
| 68 |
+
"layer-02-q4.onnx": {
|
| 69 |
+
"bytes": 13930999,
|
| 70 |
+
"sha256": "26d20e1fa8d16cab9d8cf93fc050bd12cc6cc90947518d9c87b37456c5f7ad6a"
|
| 71 |
+
},
|
| 72 |
+
"layer-03-q4.onnx": {
|
| 73 |
+
"bytes": 11847926,
|
| 74 |
+
"sha256": "a720bbcf1eb03fc444864b73cd3d3f97c4846c8e8f3a05c011ad9d3ca8bc3dd4"
|
| 75 |
+
},
|
| 76 |
+
"layer-04-q4.onnx": {
|
| 77 |
+
"bytes": 13930999,
|
| 78 |
+
"sha256": "b83acd1c46dc4136146b5dc4858a1b2ddd28e15d77b601057872536c53f43163"
|
| 79 |
+
},
|
| 80 |
+
"layer-05-q4.onnx": {
|
| 81 |
+
"bytes": 13930999,
|
| 82 |
+
"sha256": "b378e6f362e93c2eee3b8600eafc569e9e623798f1448280d36d8658f558ad77"
|
| 83 |
+
},
|
| 84 |
+
"layer-06-q4.onnx": {
|
| 85 |
+
"bytes": 13930999,
|
| 86 |
+
"sha256": "e78c6f6f138f8d60a54bb8fe9821588166ccf69296655cabadd64d45b642dd6c"
|
| 87 |
+
},
|
| 88 |
+
"layer-07-q4.onnx": {
|
| 89 |
+
"bytes": 11847926,
|
| 90 |
+
"sha256": "76e3461b9c56d3b7eed6a192b5faebf9a2f9a980324bc9091cb8c55abf74a368"
|
| 91 |
+
},
|
| 92 |
+
"layer-08-q4.onnx": {
|
| 93 |
+
"bytes": 13930999,
|
| 94 |
+
"sha256": "c89020a7bdf5b9709a897d61895f583576e6be3fef9ddc53331eb22fa2f7a049"
|
| 95 |
+
},
|
| 96 |
+
"layer-09-q4.onnx": {
|
| 97 |
+
"bytes": 13930999,
|
| 98 |
+
"sha256": "5e2b111dee724f586eb4da7b954fad89cb3f1fccbc94e1ea7165b4f2ecd86b54"
|
| 99 |
+
},
|
| 100 |
+
"layer-10-q4.onnx": {
|
| 101 |
+
"bytes": 13930999,
|
| 102 |
+
"sha256": "d1020ff2d1ec8f9572837b6c467a5a31721b434e78060fff8cc76d9fa0e658b3"
|
| 103 |
+
},
|
| 104 |
+
"layer-11-q4.onnx": {
|
| 105 |
+
"bytes": 11847926,
|
| 106 |
+
"sha256": "3ae7203a0c8ef7ac9b4a8a6fcb5c203e8ba0b0be61de137b1e5ba462a73d7f3f"
|
| 107 |
+
},
|
| 108 |
+
"layer-12-q4.onnx": {
|
| 109 |
+
"bytes": 13930999,
|
| 110 |
+
"sha256": "2359186f1b54f2937c7c01a56819e3ce0ea63b3e5ad162dbb58c4bcfcdb940bf"
|
| 111 |
+
},
|
| 112 |
+
"layer-13-q4.onnx": {
|
| 113 |
+
"bytes": 13930999,
|
| 114 |
+
"sha256": "b84c3ce848e84be4f125dc3bc5db46043cd974188138fe7adec1ef1e6e486b3c"
|
| 115 |
+
},
|
| 116 |
+
"layer-14-q4.onnx": {
|
| 117 |
+
"bytes": 13930999,
|
| 118 |
+
"sha256": "b2a9b8c5007d032154b982f734e6905a3422dd22e48823d29bcf82dd2d575389"
|
| 119 |
+
},
|
| 120 |
+
"layer-15-q4.onnx": {
|
| 121 |
+
"bytes": 11847926,
|
| 122 |
+
"sha256": "deb8c1d059a7ca2911ad68174ec673c4bf00b0396fb62f4fb05e38428461480b"
|
| 123 |
+
},
|
| 124 |
+
"layer-16-q4.onnx": {
|
| 125 |
+
"bytes": 13930999,
|
| 126 |
+
"sha256": "25a08af6d7432e07eec78017e3fe3750ffc4e5e67fd16aae5a07ee35576eb3eb"
|
| 127 |
+
},
|
| 128 |
+
"layer-17-q4.onnx": {
|
| 129 |
+
"bytes": 13930999,
|
| 130 |
+
"sha256": "7a92793c044d96f3983b710f4acc8483a78abaa71214c65704d7fcc76710833d"
|
| 131 |
+
},
|
| 132 |
+
"layer-18-q4.onnx": {
|
| 133 |
+
"bytes": 13930999,
|
| 134 |
+
"sha256": "36f34165d21862b08b11898ed189c6e6a7f2f8f19faa87b361d1b70e41f1124f"
|
| 135 |
+
},
|
| 136 |
+
"layer-19-q4.onnx": {
|
| 137 |
+
"bytes": 11847926,
|
| 138 |
+
"sha256": "19ea7c9a796dacbec7a733a897e2919cbf78522f414f698aa531414e873b77e0"
|
| 139 |
+
},
|
| 140 |
+
"layer-20-q4.onnx": {
|
| 141 |
+
"bytes": 13930999,
|
| 142 |
+
"sha256": "fcee1290c07ed2b56daddea42021520b3a4675c287c685dc021a349aa366f16a"
|
| 143 |
+
},
|
| 144 |
+
"layer-21-q4.onnx": {
|
| 145 |
+
"bytes": 13930999,
|
| 146 |
+
"sha256": "61df1d01e2afe4f372f81df2905e0b671de2b95c2cb0140184869684074d5e3a"
|
| 147 |
+
},
|
| 148 |
+
"layer-22-q4.onnx": {
|
| 149 |
+
"bytes": 13930999,
|
| 150 |
+
"sha256": "ad9093090c30af97d1d809f48ed05f13c3f3e0f32134b0a7c488ff62954e039f"
|
| 151 |
+
},
|
| 152 |
+
"layer-23-q4.onnx": {
|
| 153 |
+
"bytes": 11847926,
|
| 154 |
+
"sha256": "99f2d5d78d8df94895ecd394b060a2ba8e688394f8bd057fb6185d01c4579c4f"
|
| 155 |
+
}
|
| 156 |
+
},
|
| 157 |
+
"semantics": "Matches the pinned Transformers scorer: full-attention layers use the tree mask; linear-attention layers use sequential recurrence."
|
| 158 |
+
}
|
browser/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
browser/tokenizer_config.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"unk_token": null,
|
| 29 |
+
"video_token": "<|video_pad|>",
|
| 30 |
+
"vision_bos_token": "<|vision_start|>",
|
| 31 |
+
"vision_eos_token": "<|vision_end|>"
|
| 32 |
+
}
|
browser/validation.json
ADDED
|
@@ -0,0 +1,242 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"layer": 0,
|
| 4 |
+
"length": 5,
|
| 5 |
+
"max_abs_error": 4.76837158203125e-07
|
| 6 |
+
},
|
| 7 |
+
{
|
| 8 |
+
"layer": 0,
|
| 9 |
+
"length": 13,
|
| 10 |
+
"max_abs_error": 4.76837158203125e-07
|
| 11 |
+
},
|
| 12 |
+
{
|
| 13 |
+
"layer": 1,
|
| 14 |
+
"length": 5,
|
| 15 |
+
"max_abs_error": 5.364418029785156e-07
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"layer": 1,
|
| 19 |
+
"length": 13,
|
| 20 |
+
"max_abs_error": 5.960464477539062e-07
|
| 21 |
+
},
|
| 22 |
+
{
|
| 23 |
+
"layer": 2,
|
| 24 |
+
"length": 5,
|
| 25 |
+
"max_abs_error": 3.5762786865234375e-07
|
| 26 |
+
},
|
| 27 |
+
{
|
| 28 |
+
"layer": 2,
|
| 29 |
+
"length": 13,
|
| 30 |
+
"max_abs_error": 4.76837158203125e-07
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"layer": 3,
|
| 34 |
+
"length": 5,
|
| 35 |
+
"max_abs_error": 9.5367431640625e-07
|
| 36 |
+
},
|
| 37 |
+
{
|
| 38 |
+
"layer": 3,
|
| 39 |
+
"length": 13,
|
| 40 |
+
"max_abs_error": 1.3113021850585938e-06
|
| 41 |
+
},
|
| 42 |
+
{
|
| 43 |
+
"layer": 4,
|
| 44 |
+
"length": 5,
|
| 45 |
+
"max_abs_error": 4.76837158203125e-07
|
| 46 |
+
},
|
| 47 |
+
{
|
| 48 |
+
"layer": 4,
|
| 49 |
+
"length": 13,
|
| 50 |
+
"max_abs_error": 5.960464477539062e-07
|
| 51 |
+
},
|
| 52 |
+
{
|
| 53 |
+
"layer": 5,
|
| 54 |
+
"length": 5,
|
| 55 |
+
"max_abs_error": 4.76837158203125e-07
|
| 56 |
+
},
|
| 57 |
+
{
|
| 58 |
+
"layer": 5,
|
| 59 |
+
"length": 13,
|
| 60 |
+
"max_abs_error": 4.76837158203125e-07
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"layer": 6,
|
| 64 |
+
"length": 5,
|
| 65 |
+
"max_abs_error": 4.76837158203125e-07
|
| 66 |
+
},
|
| 67 |
+
{
|
| 68 |
+
"layer": 6,
|
| 69 |
+
"length": 13,
|
| 70 |
+
"max_abs_error": 4.76837158203125e-07
|
| 71 |
+
},
|
| 72 |
+
{
|
| 73 |
+
"layer": 7,
|
| 74 |
+
"length": 5,
|
| 75 |
+
"max_abs_error": 4.76837158203125e-07
|
| 76 |
+
},
|
| 77 |
+
{
|
| 78 |
+
"layer": 7,
|
| 79 |
+
"length": 13,
|
| 80 |
+
"max_abs_error": 4.76837158203125e-07
|
| 81 |
+
},
|
| 82 |
+
{
|
| 83 |
+
"layer": 8,
|
| 84 |
+
"length": 5,
|
| 85 |
+
"max_abs_error": 5.960464477539062e-07
|
| 86 |
+
},
|
| 87 |
+
{
|
| 88 |
+
"layer": 8,
|
| 89 |
+
"length": 13,
|
| 90 |
+
"max_abs_error": 4.76837158203125e-07
|
| 91 |
+
},
|
| 92 |
+
{
|
| 93 |
+
"layer": 9,
|
| 94 |
+
"length": 5,
|
| 95 |
+
"max_abs_error": 2.384185791015625e-07
|
| 96 |
+
},
|
| 97 |
+
{
|
| 98 |
+
"layer": 9,
|
| 99 |
+
"length": 13,
|
| 100 |
+
"max_abs_error": 4.76837158203125e-07
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"layer": 10,
|
| 104 |
+
"length": 5,
|
| 105 |
+
"max_abs_error": 2.384185791015625e-07
|
| 106 |
+
},
|
| 107 |
+
{
|
| 108 |
+
"layer": 10,
|
| 109 |
+
"length": 13,
|
| 110 |
+
"max_abs_error": 4.76837158203125e-07
|
| 111 |
+
},
|
| 112 |
+
{
|
| 113 |
+
"layer": 11,
|
| 114 |
+
"length": 5,
|
| 115 |
+
"max_abs_error": 5.364418029785156e-07
|
| 116 |
+
},
|
| 117 |
+
{
|
| 118 |
+
"layer": 11,
|
| 119 |
+
"length": 13,
|
| 120 |
+
"max_abs_error": 7.152557373046875e-07
|
| 121 |
+
},
|
| 122 |
+
{
|
| 123 |
+
"layer": 12,
|
| 124 |
+
"length": 5,
|
| 125 |
+
"max_abs_error": 4.76837158203125e-07
|
| 126 |
+
},
|
| 127 |
+
{
|
| 128 |
+
"layer": 12,
|
| 129 |
+
"length": 13,
|
| 130 |
+
"max_abs_error": 4.76837158203125e-07
|
| 131 |
+
},
|
| 132 |
+
{
|
| 133 |
+
"layer": 13,
|
| 134 |
+
"length": 5,
|
| 135 |
+
"max_abs_error": 4.76837158203125e-07
|
| 136 |
+
},
|
| 137 |
+
{
|
| 138 |
+
"layer": 13,
|
| 139 |
+
"length": 13,
|
| 140 |
+
"max_abs_error": 4.76837158203125e-07
|
| 141 |
+
},
|
| 142 |
+
{
|
| 143 |
+
"layer": 14,
|
| 144 |
+
"length": 5,
|
| 145 |
+
"max_abs_error": 4.76837158203125e-07
|
| 146 |
+
},
|
| 147 |
+
{
|
| 148 |
+
"layer": 14,
|
| 149 |
+
"length": 13,
|
| 150 |
+
"max_abs_error": 5.960464477539062e-07
|
| 151 |
+
},
|
| 152 |
+
{
|
| 153 |
+
"layer": 15,
|
| 154 |
+
"length": 5,
|
| 155 |
+
"max_abs_error": 9.5367431640625e-07
|
| 156 |
+
},
|
| 157 |
+
{
|
| 158 |
+
"layer": 15,
|
| 159 |
+
"length": 13,
|
| 160 |
+
"max_abs_error": 8.940696716308594e-07
|
| 161 |
+
},
|
| 162 |
+
{
|
| 163 |
+
"layer": 16,
|
| 164 |
+
"length": 5,
|
| 165 |
+
"max_abs_error": 4.76837158203125e-07
|
| 166 |
+
},
|
| 167 |
+
{
|
| 168 |
+
"layer": 16,
|
| 169 |
+
"length": 13,
|
| 170 |
+
"max_abs_error": 7.450580596923828e-07
|
| 171 |
+
},
|
| 172 |
+
{
|
| 173 |
+
"layer": 17,
|
| 174 |
+
"length": 5,
|
| 175 |
+
"max_abs_error": 5.513429641723633e-07
|
| 176 |
+
},
|
| 177 |
+
{
|
| 178 |
+
"layer": 17,
|
| 179 |
+
"length": 13,
|
| 180 |
+
"max_abs_error": 5.960464477539062e-07
|
| 181 |
+
},
|
| 182 |
+
{
|
| 183 |
+
"layer": 18,
|
| 184 |
+
"length": 5,
|
| 185 |
+
"max_abs_error": 7.152557373046875e-07
|
| 186 |
+
},
|
| 187 |
+
{
|
| 188 |
+
"layer": 18,
|
| 189 |
+
"length": 13,
|
| 190 |
+
"max_abs_error": 7.152557373046875e-07
|
| 191 |
+
},
|
| 192 |
+
{
|
| 193 |
+
"layer": 19,
|
| 194 |
+
"length": 5,
|
| 195 |
+
"max_abs_error": 1.862645149230957e-06
|
| 196 |
+
},
|
| 197 |
+
{
|
| 198 |
+
"layer": 19,
|
| 199 |
+
"length": 13,
|
| 200 |
+
"max_abs_error": 2.1457672119140625e-06
|
| 201 |
+
},
|
| 202 |
+
{
|
| 203 |
+
"layer": 20,
|
| 204 |
+
"length": 5,
|
| 205 |
+
"max_abs_error": 6.556510925292969e-07
|
| 206 |
+
},
|
| 207 |
+
{
|
| 208 |
+
"layer": 20,
|
| 209 |
+
"length": 13,
|
| 210 |
+
"max_abs_error": 7.152557373046875e-07
|
| 211 |
+
},
|
| 212 |
+
{
|
| 213 |
+
"layer": 21,
|
| 214 |
+
"length": 5,
|
| 215 |
+
"max_abs_error": 9.5367431640625e-07
|
| 216 |
+
},
|
| 217 |
+
{
|
| 218 |
+
"layer": 21,
|
| 219 |
+
"length": 13,
|
| 220 |
+
"max_abs_error": 8.940696716308594e-07
|
| 221 |
+
},
|
| 222 |
+
{
|
| 223 |
+
"layer": 22,
|
| 224 |
+
"length": 5,
|
| 225 |
+
"max_abs_error": 9.5367431640625e-07
|
| 226 |
+
},
|
| 227 |
+
{
|
| 228 |
+
"layer": 22,
|
| 229 |
+
"length": 13,
|
| 230 |
+
"max_abs_error": 1.1920928955078125e-06
|
| 231 |
+
},
|
| 232 |
+
{
|
| 233 |
+
"layer": 23,
|
| 234 |
+
"length": 5,
|
| 235 |
+
"max_abs_error": 8.344650268554688e-07
|
| 236 |
+
},
|
| 237 |
+
{
|
| 238 |
+
"layer": 23,
|
| 239 |
+
"length": 13,
|
| 240 |
+
"max_abs_error": 1.5497207641601562e-06
|
| 241 |
+
}
|
| 242 |
+
]
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is true %}
|
| 150 |
+
{{- '<think>\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
config.json
ADDED
|
@@ -0,0 +1,241 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"PackedScorer"
|
| 4 |
+
],
|
| 5 |
+
"auto_map": {
|
| 6 |
+
"AutoConfig": "modeling.PackedScorerConfig",
|
| 7 |
+
"AutoModel": "modeling.PackedScorer"
|
| 8 |
+
},
|
| 9 |
+
"context_tokens": 16384,
|
| 10 |
+
"dtype": "bfloat16",
|
| 11 |
+
"encoder_config": {
|
| 12 |
+
"_name_or_path": "Qwen/Qwen3.5-0.8B",
|
| 13 |
+
"architectures": [
|
| 14 |
+
"Qwen3_5ForConditionalGeneration"
|
| 15 |
+
],
|
| 16 |
+
"chunk_size_feed_forward": 0,
|
| 17 |
+
"dtype": "bfloat16",
|
| 18 |
+
"id2label": {
|
| 19 |
+
"0": "LABEL_0",
|
| 20 |
+
"1": "LABEL_1"
|
| 21 |
+
},
|
| 22 |
+
"image_token_id": 248056,
|
| 23 |
+
"is_encoder_decoder": false,
|
| 24 |
+
"label2id": {
|
| 25 |
+
"LABEL_0": 0,
|
| 26 |
+
"LABEL_1": 1
|
| 27 |
+
},
|
| 28 |
+
"model_type": "qwen3_5",
|
| 29 |
+
"output_attentions": false,
|
| 30 |
+
"output_hidden_states": false,
|
| 31 |
+
"problem_type": null,
|
| 32 |
+
"return_dict": true,
|
| 33 |
+
"text_config": {
|
| 34 |
+
"_name_or_path": "",
|
| 35 |
+
"architectures": null,
|
| 36 |
+
"attention_bias": false,
|
| 37 |
+
"attention_dropout": 0.0,
|
| 38 |
+
"attn_output_gate": true,
|
| 39 |
+
"bos_token_id": null,
|
| 40 |
+
"chunk_size_feed_forward": 0,
|
| 41 |
+
"dtype": "bfloat16",
|
| 42 |
+
"eos_token_id": 248044,
|
| 43 |
+
"full_attention_interval": 4,
|
| 44 |
+
"head_dim": 256,
|
| 45 |
+
"hidden_act": "silu",
|
| 46 |
+
"hidden_size": 1024,
|
| 47 |
+
"id2label": {
|
| 48 |
+
"0": "LABEL_0",
|
| 49 |
+
"1": "LABEL_1"
|
| 50 |
+
},
|
| 51 |
+
"initializer_range": 0.02,
|
| 52 |
+
"intermediate_size": 3584,
|
| 53 |
+
"is_encoder_decoder": false,
|
| 54 |
+
"label2id": {
|
| 55 |
+
"LABEL_0": 0,
|
| 56 |
+
"LABEL_1": 1
|
| 57 |
+
},
|
| 58 |
+
"layer_types": [
|
| 59 |
+
"linear_attention",
|
| 60 |
+
"linear_attention",
|
| 61 |
+
"linear_attention",
|
| 62 |
+
"full_attention",
|
| 63 |
+
"linear_attention",
|
| 64 |
+
"linear_attention",
|
| 65 |
+
"linear_attention",
|
| 66 |
+
"full_attention",
|
| 67 |
+
"linear_attention",
|
| 68 |
+
"linear_attention",
|
| 69 |
+
"linear_attention",
|
| 70 |
+
"full_attention",
|
| 71 |
+
"linear_attention",
|
| 72 |
+
"linear_attention",
|
| 73 |
+
"linear_attention",
|
| 74 |
+
"full_attention",
|
| 75 |
+
"linear_attention",
|
| 76 |
+
"linear_attention",
|
| 77 |
+
"linear_attention",
|
| 78 |
+
"full_attention",
|
| 79 |
+
"linear_attention",
|
| 80 |
+
"linear_attention",
|
| 81 |
+
"linear_attention",
|
| 82 |
+
"full_attention"
|
| 83 |
+
],
|
| 84 |
+
"linear_conv_kernel_dim": 4,
|
| 85 |
+
"linear_key_head_dim": 128,
|
| 86 |
+
"linear_num_key_heads": 16,
|
| 87 |
+
"linear_num_value_heads": 16,
|
| 88 |
+
"linear_value_head_dim": 128,
|
| 89 |
+
"mamba_ssm_dtype": "float32",
|
| 90 |
+
"max_position_embeddings": 262144,
|
| 91 |
+
"mlp_only_layers": [],
|
| 92 |
+
"model_type": "qwen3_5_text",
|
| 93 |
+
"mtp_num_hidden_layers": 1,
|
| 94 |
+
"mtp_use_dedicated_embeddings": false,
|
| 95 |
+
"num_attention_heads": 8,
|
| 96 |
+
"num_hidden_layers": 24,
|
| 97 |
+
"num_key_value_heads": 2,
|
| 98 |
+
"output_attentions": false,
|
| 99 |
+
"output_hidden_states": false,
|
| 100 |
+
"pad_token_id": null,
|
| 101 |
+
"partial_rotary_factor": 0.25,
|
| 102 |
+
"problem_type": null,
|
| 103 |
+
"return_dict": true,
|
| 104 |
+
"rms_norm_eps": 1e-06,
|
| 105 |
+
"rope_parameters": {
|
| 106 |
+
"mrope_interleaved": true,
|
| 107 |
+
"mrope_section": [
|
| 108 |
+
11,
|
| 109 |
+
11,
|
| 110 |
+
10
|
| 111 |
+
],
|
| 112 |
+
"partial_rotary_factor": 0.25,
|
| 113 |
+
"rope_theta": 10000000,
|
| 114 |
+
"rope_type": "default"
|
| 115 |
+
},
|
| 116 |
+
"tie_word_embeddings": true,
|
| 117 |
+
"use_cache": true,
|
| 118 |
+
"vocab_size": 248320
|
| 119 |
+
},
|
| 120 |
+
"tie_word_embeddings": true,
|
| 121 |
+
"video_token_id": 248057,
|
| 122 |
+
"vision_config": {
|
| 123 |
+
"_name_or_path": "",
|
| 124 |
+
"architectures": null,
|
| 125 |
+
"chunk_size_feed_forward": 0,
|
| 126 |
+
"deepstack_visual_indexes": [],
|
| 127 |
+
"depth": 12,
|
| 128 |
+
"dtype": "bfloat16",
|
| 129 |
+
"hidden_act": "gelu_pytorch_tanh",
|
| 130 |
+
"hidden_size": 768,
|
| 131 |
+
"id2label": {
|
| 132 |
+
"0": "LABEL_0",
|
| 133 |
+
"1": "LABEL_1"
|
| 134 |
+
},
|
| 135 |
+
"in_channels": 3,
|
| 136 |
+
"initializer_range": 0.02,
|
| 137 |
+
"intermediate_size": 3072,
|
| 138 |
+
"is_encoder_decoder": false,
|
| 139 |
+
"label2id": {
|
| 140 |
+
"LABEL_0": 0,
|
| 141 |
+
"LABEL_1": 1
|
| 142 |
+
},
|
| 143 |
+
"model_type": "qwen3_5_vision",
|
| 144 |
+
"num_heads": 12,
|
| 145 |
+
"num_position_embeddings": 2304,
|
| 146 |
+
"out_hidden_size": 1024,
|
| 147 |
+
"output_attentions": false,
|
| 148 |
+
"output_hidden_states": false,
|
| 149 |
+
"patch_size": 16,
|
| 150 |
+
"problem_type": null,
|
| 151 |
+
"return_dict": true,
|
| 152 |
+
"rope_parameters": {
|
| 153 |
+
"rope_theta": 10000.0,
|
| 154 |
+
"rope_type": "axial"
|
| 155 |
+
},
|
| 156 |
+
"spatial_merge_size": 2,
|
| 157 |
+
"temporal_patch_size": 2
|
| 158 |
+
},
|
| 159 |
+
"vision_end_token_id": 248054,
|
| 160 |
+
"vision_start_token_id": 248053
|
| 161 |
+
},
|
| 162 |
+
"encoder_name": "Qwen/Qwen3.5-0.8B",
|
| 163 |
+
"model_type": "mojev-scorer",
|
| 164 |
+
"rank": 512,
|
| 165 |
+
"schema": {
|
| 166 |
+
"fields": [
|
| 167 |
+
{
|
| 168 |
+
"description": "the option the state and question license",
|
| 169 |
+
"kind": "choice",
|
| 170 |
+
"name": "answer",
|
| 171 |
+
"options": [
|
| 172 |
+
"slot-0",
|
| 173 |
+
"slot-1",
|
| 174 |
+
"slot-2",
|
| 175 |
+
"slot-3",
|
| 176 |
+
"slot-4",
|
| 177 |
+
"slot-5",
|
| 178 |
+
"slot-6",
|
| 179 |
+
"slot-7",
|
| 180 |
+
"slot-8",
|
| 181 |
+
"slot-9",
|
| 182 |
+
"slot-10",
|
| 183 |
+
"slot-11",
|
| 184 |
+
"slot-12",
|
| 185 |
+
"slot-13",
|
| 186 |
+
"slot-14",
|
| 187 |
+
"slot-15",
|
| 188 |
+
"slot-16",
|
| 189 |
+
"slot-17",
|
| 190 |
+
"slot-18",
|
| 191 |
+
"slot-19",
|
| 192 |
+
"slot-20",
|
| 193 |
+
"slot-21",
|
| 194 |
+
"slot-22",
|
| 195 |
+
"slot-23",
|
| 196 |
+
"slot-24",
|
| 197 |
+
"slot-25",
|
| 198 |
+
"slot-26",
|
| 199 |
+
"slot-27",
|
| 200 |
+
"slot-28",
|
| 201 |
+
"slot-29",
|
| 202 |
+
"slot-30",
|
| 203 |
+
"slot-31",
|
| 204 |
+
"slot-32",
|
| 205 |
+
"slot-33",
|
| 206 |
+
"slot-34",
|
| 207 |
+
"slot-35",
|
| 208 |
+
"slot-36",
|
| 209 |
+
"slot-37",
|
| 210 |
+
"slot-38",
|
| 211 |
+
"slot-39",
|
| 212 |
+
"slot-40",
|
| 213 |
+
"slot-41",
|
| 214 |
+
"slot-42",
|
| 215 |
+
"slot-43",
|
| 216 |
+
"slot-44",
|
| 217 |
+
"slot-45",
|
| 218 |
+
"slot-46",
|
| 219 |
+
"slot-47",
|
| 220 |
+
"slot-48",
|
| 221 |
+
"slot-49",
|
| 222 |
+
"slot-50",
|
| 223 |
+
"slot-51",
|
| 224 |
+
"slot-52",
|
| 225 |
+
"slot-53",
|
| 226 |
+
"slot-54",
|
| 227 |
+
"slot-55",
|
| 228 |
+
"slot-56",
|
| 229 |
+
"slot-57",
|
| 230 |
+
"slot-58",
|
| 231 |
+
"slot-59",
|
| 232 |
+
"slot-60",
|
| 233 |
+
"slot-61",
|
| 234 |
+
"slot-62",
|
| 235 |
+
"slot-63"
|
| 236 |
+
]
|
| 237 |
+
}
|
| 238 |
+
]
|
| 239 |
+
},
|
| 240 |
+
"transformers_version": "5.17.0"
|
| 241 |
+
}
|
model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:eae27bf03e0e44501316cafab2406b1505732ddf4b836d19fbb8deb642f55f50
|
| 3 |
+
size 1710234304
|
modeling.py
ADDED
|
@@ -0,0 +1,263 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""The scorer as a HuggingFace model: config, weights, and registration.
|
| 2 |
+
|
| 3 |
+
A checkpoint used to be ``torch.save({"schema", "state_dict", "args"})``, which
|
| 4 |
+
cost three things. Loading one ran arbitrary pickle, because the payload carried
|
| 5 |
+
the training ``args`` beside the tensors and every reader had to pass
|
| 6 |
+
``weights_only=False``. Every load read the pretrained encoder and then threw it
|
| 7 |
+
away -- 4.32 s to fetch 473 tensors that ``load_state_dict`` immediately
|
| 8 |
+
overwrote, against 0.30 s for the same weights through ``from_pretrained``. And
|
| 9 |
+
the layout was private, so four call sites each re-derived it and the encoder's
|
| 10 |
+
identity lived in a free-text ``args`` field rather than in a config, which is
|
| 11 |
+
why every entry point wanted ``--hf-model`` passed alongside the checkpoint.
|
| 12 |
+
|
| 13 |
+
So the model is a ``PreTrainedModel``. ``save_pretrained`` writes
|
| 14 |
+
``config.json`` plus safetensors, ``from_pretrained`` reads them once, the
|
| 15 |
+
encoder config nests inside the model config, and the schema travels with the
|
| 16 |
+
weights. Registration below makes the directory loadable as
|
| 17 |
+
``AutoModel.from_pretrained(path, trust_remote_code=True)`` by anyone with
|
| 18 |
+
transformers and no copy of this package.
|
| 19 |
+
|
| 20 |
+
**Dtypes are mixed and that is load-bearing.** The encoder is bf16; the head --
|
| 21 |
+
``option_proj``, ``context_proj``, ``norm`` -- is fp32, which is how training
|
| 22 |
+
produced it and what ``layer_norm`` needs. Both failure modes here were measured:
|
| 23 |
+
building the model in fp32 before loading upcast the whole encoder, ``F32`` went
|
| 24 |
+
to disk for all 477 tensors, and predictions drifted 4.7e-03; passing
|
| 25 |
+
``dtype=torch.bfloat16`` to ``from_pretrained`` casts the head too and
|
| 26 |
+
``layer_norm`` then raises. The per-module dtype has to come from ``__init__``,
|
| 27 |
+
which is what ``_dtype_for`` below is for.
|
| 28 |
+
"""
|
| 29 |
+
|
| 30 |
+
from __future__ import annotations
|
| 31 |
+
|
| 32 |
+
import torch
|
| 33 |
+
from torch import nn
|
| 34 |
+
from transformers import AutoConfig, AutoModel, PretrainedConfig, PreTrainedModel
|
| 35 |
+
|
| 36 |
+
from .schema import Schema
|
| 37 |
+
|
| 38 |
+
ENCODER_DTYPE = torch.bfloat16
|
| 39 |
+
HEAD_DTYPE = torch.float32
|
| 40 |
+
DEFAULT_TRAINING_CONTEXT_TOKENS = 16_384
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
class PackedScorerConfig(PretrainedConfig):
|
| 44 |
+
"""Everything needed to rebuild the scorer, including the encoder's own config.
|
| 45 |
+
|
| 46 |
+
``schema`` is the JSON ``Schema.to_json`` already produces, so the schema a
|
| 47 |
+
checkpoint was trained with travels with its weights. ``context_tokens``
|
| 48 |
+
records the 16K state budget used in training. Inference callers can select
|
| 49 |
+
a larger state window without changing the model weights. Candidate text
|
| 50 |
+
has no separate token limit.
|
| 51 |
+
"""
|
| 52 |
+
|
| 53 |
+
model_type = "mojev-scorer"
|
| 54 |
+
sub_configs = {"encoder_config": AutoConfig}
|
| 55 |
+
|
| 56 |
+
def __init__(self, encoder_config=None, rank: int = 512, schema=None,
|
| 57 |
+
context_tokens: int = DEFAULT_TRAINING_CONTEXT_TOKENS,
|
| 58 |
+
encoder_name: str | None = None, **kwargs) -> None:
|
| 59 |
+
# from_dict hands back a plain dict; for_model rebuilds the right class
|
| 60 |
+
# using the model_type that to_dict preserved.
|
| 61 |
+
if isinstance(encoder_config, dict):
|
| 62 |
+
encoder_config = AutoConfig.for_model(**encoder_config)
|
| 63 |
+
self.encoder_config = encoder_config
|
| 64 |
+
self.rank = rank
|
| 65 |
+
self.schema = schema
|
| 66 |
+
if context_tokens < 1:
|
| 67 |
+
raise ValueError("context_tokens must be positive")
|
| 68 |
+
self.context_tokens = context_tokens
|
| 69 |
+
kwargs.pop("option_tokens", None)
|
| 70 |
+
# Kept for provenance only. Loading does not consult it -- the weights are
|
| 71 |
+
# in the checkpoint -- but it records which encoder the run started from.
|
| 72 |
+
self.encoder_name = encoder_name
|
| 73 |
+
super().__init__(**kwargs)
|
| 74 |
+
|
| 75 |
+
|
| 76 |
+
class PackedScorer(PreTrainedModel):
|
| 77 |
+
"""Encode context and every option in one sequence, then score each option.
|
| 78 |
+
|
| 79 |
+
Layout per row:
|
| 80 |
+
|
| 81 |
+
[context tokens] [opt 0 tokens] [opt 1 tokens] ... [opt N-1 tokens]
|
| 82 |
+
|
| 83 |
+
The attention mask is block-diagonal over the option spans: an option sees
|
| 84 |
+
the context and itself, never another option. Without that, scores would
|
| 85 |
+
depend on which rivals happened to be present and permutation invariance
|
| 86 |
+
would be gone -- the property that separates this from putting the choices
|
| 87 |
+
in a prompt.
|
| 88 |
+
"""
|
| 89 |
+
|
| 90 |
+
config_class = PackedScorerConfig
|
| 91 |
+
base_model_prefix = "encoder"
|
| 92 |
+
_supports_sdpa = True
|
| 93 |
+
|
| 94 |
+
def __init__(self, config: PackedScorerConfig) -> None:
|
| 95 |
+
super().__init__(config)
|
| 96 |
+
self.encoder = AutoModel.from_config(config.encoder_config, dtype=ENCODER_DTYPE)
|
| 97 |
+
width = self.hidden_size(config.encoder_config)
|
| 98 |
+
self.width = width
|
| 99 |
+
self.rank = config.rank
|
| 100 |
+
self.option_proj = nn.Linear(width, config.rank, bias=False, dtype=HEAD_DTYPE)
|
| 101 |
+
self.context_proj = nn.Linear(width, config.rank, bias=False, dtype=HEAD_DTYPE)
|
| 102 |
+
self.norm = nn.LayerNorm(width, dtype=HEAD_DTYPE)
|
| 103 |
+
# Sets all_tied_weights_keys and the rest of the composite-model state;
|
| 104 |
+
# without it from_pretrained raises AttributeError on the first of them.
|
| 105 |
+
self.post_init()
|
| 106 |
+
|
| 107 |
+
@staticmethod
|
| 108 |
+
def hidden_size(encoder_config) -> int:
|
| 109 |
+
"""Multimodal configs nest the text stack; single-stack ones do not."""
|
| 110 |
+
return getattr(encoder_config, "text_config", encoder_config).hidden_size
|
| 111 |
+
|
| 112 |
+
@property
|
| 113 |
+
def schema(self) -> Schema:
|
| 114 |
+
return Schema.from_json(self.config.schema)
|
| 115 |
+
|
| 116 |
+
@classmethod
|
| 117 |
+
def from_encoder(cls, model_name: str, schema: Schema, rank: int = 512,
|
| 118 |
+
context_tokens: int = DEFAULT_TRAINING_CONTEXT_TOKENS):
|
| 119 |
+
"""Build a fresh scorer on a pretrained encoder -- the training entry point.
|
| 120 |
+
|
| 121 |
+
This is the one path that should read pretrained weights, because starting
|
| 122 |
+
from them is the point. Loading a trained checkpoint goes through
|
| 123 |
+
``from_pretrained`` instead and reads the encoder exactly once.
|
| 124 |
+
"""
|
| 125 |
+
config = PackedScorerConfig(
|
| 126 |
+
encoder_config=AutoConfig.from_pretrained(model_name),
|
| 127 |
+
rank=rank, schema=schema.to_json(), context_tokens=context_tokens,
|
| 128 |
+
encoder_name=str(model_name),
|
| 129 |
+
)
|
| 130 |
+
model = cls(config)
|
| 131 |
+
model.encoder = AutoModel.from_pretrained(model_name, dtype=ENCODER_DTYPE)
|
| 132 |
+
return model
|
| 133 |
+
|
| 134 |
+
def build_mask(self, context_span: torch.Tensor, field_span: torch.Tensor,
|
| 135 |
+
option_span: torch.Tensor) -> torch.Tensor:
|
| 136 |
+
"""(B, 1, L, L) additive mask enforcing a state -> question -> candidate tree.
|
| 137 |
+
|
| 138 |
+
Three levels, not two:
|
| 139 |
+
|
| 140 |
+
state attends within itself
|
| 141 |
+
question attends to the state and to itself
|
| 142 |
+
candidate attends to the state, to *its own* question, and to itself
|
| 143 |
+
|
| 144 |
+
What the two-level version got wrong is the middle row. With candidates
|
| 145 |
+
hanging straight off the context, a question's wording reached every
|
| 146 |
+
candidate in the request, so the eight questions of a customer-service row
|
| 147 |
+
could see each other's text. Worse, question spans sat unmasked in the
|
| 148 |
+
sequence, which let candidates of question A read question B -- scores then
|
| 149 |
+
depend on which other questions happen to be in the same request, and the
|
| 150 |
+
parallel-sampling guarantee (independent decisions, exact permutation
|
| 151 |
+
invariance) no longer holds.
|
| 152 |
+
|
| 153 |
+
Sibling isolation is the point: two candidates of the same question cannot
|
| 154 |
+
see each other, and two questions of the same state cannot see each other.
|
| 155 |
+
"""
|
| 156 |
+
batch, fields, width, total = option_span.shape
|
| 157 |
+
device = option_span.device
|
| 158 |
+
state = context_span > 0 # (B, L)
|
| 159 |
+
question = field_span > 0 # (B, F, L)
|
| 160 |
+
candidate = option_span > 0 # (B, F, N, L)
|
| 161 |
+
|
| 162 |
+
allow = torch.zeros(batch, total, total, dtype=torch.bool, device=device)
|
| 163 |
+
# state -> state
|
| 164 |
+
allow |= state[:, :, None] & state[:, None, :]
|
| 165 |
+
# question -> state, question -> itself
|
| 166 |
+
q_any = question.any(1)
|
| 167 |
+
allow |= q_any[:, :, None] & state[:, None, :]
|
| 168 |
+
allow |= torch.einsum("bfi,bfj->bij", question.float(), question.float()).bool()
|
| 169 |
+
# candidate -> state
|
| 170 |
+
c_any = candidate.any(1).any(1)
|
| 171 |
+
allow |= c_any[:, :, None] & state[:, None, :]
|
| 172 |
+
# candidate -> its own question (broadcast over that question's candidates)
|
| 173 |
+
own_question = torch.einsum(
|
| 174 |
+
"bfni,bfj->bij", candidate.float(), question.float()
|
| 175 |
+
).bool()
|
| 176 |
+
allow |= own_question
|
| 177 |
+
# candidate -> itself only, never a sibling
|
| 178 |
+
allow |= torch.einsum("bfni,bfnj->bij", candidate.float(), candidate.float()).bool()
|
| 179 |
+
# Padding positions belong to no node in the tree, so every one of their
|
| 180 |
+
# rows would be entirely masked and softmax would divide by zero -- the
|
| 181 |
+
# NaN this produced showed up within 200 steps. Let each position attend
|
| 182 |
+
# to itself; the result is discarded because nothing pools from padding.
|
| 183 |
+
eye = torch.eye(total, dtype=torch.bool, device=device)
|
| 184 |
+
allow |= eye[None, :, :]
|
| 185 |
+
return torch.where(allow, 0.0, torch.finfo(torch.float32).min).unsqueeze(1)
|
| 186 |
+
|
| 187 |
+
def forward(self, batch: dict) -> torch.Tensor:
|
| 188 |
+
# The tree mask, not a plain padding mask: without it every span in the
|
| 189 |
+
# sequence is mutually visible and the per-decision independence this
|
| 190 |
+
# design rests on is lost.
|
| 191 |
+
mask = self.build_mask(
|
| 192 |
+
batch["context_span"], batch["field_span"], batch["option_span"]
|
| 193 |
+
)
|
| 194 |
+
# Padding columns are unreachable, but the diagonal must survive or the
|
| 195 |
+
# padding rows go fully masked again and softmax divides by zero.
|
| 196 |
+
floor = torch.finfo(mask.dtype).min
|
| 197 |
+
total = mask.shape[-1]
|
| 198 |
+
keep = batch["packed_mask"][:, None, None, :] | torch.eye(
|
| 199 |
+
total, dtype=torch.bool, device=mask.device
|
| 200 |
+
)[None, None]
|
| 201 |
+
mask = mask.masked_fill(~keep, floor)
|
| 202 |
+
extra = {}
|
| 203 |
+
if "pixel_values" in batch:
|
| 204 |
+
extra["pixel_values"] = batch["pixel_values"]
|
| 205 |
+
extra["image_grid_thw"] = batch["image_grid_thw"]
|
| 206 |
+
# The processor sizes mm_token_type_ids to the state alone; packing
|
| 207 |
+
# appends questions and candidates, so it is padded with zeros (text)
|
| 208 |
+
# out to the full sequence.
|
| 209 |
+
token_types = batch["mm_token_type_ids"]
|
| 210 |
+
if token_types.shape[1] < total:
|
| 211 |
+
token_types = torch.cat([
|
| 212 |
+
token_types,
|
| 213 |
+
token_types.new_zeros(token_types.shape[0], total - token_types.shape[1]),
|
| 214 |
+
], dim=1)
|
| 215 |
+
extra["mm_token_type_ids"] = token_types[:, :total]
|
| 216 |
+
# M-RoPE derives 3D positions by indexing the attention mask as a 2D
|
| 217 |
+
# (B, L) padding mask. Ours is the 4D additive tree mask, which that
|
| 218 |
+
# code cannot read -- it raised IndexError on attention_mask[b].bool().
|
| 219 |
+
# Compute the positions here from the real padding mask and hand them
|
| 220 |
+
# over, so the encoder skips its own derivation. Position ids are
|
| 221 |
+
# per-token, so the tree mask is irrelevant to them.
|
| 222 |
+
extra["position_ids"] = self.encoder.get_rope_index(
|
| 223 |
+
batch["packed_ids"],
|
| 224 |
+
image_grid_thw=batch["image_grid_thw"],
|
| 225 |
+
attention_mask=batch["packed_mask"].long(),
|
| 226 |
+
mm_token_type_ids=extra["mm_token_type_ids"],
|
| 227 |
+
)[0]
|
| 228 |
+
hidden = self.encoder(
|
| 229 |
+
input_ids=batch["packed_ids"],
|
| 230 |
+
attention_mask=mask,
|
| 231 |
+
**extra,
|
| 232 |
+
).last_hidden_state.float()
|
| 233 |
+
hidden = self.norm(hidden)
|
| 234 |
+
|
| 235 |
+
# Mean-pool the context span and each option span.
|
| 236 |
+
context = (hidden * batch["context_span"].unsqueeze(-1)).sum(1)
|
| 237 |
+
context = context / batch["context_span"].sum(-1, keepdim=True).clamp_min(1)
|
| 238 |
+
query = self.context_proj(context) # (B, r)
|
| 239 |
+
|
| 240 |
+
spans = batch["option_span"] # (B, F, N, L)
|
| 241 |
+
weights = spans.sum(-1, keepdim=True).clamp_min(1)
|
| 242 |
+
pooled = torch.einsum("bfnl,blw->bfnw", spans, hidden) / weights
|
| 243 |
+
keys = self.option_proj(pooled) # (B, F, N, r)
|
| 244 |
+
|
| 245 |
+
# The field's words are pooled from the sequence like everything else,
|
| 246 |
+
# and added to the context query. No per-field parameters exist.
|
| 247 |
+
field = torch.einsum("bfl,blw->bfw", batch["field_span"], hidden)
|
| 248 |
+
field = field / batch["field_span"].sum(-1, keepdim=True).clamp_min(1)
|
| 249 |
+
query = query[:, None, :] + self.context_proj(field) # (B, F, r)
|
| 250 |
+
logits = (query[:, :, None, :] * keys).sum(-1) / self.rank ** 0.5
|
| 251 |
+
return logits.masked_fill(~batch["option_mask"], torch.finfo(logits.dtype).min)
|
| 252 |
+
|
| 253 |
+
|
| 254 |
+
# Registering against the Auto classes, and recording auto_map in config.json, is
|
| 255 |
+
# what makes a saved directory the whole model: someone with transformers and no
|
| 256 |
+
# copy of this package can load it with
|
| 257 |
+
# AutoModel.from_pretrained(path, trust_remote_code=True). These have to run at
|
| 258 |
+
# module import in a real module -- defining the classes in __main__ silently
|
| 259 |
+
# writes auto_map: null and the directory stops being portable.
|
| 260 |
+
AutoConfig.register(PackedScorerConfig.model_type, PackedScorerConfig, exist_ok=True)
|
| 261 |
+
AutoModel.register(PackedScorerConfig, PackedScorer, exist_ok=True)
|
| 262 |
+
PackedScorerConfig.register_for_auto_class()
|
| 263 |
+
PackedScorer.register_for_auto_class("AutoModel")
|
preprocessor_config.json
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"size": {
|
| 3 |
+
"longest_edge": 65536,
|
| 4 |
+
"shortest_edge": 65536
|
| 5 |
+
},
|
| 6 |
+
"patch_size": 16,
|
| 7 |
+
"temporal_patch_size": 2,
|
| 8 |
+
"merge_size": 2,
|
| 9 |
+
"image_mean": [
|
| 10 |
+
0.5,
|
| 11 |
+
0.5,
|
| 12 |
+
0.5
|
| 13 |
+
],
|
| 14 |
+
"image_std": [
|
| 15 |
+
0.5,
|
| 16 |
+
0.5,
|
| 17 |
+
0.5
|
| 18 |
+
],
|
| 19 |
+
"processor_class": "Qwen3VLProcessor",
|
| 20 |
+
"image_processor_type": "Qwen2VLImageProcessorFast"
|
| 21 |
+
}
|
schema.py
ADDED
|
@@ -0,0 +1,178 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Typed decision schemas.
|
| 2 |
+
|
| 3 |
+
A schema declares, in advance, every field a query returns and every value each
|
| 4 |
+
field may take. Type safety is therefore constructive: the model normalises only
|
| 5 |
+
over declared options, so a returned struct cannot name an option that does not
|
| 6 |
+
exist and cannot omit a declared field. Nothing is parsed or validated at
|
| 7 |
+
inference time.
|
| 8 |
+
|
| 9 |
+
Four field kinds cover the shapes decisions actually take:
|
| 10 |
+
|
| 11 |
+
- ``choice`` exactly one of N unordered options (softmax over N)
|
| 12 |
+
- ``bool`` a two-option choice, kept separate so it calibrates on its own
|
| 13 |
+
- ``multi`` any subset of N options (independent sigmoid per option)
|
| 14 |
+
- ``bucket`` one of N *ordered* options, scored with cumulative logits so that
|
| 15 |
+
the order is part of the model rather than an accident of labels
|
| 16 |
+
"""
|
| 17 |
+
|
| 18 |
+
from __future__ import annotations
|
| 19 |
+
|
| 20 |
+
from dataclasses import dataclass
|
| 21 |
+
from typing import Literal
|
| 22 |
+
|
| 23 |
+
Kind = Literal["choice", "bool", "multi", "bucket"]
|
| 24 |
+
KINDS: tuple[Kind, ...] = ("choice", "bool", "multi", "bucket")
|
| 25 |
+
|
| 26 |
+
BOOL_OPTIONS = ("false", "true")
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
@dataclass(frozen=True)
|
| 30 |
+
class Field:
|
| 31 |
+
"""One decision within a schema."""
|
| 32 |
+
|
| 33 |
+
name: str
|
| 34 |
+
kind: Kind = "choice"
|
| 35 |
+
options: tuple[str, ...] = BOOL_OPTIONS
|
| 36 |
+
description: str = ""
|
| 37 |
+
|
| 38 |
+
def __post_init__(self) -> None:
|
| 39 |
+
if not self.name:
|
| 40 |
+
raise ValueError("field name must not be empty")
|
| 41 |
+
if self.kind not in KINDS:
|
| 42 |
+
raise ValueError(f"{self.name}: unknown kind {self.kind!r}, expected one of {KINDS}")
|
| 43 |
+
if self.kind == "bool":
|
| 44 |
+
if self.options != BOOL_OPTIONS:
|
| 45 |
+
raise ValueError(f"{self.name}: bool options are fixed to {BOOL_OPTIONS}")
|
| 46 |
+
elif len(self.options) < 2:
|
| 47 |
+
raise ValueError(f"{self.name}: {self.kind} needs at least two options")
|
| 48 |
+
if len(set(self.options)) != len(self.options):
|
| 49 |
+
raise ValueError(f"{self.name}: options must be unique")
|
| 50 |
+
if any(not option for option in self.options):
|
| 51 |
+
raise ValueError(f"{self.name}: options must not be empty strings")
|
| 52 |
+
|
| 53 |
+
@property
|
| 54 |
+
def cardinality(self) -> int:
|
| 55 |
+
return len(self.options)
|
| 56 |
+
|
| 57 |
+
@property
|
| 58 |
+
def prompt(self) -> str:
|
| 59 |
+
"""The text the model reads to know what this field asks.
|
| 60 |
+
|
| 61 |
+
This is what makes a schema the model never trained on usable: the field
|
| 62 |
+
is identified by its words, not by a row index into a learned table. An
|
| 63 |
+
earlier version stored one trainable vector per field, which meant adding
|
| 64 |
+
a field to a schema raised a shape error and renaming one made the field
|
| 65 |
+
unrecognisable.
|
| 66 |
+
"""
|
| 67 |
+
parts = [self.name.replace("_", " ")]
|
| 68 |
+
if self.description:
|
| 69 |
+
parts.append(self.description)
|
| 70 |
+
parts.append(f"kind: {self.kind}")
|
| 71 |
+
if self.kind != "choice" or len(self.options) <= 8:
|
| 72 |
+
parts.append("options: " + ", ".join(self.options[:8]))
|
| 73 |
+
return " | ".join(parts)
|
| 74 |
+
|
| 75 |
+
@property
|
| 76 |
+
def single(self) -> bool:
|
| 77 |
+
"""True when exactly one option is correct, so the field owns a softmax."""
|
| 78 |
+
return self.kind in ("choice", "bool", "bucket")
|
| 79 |
+
|
| 80 |
+
def index(self, value: str) -> int:
|
| 81 |
+
try:
|
| 82 |
+
return self.options.index(value)
|
| 83 |
+
except ValueError:
|
| 84 |
+
raise ValueError(
|
| 85 |
+
f"{self.name}: {value!r} is not a declared option; expected one of {self.options}"
|
| 86 |
+
) from None
|
| 87 |
+
|
| 88 |
+
def encode(self, value) -> list[int] | int:
|
| 89 |
+
"""Label for one row: an option index, or a 0/1 vector for ``multi``."""
|
| 90 |
+
if self.kind == "bool":
|
| 91 |
+
if not isinstance(value, bool):
|
| 92 |
+
raise ValueError(f"{self.name}: expected a bool, got {value!r}")
|
| 93 |
+
return int(value)
|
| 94 |
+
if self.kind == "multi":
|
| 95 |
+
if isinstance(value, str) or not isinstance(value, (list, tuple, set)):
|
| 96 |
+
raise ValueError(f"{self.name}: multi expects a list of options, got {value!r}")
|
| 97 |
+
chosen = {self.index(item) for item in value}
|
| 98 |
+
return [int(index in chosen) for index in range(self.cardinality)]
|
| 99 |
+
if not isinstance(value, str):
|
| 100 |
+
raise ValueError(f"{self.name}: expected an option string, got {value!r}")
|
| 101 |
+
return self.index(value)
|
| 102 |
+
|
| 103 |
+
def decode(self, probabilities, threshold: float = 0.5):
|
| 104 |
+
"""Probabilities for this field -> the typed value plus its confidence."""
|
| 105 |
+
if len(probabilities) != self.cardinality:
|
| 106 |
+
raise ValueError(
|
| 107 |
+
f"{self.name}: expected {self.cardinality} probabilities, got {len(probabilities)}"
|
| 108 |
+
)
|
| 109 |
+
if self.kind == "multi":
|
| 110 |
+
selected = [option for option, p in zip(self.options, probabilities) if p >= threshold]
|
| 111 |
+
confidence = min((max(p, 1.0 - p) for p in probabilities), default=1.0)
|
| 112 |
+
return selected, float(confidence)
|
| 113 |
+
best = max(range(self.cardinality), key=probabilities.__getitem__)
|
| 114 |
+
value = bool(best) if self.kind == "bool" else self.options[best]
|
| 115 |
+
return value, float(probabilities[best])
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
@dataclass(frozen=True)
|
| 119 |
+
class Schema:
|
| 120 |
+
"""The full set of fields one query returns."""
|
| 121 |
+
|
| 122 |
+
fields: tuple[Field, ...]
|
| 123 |
+
|
| 124 |
+
def __post_init__(self) -> None:
|
| 125 |
+
if not self.fields:
|
| 126 |
+
raise ValueError("a schema needs at least one field")
|
| 127 |
+
names = [field.name for field in self.fields]
|
| 128 |
+
if len(set(names)) != len(names):
|
| 129 |
+
raise ValueError("field names must be unique")
|
| 130 |
+
|
| 131 |
+
def __len__(self) -> int:
|
| 132 |
+
return len(self.fields)
|
| 133 |
+
|
| 134 |
+
def __iter__(self):
|
| 135 |
+
return iter(self.fields)
|
| 136 |
+
|
| 137 |
+
def __getitem__(self, name: str) -> Field:
|
| 138 |
+
for field in self.fields:
|
| 139 |
+
if field.name == name:
|
| 140 |
+
return field
|
| 141 |
+
raise KeyError(name)
|
| 142 |
+
|
| 143 |
+
@property
|
| 144 |
+
def max_cardinality(self) -> int:
|
| 145 |
+
return max(field.cardinality for field in self.fields)
|
| 146 |
+
|
| 147 |
+
def encode(self, values: dict) -> list:
|
| 148 |
+
"""One row of labels, in field order. Every declared field must be present."""
|
| 149 |
+
missing = [field.name for field in self.fields if field.name not in values]
|
| 150 |
+
if missing:
|
| 151 |
+
raise ValueError(f"missing labels for fields: {missing}")
|
| 152 |
+
extra = set(values) - {field.name for field in self.fields}
|
| 153 |
+
if extra:
|
| 154 |
+
raise ValueError(f"labels for undeclared fields: {sorted(extra)}")
|
| 155 |
+
return [field.encode(values[field.name]) for field in self.fields]
|
| 156 |
+
|
| 157 |
+
@property
|
| 158 |
+
def prompts(self) -> tuple[str, ...]:
|
| 159 |
+
return tuple(field.prompt for field in self.fields)
|
| 160 |
+
|
| 161 |
+
def to_json(self) -> dict:
|
| 162 |
+
return {
|
| 163 |
+
"fields": [
|
| 164 |
+
{"name": f.name, "kind": f.kind, "options": list(f.options),
|
| 165 |
+
"description": f.description}
|
| 166 |
+
for f in self.fields
|
| 167 |
+
]
|
| 168 |
+
}
|
| 169 |
+
|
| 170 |
+
@classmethod
|
| 171 |
+
def from_json(cls, payload: dict) -> "Schema":
|
| 172 |
+
return cls(
|
| 173 |
+
tuple(
|
| 174 |
+
Field(item["name"], item.get("kind", "choice"), tuple(item["options"]),
|
| 175 |
+
item.get("description", ""))
|
| 176 |
+
for item in payload["fields"]
|
| 177 |
+
)
|
| 178 |
+
)
|
tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"unk_token": null,
|
| 29 |
+
"video_token": "<|video_pad|>",
|
| 30 |
+
"vision_bos_token": "<|vision_start|>",
|
| 31 |
+
"vision_eos_token": "<|vision_end|>"
|
| 32 |
+
}
|
video_preprocessor_config.json
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"size": {
|
| 3 |
+
"longest_edge": 25165824,
|
| 4 |
+
"shortest_edge": 4096
|
| 5 |
+
},
|
| 6 |
+
"patch_size": 16,
|
| 7 |
+
"temporal_patch_size": 2,
|
| 8 |
+
"merge_size": 2,
|
| 9 |
+
"image_mean": [
|
| 10 |
+
0.5,
|
| 11 |
+
0.5,
|
| 12 |
+
0.5
|
| 13 |
+
],
|
| 14 |
+
"image_std": [
|
| 15 |
+
0.5,
|
| 16 |
+
0.5,
|
| 17 |
+
0.5
|
| 18 |
+
],
|
| 19 |
+
"processor_class": "Qwen3VLProcessor",
|
| 20 |
+
"video_processor_type": "Qwen3VLVideoProcessor"
|
| 21 |
+
}
|