



 | `K6DXAY` | **`K6DXAY` (100%)** | `K6DXAY` (100%) | `K6DxAY` | `x674w7` (0%) |
|
 | `DmS3X` | **`DmS3X` (100%)** | `PxcC` (0%) | `DxP9` (0%) | `p4c4m` (0%) |
|
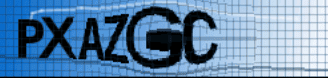
 | `PXAZGC` | **`PXAZSC` (83.3%)** | `PxAzGC` (100% case) | `PXAZCc` (83.3%) | `xw6c` (0%) |
|
 | `JQA3Lg` | **`JQA3LQ` (83.3%)** | `lIJ` (0%) | `J8g` (0%) | `dn86g` (0%) |
|
 | `7yCntT` | `3rem5s` | `ajyGcr` | `7GEr` | `cmcn` |
---
## Comprehensive Benchmark: captCHAD vs. Hugging Face Models
Benchmarked on identical hardware (CPU, 4 threads) across 50 unseen multi-archetype test captchas:
| Model | Architecture | # Parameters | Disk Footprint | Exact Match | Mean Char Acc | CPU Latency |
| :--- | :--- | :---: | :---: | :---: | :---: | :---: |
| **captCHAD (ONNX)** | **Inverted Residuals + BiGRU + CTC** | **97,057** | **582 KB** | **80.0%** (40/50) | **95.00%** | **0.56 ms** |
| **captCHAD (PyTorch)** | **Inverted Residuals + BiGRU + CTC** | **97,057** | **436 KB** | **80.0%** (40/50) | **95.00%** | **3.65 ms** |
| **[Graf-J/captcha-crnn-finetuned](https://huggingface.co/Graf-J/captcha-crnn-finetuned)** | CNN + Bi-LSTM (CRNN) | 3,570,943 (3.57M) | 14.3 MB | 12.0% (6/50) | 58.33% | 16.18 ms |
| **[Graf-J/captcha-conv-transformer](https://huggingface.co/Graf-J/captcha-conv-transformer-finetuned)** | CNN + Transformer Encoder | 12,279,551 (12.3M) | 51.7 MB | 10.0% (5/50) | 58.90% | 18.22 ms |
| **[tomofi/trocr-captcha](https://huggingface.co/tomofi/trocr-captcha)** | TrOCR (Vision Transformer) | 61,596,672 (61.6M) | 246.5 MB | 0.0% (0/50) | 15.67% | 564.51 ms |
### Architectural Observations
- **TrOCR (61.6M params):** Autoregressive Vision Transformers trained primarily on clean documents lack inductive edge bias. When facing crossing strike-bars, non-linear waves, or bulge grids, the attention mechanism loses positional alignment and hallucinates, resulting in 0% exact match and 564 ms latency.
- **CRNN and Conv-Transformer (3.6M–12.3M params):** Standard convolutional backbones without edge-separation stages fuse background grid lines and noise specks into character activations, resulting in 10%–12% exact match on multi-archetype noise.
- **captCHAD (97k params):** Uses a pre-convolutional Contrast Stem (normalized luminance and directional Sobel gradients) and Squeeze-and-Excitation channel gating to isolate glyph contours from background clutter, maintaining 80% exact match with significantly lower compute requirements.
---
## Quantization Formats & Benchmark
To support different deployment environments (WASM browsers, microcontrollers, embedded Linux, server inference), captCHAD is provided in multiple precision formats:
| Format / File | Precision | Disk Size | Exact Match | Mean Char Acc | Single-Sample Latency | Profile / Recommendation |
| :--- | :--- | :---: | :---: | :---: | :---: | :--- |
| **`captchad.onnx`** | FP32 | **582 KB** | **80.0%** | **94.00%** | **1.03 ms** (0.56 ms raw) | **Fastest CPU Execution** (Production standard) |
| **`model_fp16.safetensors`** | FP16 | **206 KB** | **80.0%** | **94.00%** | 5.61 ms | **Optimal Balance** (50% size reduction, 0% accuracy loss) |
| **`captchad_fp16.onnx`** | FP16 | **395 KB** | **80.0%** | **94.00%** | 5.75 ms | **Balanced ONNX** (Half-precision graph) |
| **`captchad_int8.pt`** | INT8 | **320 KB** | **80.0%** | **94.00%** | 6.13 ms | **Quantized PyTorch** (Integer dynamic weights) |
| **`captchad_int8.onnx`** | INT8 | **412 KB** | 72.0% | 90.67% | 5.26 ms | **Edge Hardware** (Integer quantized graph) |
| **`model_fp8.safetensors`** | FP8 (`e4m3fn`) | **110 KB** | 68.0% | 91.33% | 5.68 ms | **Ultra-Compact** (72% size reduction, solid accuracy) |
| **`model_int4.safetensors`** | INT4 Packed | **72 KB** | 4.0% | 41.30% | 5.63 ms | **Extreme Compression** (Experimental 4-bit packaging) |
---
## Architecture Details
```
Input Image (3 x 64 x 192)
│
▼
[Contrast Stem] ──> Extracts Normalized Luminance + Sobel Spatial Gradients (Sobel-X & Sobel-Y)
│
▼
[MobileNet Inverted Residual Blocks] ──> Depthwise-Separable Convolutions + Squeeze-and-Excitation
│
▼
[Height Pooling] ──> Vertical feature compression: (B, 52, 48)
│
▼
[Bidirectional GRU] ──> Horizontal temporal sequence modeling
│
▼
[CTC Sequence Decoder] ──> Arbitrary-length prediction without segmentation
```
- **Input Dimensions:** `(B, 3, 64, 192)`
- **Output Dimensions:** `(48, B, 63)` (Logits for CTC Loss, sequence length $T=48$)
- **Output Character Length:** 1 to 8 characters per image (optimized for 4–7 character CAPTCHAs)
- **Character Vocabulary:** `0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ` (62 alphanumeric classes + 1 CTC blank token at index 0)
- **Trainable Parameters:** `97,057`
---
## Quick Start
### 1. ONNX Runtime Inference
Requires `onnxruntime`, `numpy`, and `pillow`:
```python
import numpy as np
from PIL import Image
import onnxruntime as ort
# Supports captchad.onnx (FP32), captchad_int8.onnx (INT8), captchad_fp16.onnx (FP16)
session = ort.InferenceSession("captchad.onnx")
input_name = session.get_inputs()[0].name
CHARSET = "0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ"
IDX2CHAR = {i + 1: ch for i, ch in enumerate(CHARSET)}
# Preprocess image to [1, 3, 64, 192] normalized in [-1.0, 1.0]
img = Image.open("sample.png").convert("RGB").resize((192, 64), Image.BILINEAR)
arr = (np.array(img, dtype=np.float32).transpose(2, 0, 1) - 127.5) / 127.5
inp = arr[np.newaxis, :, :, :]
# Run inference
logits = session.run(None, {input_name: inp})[0]
preds = np.argmax(logits[:, 0, :], axis=-1)
# CTC Collapse
decoded, prev = [], None
for t in preds:
if t != prev and t != 0:
decoded.append(IDX2CHAR[t])
prev = t
print("Prediction:", "".join(decoded))
```
### 2. Safetensors and PyTorch Inference
```python
import torch
from safetensors.torch import load_file
from model import captCHAD, decode_tokens
from PIL import Image
import numpy as np
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model = captCHAD()
# Load weights (supports model.safetensors, model_fp16.safetensors, model_fp8.safetensors)
state_dict = load_file("model_fp16.safetensors")
state_dict = {k: v.to(torch.float32) if v.is_floating_point() else v for k, v in state_dict.items()}
model.load_state_dict(state_dict)
model.to(device)
model.eval()
img = Image.open("sample.png").convert("RGB").resize((192, 64), Image.BILINEAR)
arr = (np.array(img, dtype=np.float32).transpose(2, 0, 1) - 127.5) / 127.5
tensor = torch.from_numpy(arr).unsqueeze(0).to(device)
with torch.no_grad():
logits = model(tensor)
preds = logits.argmax(dim=-1)[:, 0].tolist()
text = decode_tokens(preds)
print("Prediction:", text)
```
### 3. Command-Line Inference
Test different engines and quantization formats directly via `inference.py`:
```bash
# Fastest CPU production baseline (ONNX FP32)
python inference.py sample.png --engine onnx --quant fp32
# Balanced half-precision (ONNX FP16, 395 KB)
python inference.py sample.png --engine onnx --quant fp16
# Dynamic integer quantization (ONNX INT8, 412 KB)
python inference.py sample.png --engine onnx --quant int8
# Compact half-precision (Safetensors FP16, 206 KB)
python inference.py sample.png --engine safetensors --quant fp16
# Ultra-compact 8-bit float (Safetensors FP8, 110 KB)
python inference.py sample.png --engine safetensors --quant fp8
# Extreme 4-bit packed weights (Safetensors INT4, 72 KB)
python inference.py sample.png --engine safetensors --quant int4
```
---
## License
This project is licensed under the Apache 2.0 License.